jackf857/llama-3-8b-base-new-dpo-ultrafeedback-4xh200-batch-128-q_t-0.5-s_star-0.5-20260429-032138-margin
收藏资源简介:
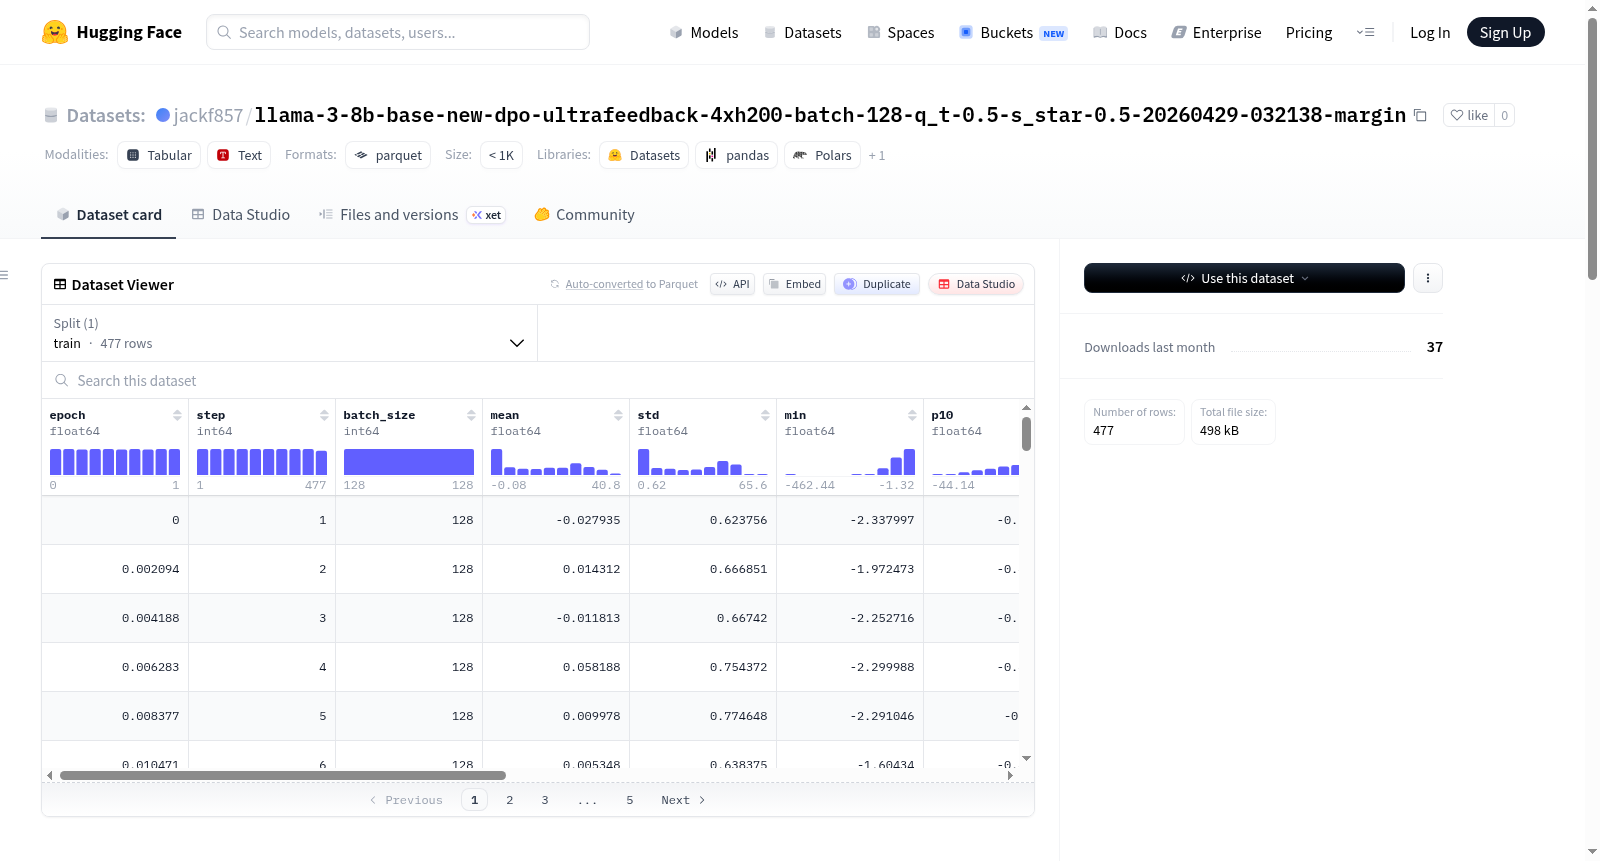
该数据集是从一个New-DPO训练运行中导出的每步边缘摘要统计。数据集包含477个训练样本,每个样本包含epoch、step、batch_size、mean、std、min、p10、median、p90、max、pos_frac、sample和npy等特征。数据集的来源运行基于模型repo id: jackf857/llama-3-8b-base-new-dpo-ultrafeedback-4xh200-batch-128-q_t-0.5-s_star-0.5-20260429-032138,基础模型为/scratch/qu.yang1/dynamic-dpo-v4/base_models/llama-3-8b-base-sft-ultrachat-8xh200。训练参数包括beta=0.01、f_divergence_type=reverse_kl、f_alpha_divergence_coef=1.0、s_star=0.5、eta=0.1和q_t=0.5。数据集混合器使用了HuggingFaceH4/ultrafeedback_binarized数据集,比例为1.0。
Per-step margin summary statistics exported from a New-DPO training run. The dataset contains 477 training examples, each with features such as epoch, step, batch_size, mean, std, min, p10, median, p90, max, pos_frac, sample, and npy. The source run is based on the model repo id: jackf857/llama-3-8b-base-new-dpo-ultrafeedback-4xh200-batch-128-q_t-0.5-s_star-0.5-20260429-032138, with the base model /scratch/qu.yang1/dynamic-dpo-v4/base_models/llama-3-8b-base-sft-ultrachat-8xh200. Training arguments include beta=0.01, f_divergence_type=reverse_kl, f_alpha_divergence_coef=1.0, s_star=0.5, eta=0.1, and q_t=0.5. The dataset mixer uses HuggingFaceH4/ultrafeedback_binarized with a ratio of 1.0.