sijieli/scalebench
收藏资源简介:
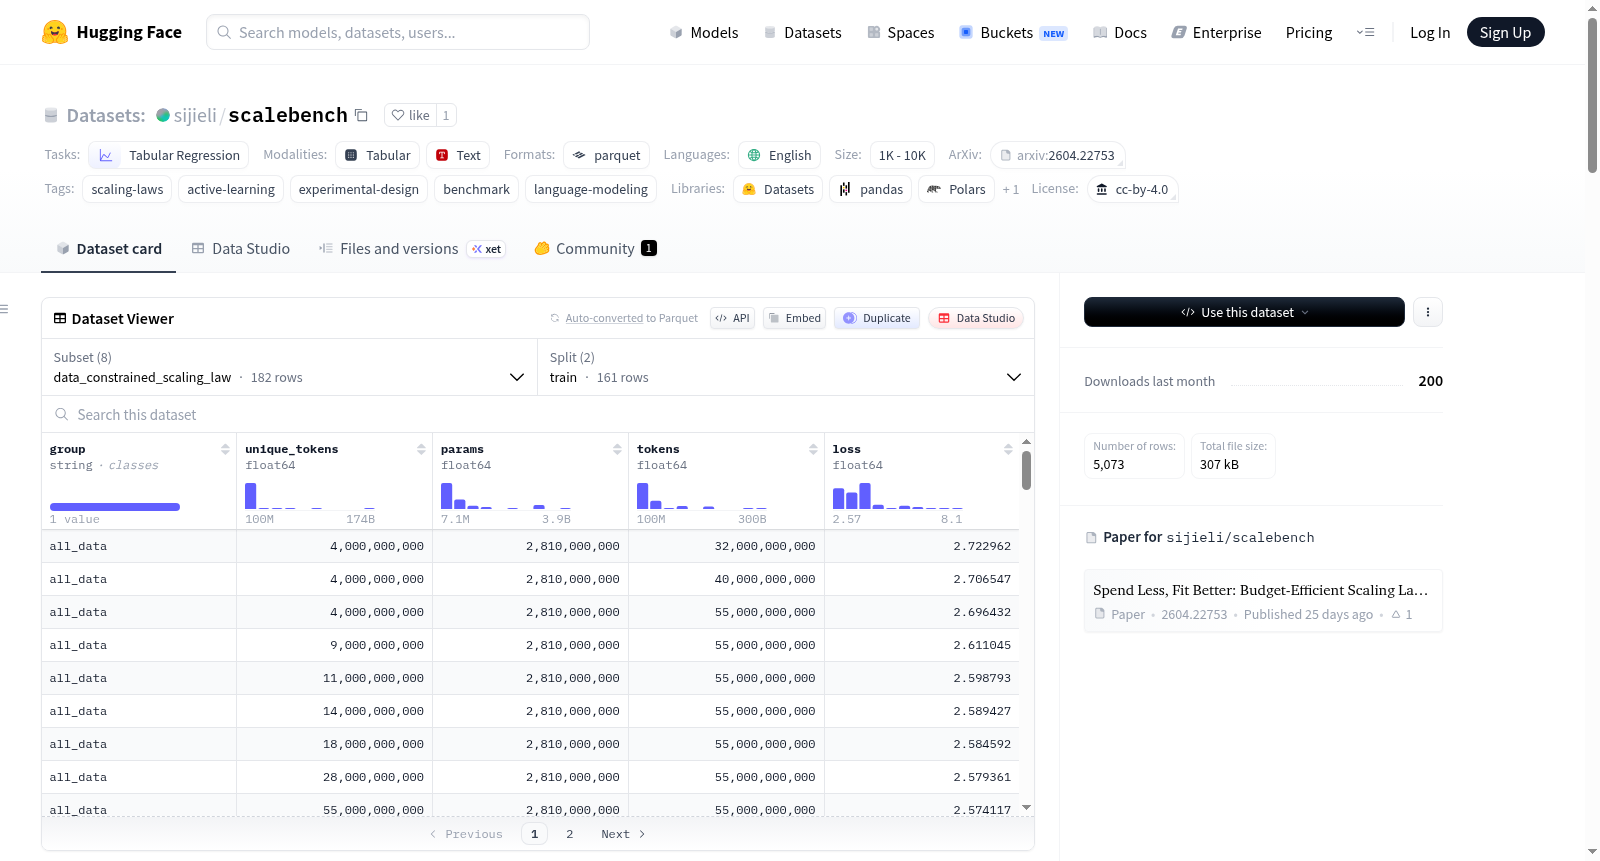
该数据集是一个预算高效缩放定律拟合基准,包含8个表格回归任务和65个缩放定律实例。这些任务覆盖了语言模型缩放设置中的多种场景,包括预训练超参数调整、数据分配、词汇设计、领域混合优化、混合专家设计、稀疏性、并行/推理时间缩放以及Farseer风格的密集预训练缩放。每个任务都存储为单独的Hugging Face配置,包含训练和测试分割。数据集旨在评估在预算约束下进行实验选择和主动实验设计的方法,用于缩放定律拟合。
This dataset is a budget-efficient scaling law fitting benchmark containing 8 tabular regression tasks and 65 scaling-law instances. The tasks cover language-model scaling settings including pre-training hyperparameter tuning, data allocation, vocabulary design, domain mixture optimization, mixture-of-experts design, sparsity, parallel/inference-time scaling, and Farseer-style dense pre-training scaling. Each task is stored as a separate Hugging Face configuration with train and test splits. The benchmark is designed for evaluating experiment-selection and active experimental-design methods for scaling-law fitting under budget constraints.