V2V-QA
收藏资源简介:
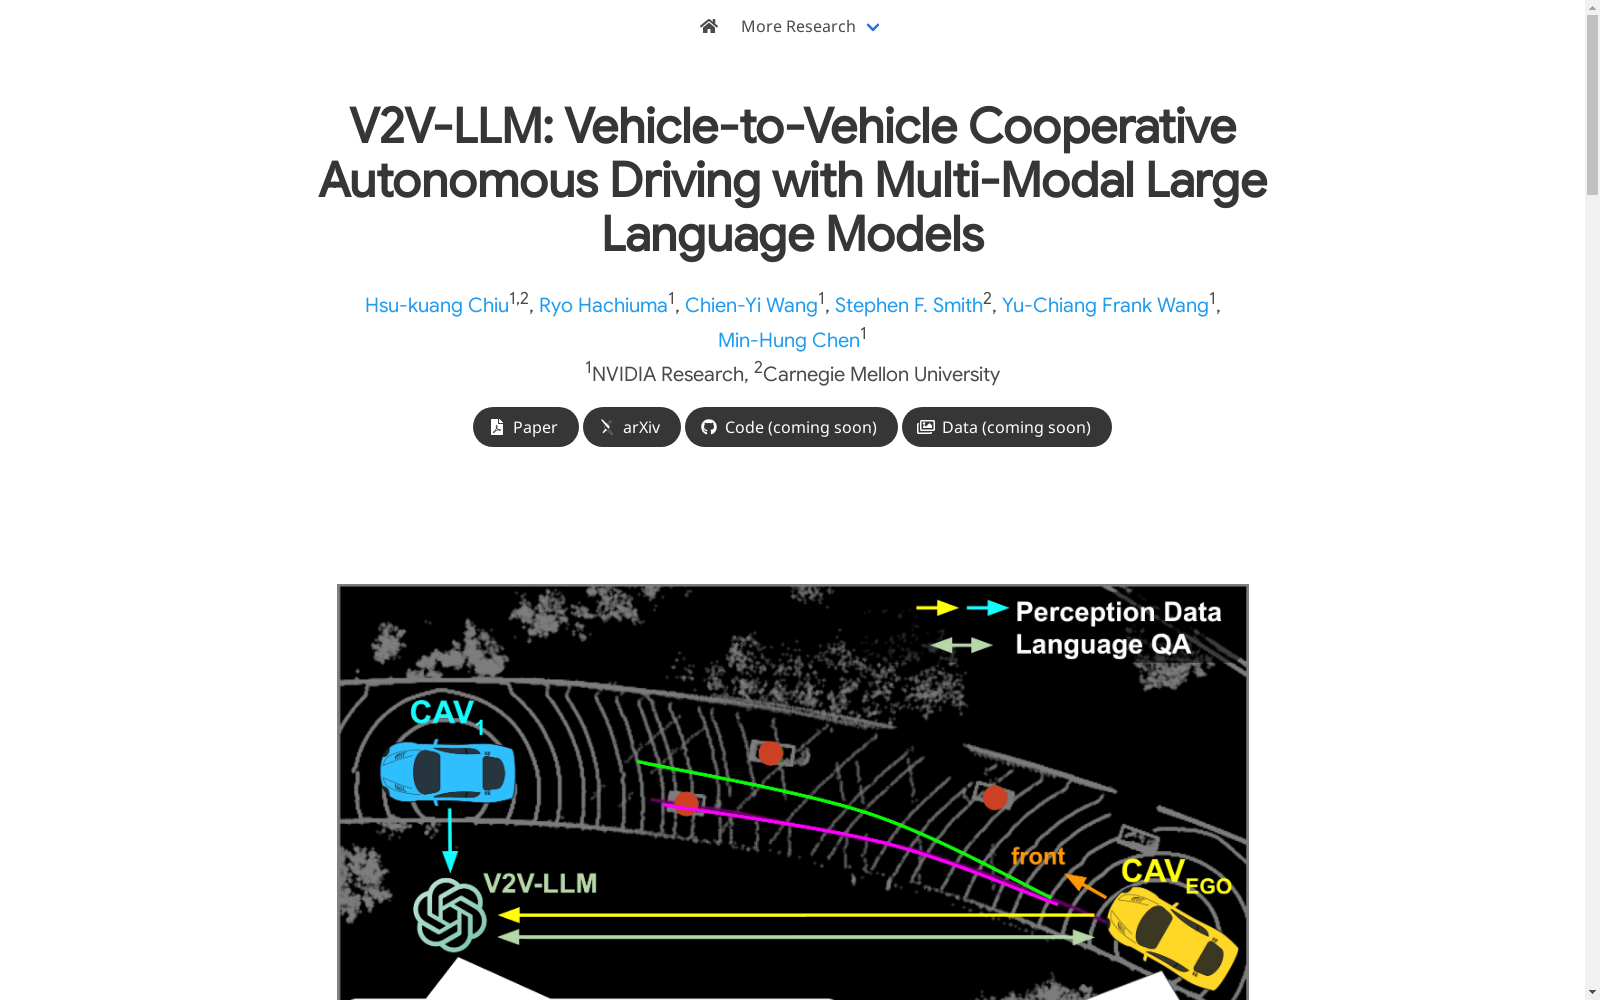
V2V-QA数据集是由NVIDIA和卡内基梅隆大学合作创建的,旨在支持大型语言模型在合作自动驾驶中的研究和评估。该数据集在V2V4Real的基础上构建,包含18,000个帧,共有577,000个问答对,涵盖定位、显著物体识别和规划任务。数据集通过车辆间的感知信息共享,提出了新的合作自动驾驶场景下的问答任务,以评估模型在融合多车感知信息和回答驾驶安全相关问题的能力。
The V2V-QA dataset was collaboratively developed by NVIDIA and Carnegie Mellon University to support research and evaluation of large language models (LLMs) in cooperative autonomous driving scenarios. Built upon the V2V4Real dataset, it contains 18,000 frames and a total of 577,000 question-answer pairs, covering localization, salient object recognition, and planning tasks. By leveraging inter-vehicle perception information sharing, this dataset proposes novel question-answering tasks under cooperative autonomous driving scenarios, aiming to evaluate models' capability to fuse multi-vehicle perception information and answer driving safety-related questions.