Perceive Anything Model (PAM) 数据集
收藏资源简介:
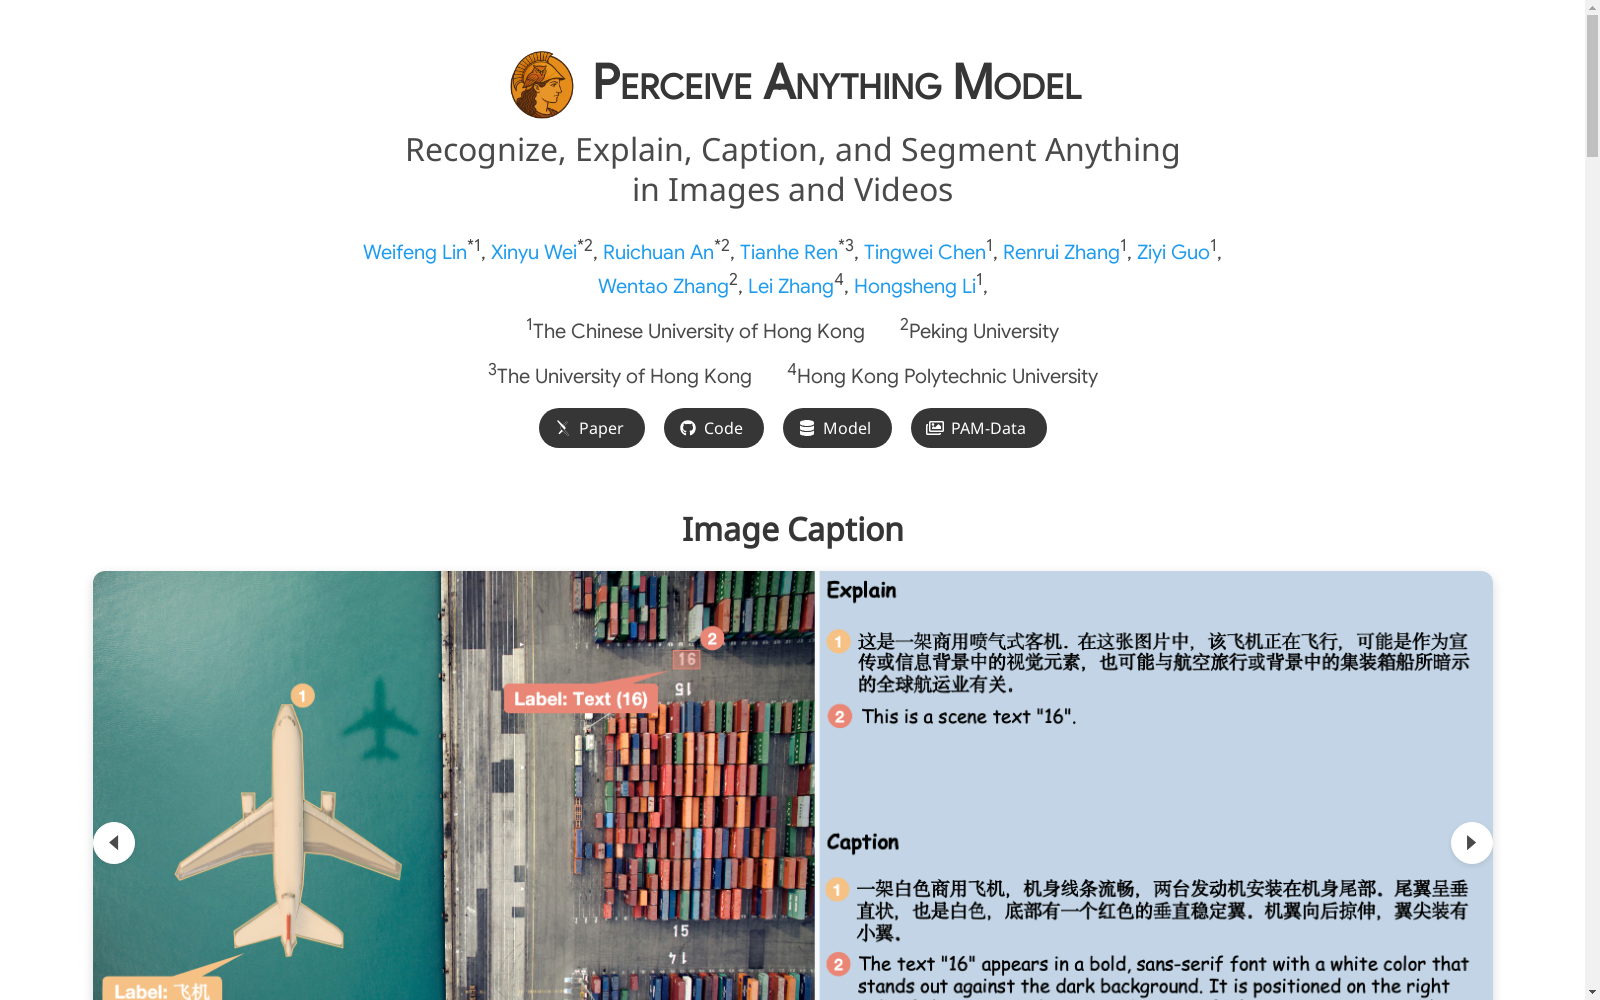
该数据集名为Perceive Anything Model (PAM) 数据集,由香港中文大学、香港大学、香港理工大学和北京大学的研究团队创建。数据集包含150万个图像和视频区域语义标注,涵盖了丰富的视觉特征、定位和语义先验信息。数据集的创建过程使用了先进的视觉语言模型(如GPT-4o)和人工专家验证,以确保高质量和多样性。该数据集旨在解决图像和视频中的区域理解问题,如预测类别、解释定义和功能,以及生成详细描述。数据集支持多语言响应,包括英语和中文版本。
This dataset, named the Perceive Anything Model (PAM) Dataset, was developed by research teams from The Chinese University of Hong Kong, The University of Hong Kong, The Hong Kong Polytechnic University, and Peking University. It contains 1.5 million semantic annotations for image and video regions, covering rich visual features, localization information, and semantic prior knowledge. The construction of this dataset utilized cutting-edge vision-language models (e.g., GPT-4o) and underwent manual expert verification to guarantee high quality and diversity. This dataset aims to address regional understanding tasks in images and videos, such as category prediction, definition and function explanation, and detailed description generation. It supports multilingual responses, including English and Chinese versions.