
IR-Plag
收藏arXiv2025-09-30 收录
官方服务:
资源简介:
该数据集名为IR-Plag,旨在为代码相似度检测技术提供基准测试,其中包含了模拟学术抄袭模式的代码文件,具有多种复杂度。该数据集共包含467个代码文件,总计59,201个标记,其中355个被标记为抄袭。数据集规模较小,适用于代码相似度评估和抄袭检测任务。
The dataset, named IR-Plag, is developed as a benchmark for code similarity detection technologies. It encompasses code files that simulate academic plagiarism patterns with diverse complexity levels. In total, this dataset contains 467 code files and 59,201 tokens in all, out of which 355 are labeled as plagiarized. With a modest scale, IR-Plag is applicable to code similarity evaluation and plagiarism detection tasks.
提供机构:
Oscar Karnalim搜集汇总
数据集介绍
背景与挑战
背景概述
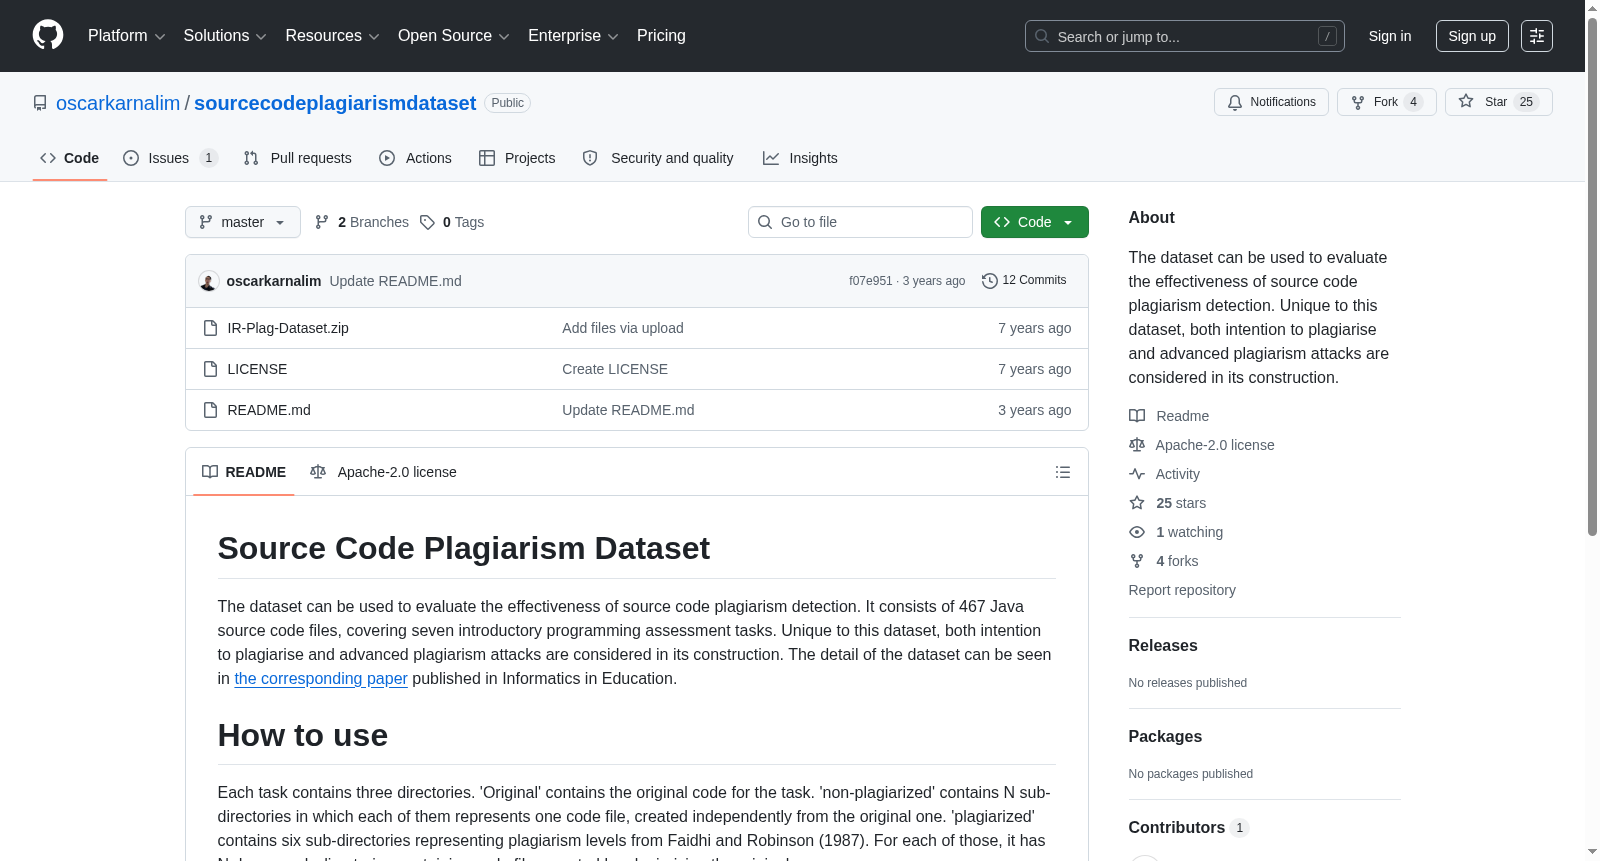
IR-Plag是一个用于评估源代码抄袭检测有效性的数据集,包含467个Java源文件,覆盖七个入门编程任务。其独特之处在于同时考虑了抄袭意图和高级抄袭攻击,并基于Faidhi和Robinson(1987)的六个级别构建抄袭样本,为研究提供了全面且结构化的测试资源。
以上内容由遇见数据集搜集并总结生成


