CCB/cis5300-word-embeddings
收藏资源简介:
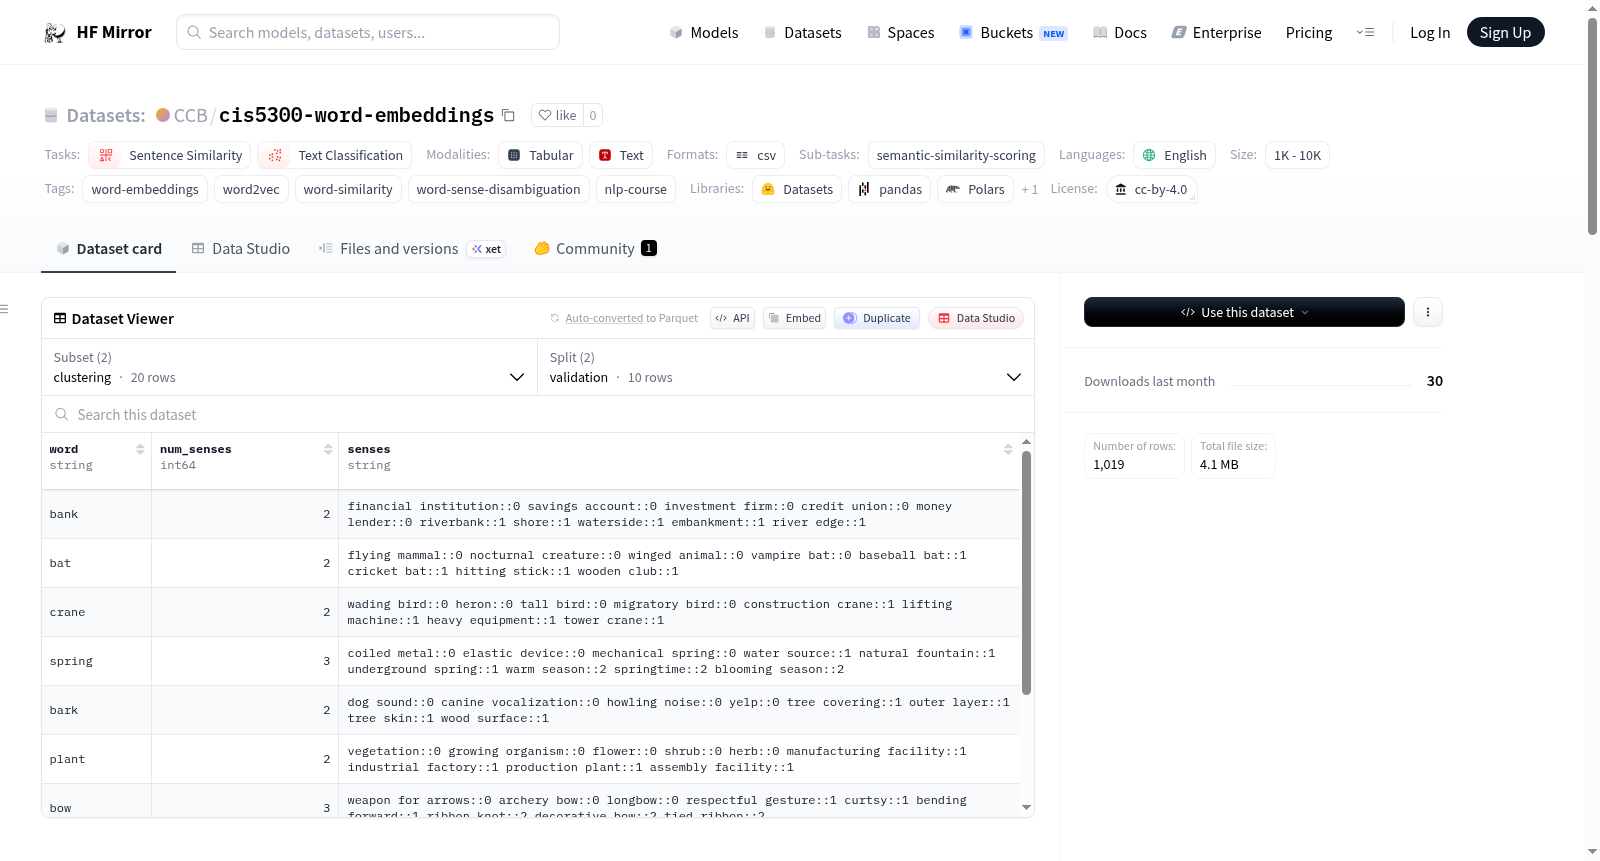
该数据集支持学习词嵌入(捕捉词义的密集向量表示)。它包含一个标准的相似性基准(SimLex-999)、一个词义消歧任务(Word Sense Clustering)以及用于训练自定义词嵌入的莎士比亚语料库。SimLex-999是一个专门测量语义相似性的黄金标准基准,不同于WordSim-353(它将相似性与相关性混为一谈)。Word Sense Clustering包含多义词及其意义,用于评估词嵌入是否能区分词的不同意义。数据集还包含莎士比亚剧本的文本文件和预计算的共现向量,用于训练和评估词嵌入模型。该数据集用于宾夕法尼亚大学自然语言处理课程(CIS 5300)的作业,学生需训练词嵌入模型、探索词类比和向量运算、评估词嵌入在SimLex-999上的表现、聚类多义词意义以及研究词嵌入中的偏见。
This dataset supports learning about word embeddings — dense vector representations that capture word meaning. It includes a standard similarity benchmark (SimLex-999), a word sense disambiguation task (Word Sense Clustering), and a Shakespeare corpus for training custom embeddings. SimLex-999 is a gold-standard benchmark for evaluating word embeddings, specifically measuring semantic similarity (unlike WordSim-353 which conflates similarity with relatedness). Word Sense Clustering contains polysemous words and their senses, for evaluating whether embeddings can distinguish word senses. The dataset also includes Shakespeare plays and pre-computed co-occurrence vectors for training and evaluating word embeddings. The dataset is used for Homework 4 in CIS 5300: Natural Language Processing at the University of Pennsylvania, where students train Word2Vec embeddings, explore word analogies and vector arithmetic, evaluate embeddings on SimLex-999, cluster polysemous word senses, and investigate bias in word embeddings.