celsowm/srp-gpt2-ptbr-corpus
收藏资源简介:
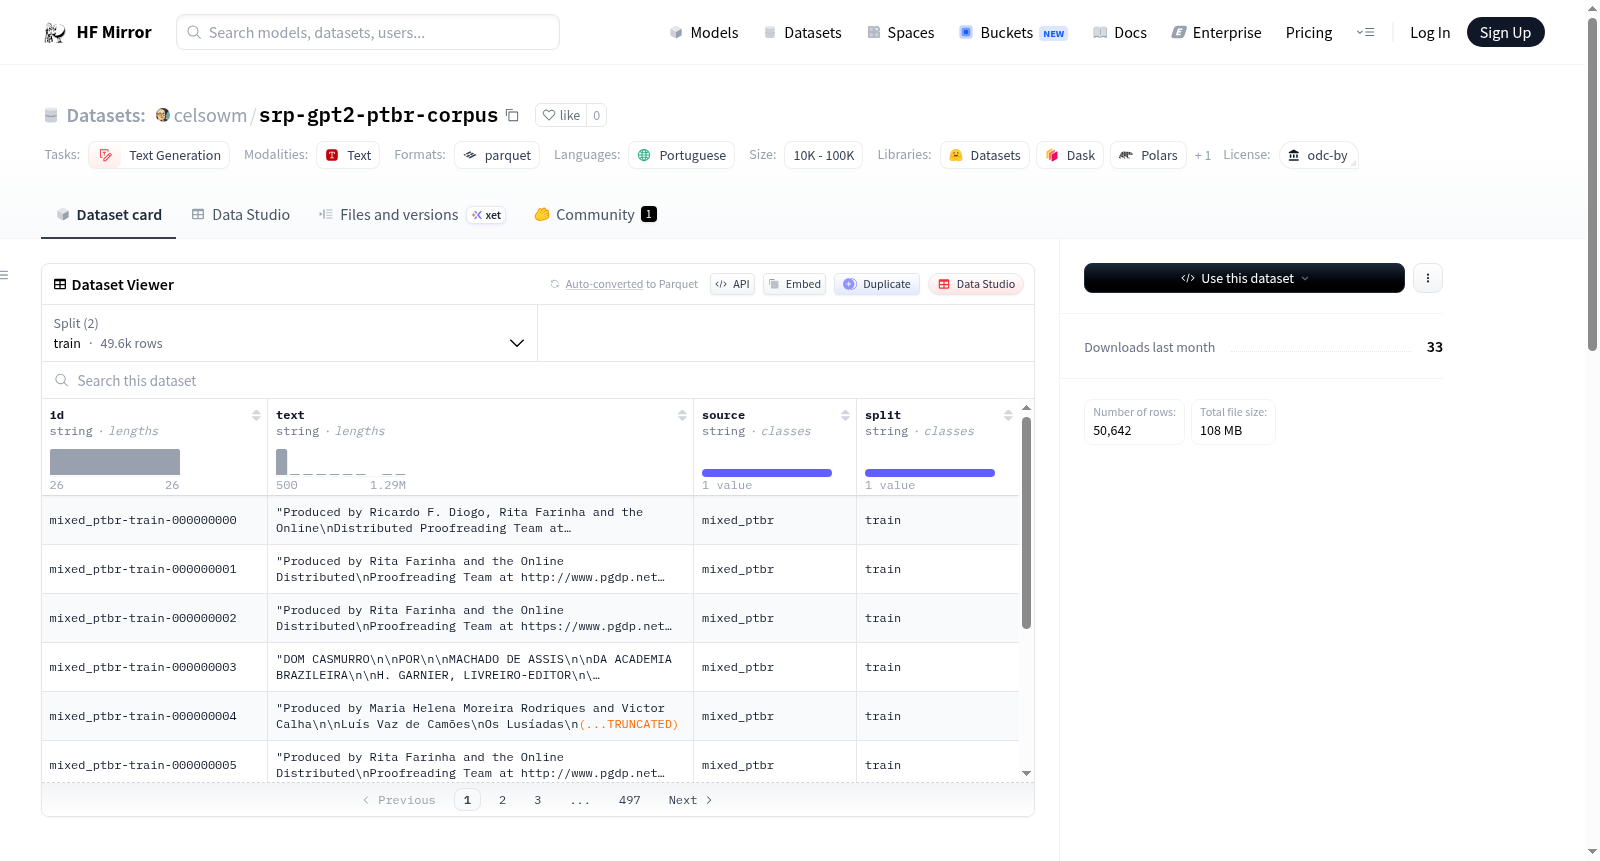
SRP GPT-2 PT-BR Corpus是一个用于葡萄牙语(pt-BR)自回归语言模型训练的公开语料库。该数据集由Project Gutenberg和FineWeb2的公开文本组成,包含49,610个训练文档和1,032个验证文档。数据集中的每一行包含一个稳定的文档标识符(id)、UTF-8编码的文本内容(text)、语料库来源标签(source)以及数据分割标签(split)。使用该数据集时需遵守原始来源的许可条款,特别是FineWeb2的ODC-By 1.0许可证要求归属。
SRP GPT-2 PT-BR Corpus is a public corpus in Parquet format for autoregressive training of language models in Portuguese (pt-BR). This dataset is a composition of public/reproducible texts, with attribution to original sources: Project Gutenberg (accessed via Gutendex API) and FineWeb2 from Hugging Face (filtered for Portuguese/pt-BR). It contains 49,610 training documents and 1,032 validation documents. Each row includes a stable document identifier (id), UTF-8 encoded text content (text), corpus source label (source), and data split label (split). Usage of this dataset requires compliance with the original sources licensing terms, particularly the ODC-By 1.0 license for FineWeb2 which requires attribution.