alexliap/greek-synth-v1
收藏资源简介:
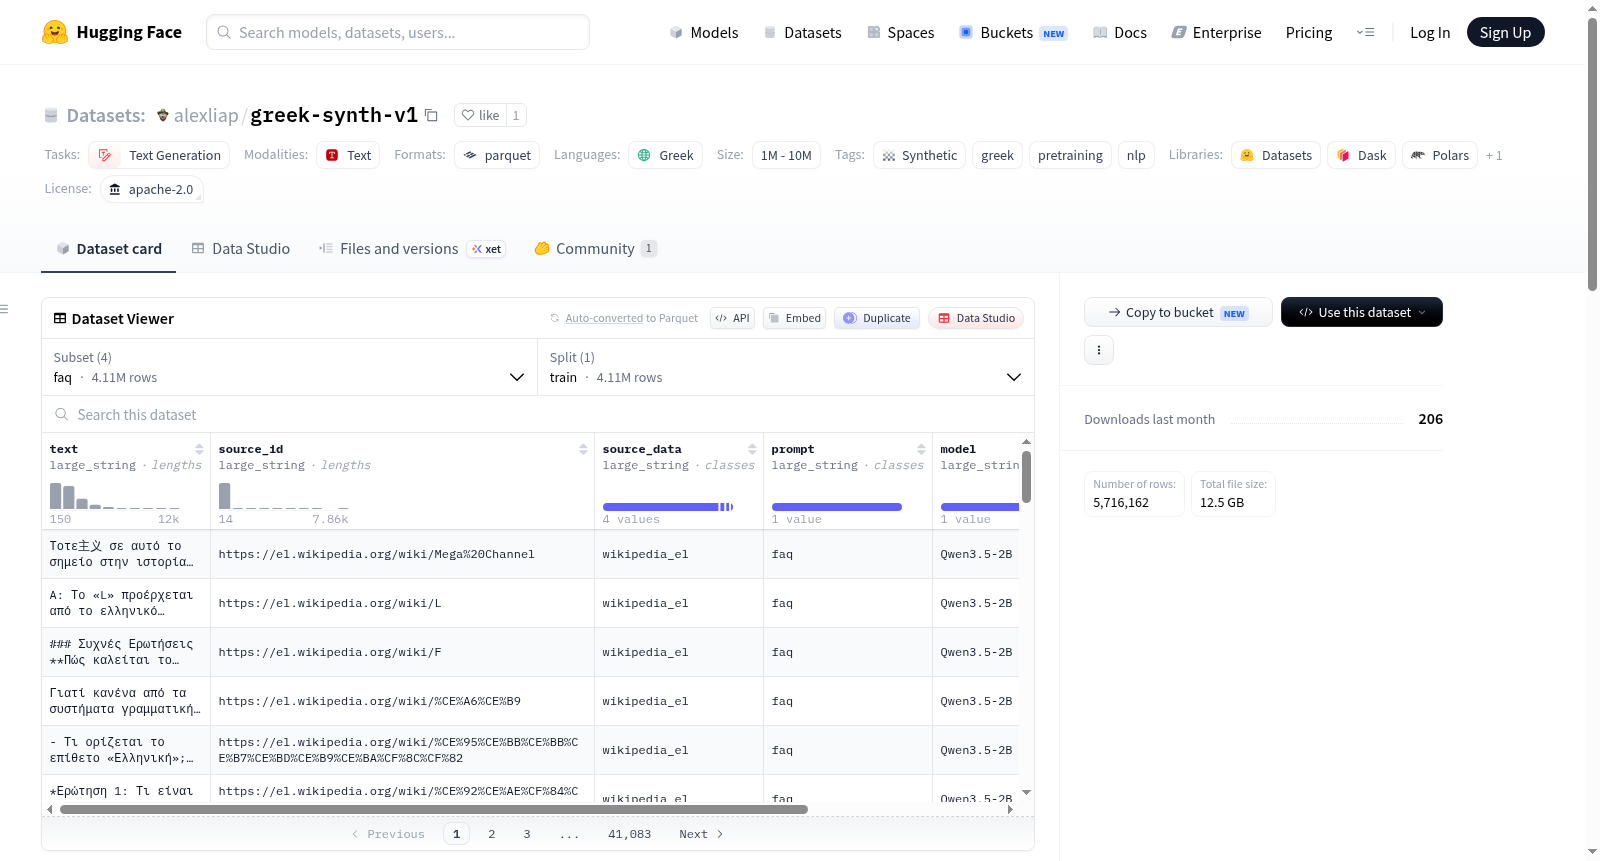
这是一个希腊语合成预训练数据集,通过使用四种教学丰富的提示格式(FAQ、数学、表格、教程)对源文档进行重述生成。数据集基于源语料库“alexliap/high-quality-gr-text”生成,每个配置单独重述并合并到相同的提示子目录中,源数据信息保存在每行的“source_data”列中。生成过程使用Lightning AI基础设施,通过Qwen/Qwen3.5-2B模型在vLLM端点上进行重述,数据以parquet分片形式存储。数据集包括文本、源ID、源数据配置、提示类型、模型信息和语言置信度等列。
Greek synthetic pre-training data produced by rephrasing source documents through four pedagogically rich prompt formats (FAQ, Math, Table, Tutorial). The dataset is generated from the source corpus alexliap/high-quality-gr-text, with each config rephrased separately and merged into the same prompt subdirectories, and the originating config preserved in the source_data column. Generation uses Lightning AI infrastructure, with the rephrasing model Qwen/Qwen3.5-2B served through a vLLM endpoint, and data is stored in parquet shards. The schema includes columns for text, source ID, source data config, prompt type, model information, and language confidence.