ghananlpcommunity/ghana-corpus
收藏资源简介:
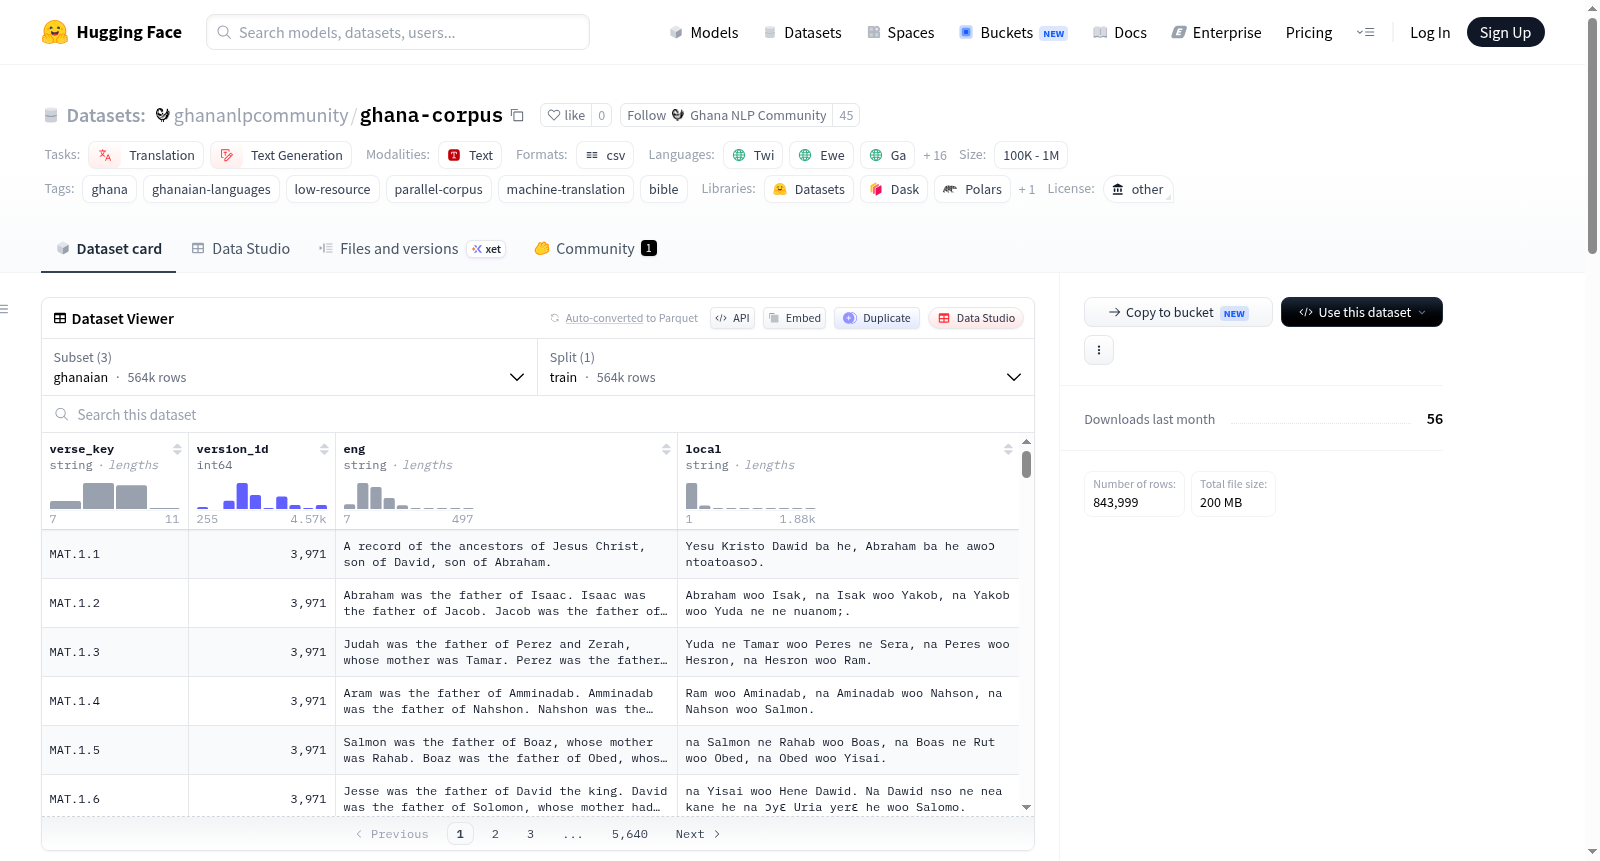
Ghana Corpus是一个包含加纳语言(如Twi、Ewe、Gaa、Dag、Fanti、Adangme、Gonja、Dagaare、Nzema、Abron等)以及多种世界语言(如英语、法语、西班牙语、葡萄牙语、德语、意大利语、阿拉伯语、中文、斯瓦希里语)的经文对齐文本数据集。该数据集用于构建平行语料库和单语语料库,所有语言通过共享的经文键(例如JHN.3.16)对齐,支持加纳语与英语(英语为默认配对语言)、加纳语之间、加纳语与其他语言的对齐,以及任何单一语言的单语语料库。数据来源于公开的圣经翻译文本,从YouVersion获取,并分为三个配置:ghanaian(包含经文键、版本ID、英语文本和本地语言文本)、english(包含经文键和英语文本)和reference(包含经文键、版本ID、语言代码和文本)。数据集旨在支持低资源语言处理、机器翻译和文本生成任务,由Ghana NLP社区构建。
Ghana Corpus is a verse-aligned text dataset for Ghanaian languages (such as Twi, Ewe, Gaa, Dag, Fanti, Adangme, Gonja, Dagaare, Nzema, Abron) plus several world languages (including English, French, Spanish, Portuguese, German, Italian, Arabic, Chinese, Swahili). It is designed for building parallel and monolingual corpora, with all languages aligned on a shared verse key (e.g., JHN.3.16), enabling Ghanaian ↔ English (default pair), Ghanaian ↔ Ghanaian, Ghanaian ↔ other language alignments, and monolingual corpora for any single language. The text is derived from public Bible translations retrieved from YouVersion, and the dataset is split into three configs: ghanaian (with columns: verse_key, version_id, eng, local), english (verse_key, eng), and reference (verse_key, version_id, lang_code, text). It supports low-resource language processing, machine translation, and text generation tasks, built by the Ghana NLP Community.