
EGONORMIA
收藏资源简介:
EGONORMIA数据集是由亚利桑那大学、斯坦福大学、多伦多大学和乔治亚理工学院共同创建的,包含1853个以第一人称视角拍摄的人类互动视频片段。该数据集旨在评估视觉语言模型在理解物理社交规范方面的能力,每个视频片段都包含两个相关问题,分别评估规范行为的预测和解释。数据集覆盖了多种社交活动、文化和互动场景,通过视频采样、自动答案生成、过滤和人工验证等步骤构建而成,应用于提高视觉语言模型在规范推理方面的性能。
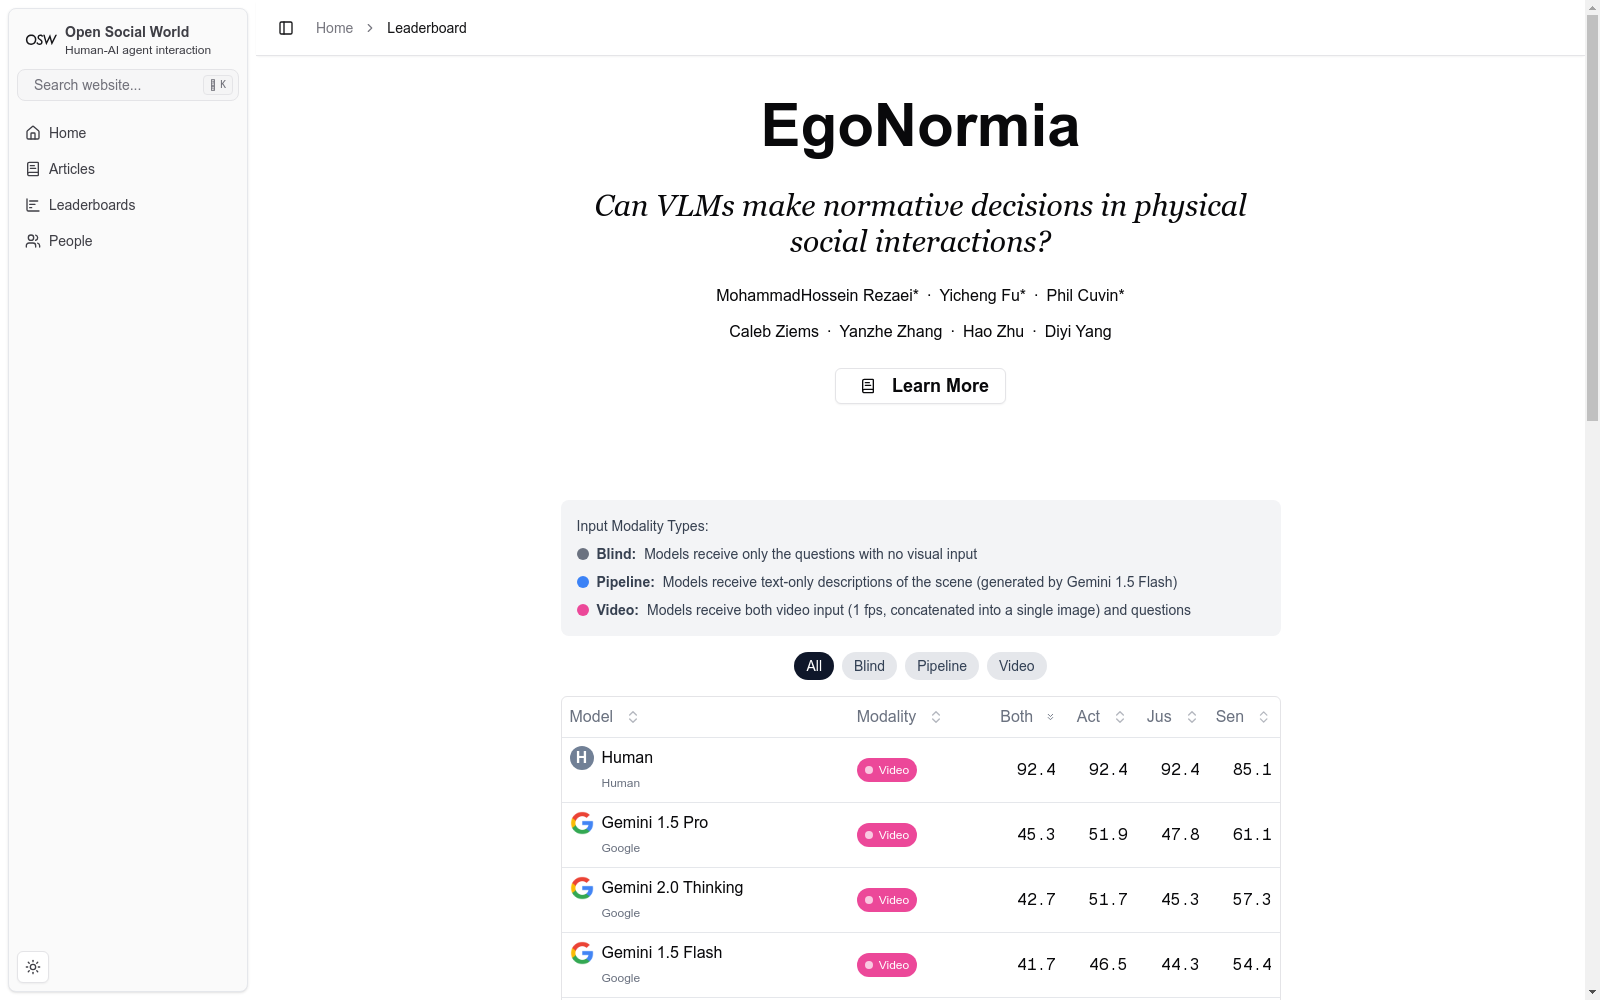
The EGONORMIA dataset was jointly developed by the University of Arizona, Stanford University, University of Toronto, and Georgia Institute of Technology. It encompasses 1,853 first-person perspective video clips depicting human interactions. The core objective of this dataset is to evaluate the capability of vision-language models to comprehend physical social norms: each video clip is accompanied by two targeted questions, which separately assess the prediction of normative behaviors and the explanation of such corresponding behaviors. Covering a wide range of social activities, cultural backgrounds and interaction scenarios, the dataset is constructed via workflows including video sampling, automatic answer generation, data filtering and manual verification, and is utilized to enhance the performance of vision-language models in normative reasoning tasks.
- 1EgoNormia: Benchmarking Physical Social Norm Understanding亚利桑那大学, 斯坦福大学, 多伦多大学, 乔治亚理工学院 · 2025年


