ChartCap
收藏资源简介:
ChartCap是一个大规模的数据集,包含565K个现实世界图表图像及其对应的类型特定、密集型描述。这些描述去除了无关信息,详细突出了图表的结构元素和关键洞察。数据集分为训练集和测试集,适用于图像到文本的任务。
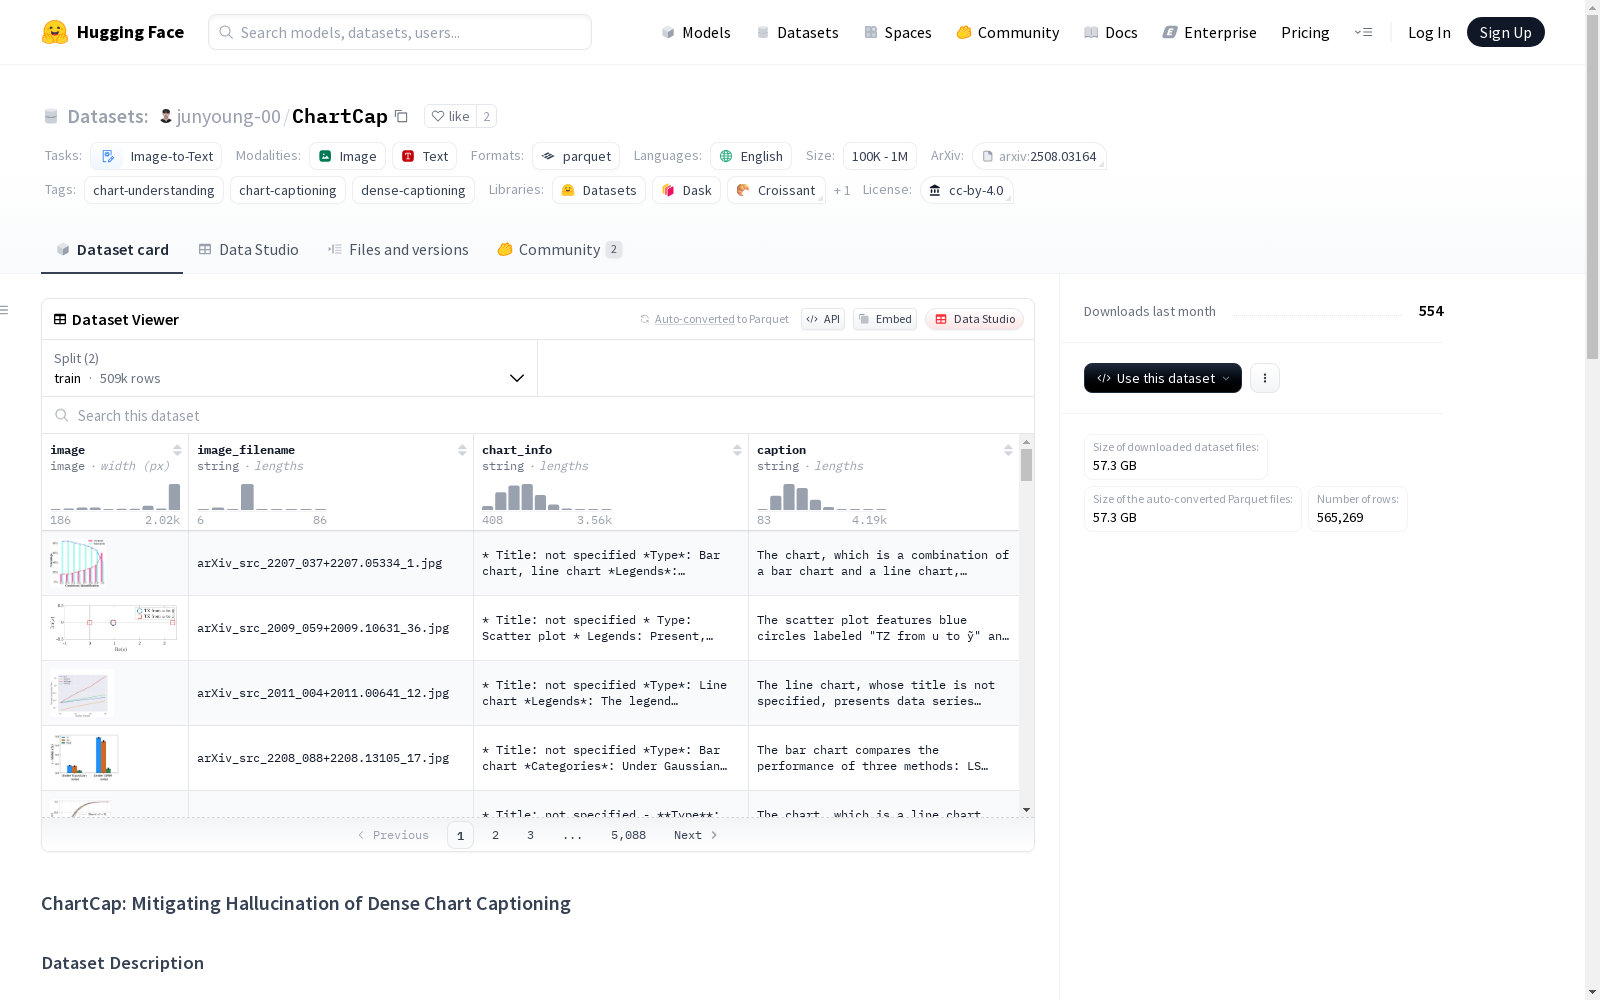
ChartCap is a large-scale dataset containing 565K real-world chart images and their corresponding type-specific and dense descriptions. These descriptions eliminate irrelevant information, and highlight the structural elements and key insights of the charts in detail. The dataset is split into training and test sets, and is suitable for image-to-text tasks.
ChartCap数据集概述
基本信息
- 语言: 英文 (en)
- 许可证: CC BY 4.0 (cc-by-4.0)
- 规模: 100K<n<1M
- 任务类型: 图像到文本 (image-to-text)
- 标签: 图表理解 (chart-understanding), 图表字幕生成 (chart-captioning), 密集字幕生成 (dense-captioning)
- arXiv论文: 2508.03164
- 库名称: datasets
数据集描述
ChartCap是一个大规模数据集,包含565K真实世界图表图像,配有针对特定类型的密集字幕,这些字幕排除了无关信息,详细突出了结构元素和关键见解。
数据集统计
- 训练集: 508,783个示例
- 测试集: 56,486个示例(人工验证)
- 总计: 565,269个示例
数据结构
每个示例包含以下字段:
image: 图表图像image_filename: 图像文件名chart_info: 使用GPT-4o提取的半结构化信息(用于粗粒度任务,如整体趋势)和Claude 3.5 Sonnet(用于细粒度任务,如精确数值)。此字段包含遵循特定类型模式的结构组件和关键见解。caption:chart_info的自然语言版本,提供描述图表结构元素和关键见解的连贯密集字幕。
使用方法
python from datasets import load_dataset
dataset = load_dataset("junyoung-00/ChartCap")
访问训练和测试集
train_data = dataset[train] test_data = dataset[test]
访问数据示例
example = train_data[0] image = example[image] caption = example[caption] chart_info = example[chart_info]
论文与引用
- 论文: ChartCap: Mitigating Hallucination of Dense Chart Captioning
- 项目页面: https://junyoung-00.github.io/ChartCap/
引用: bibtex @inproceedings{lim2025chartcap, title={ChartCap: Mitigating Hallucination of Dense Chart Captioning}, author={Junyoung Lim and Jaewoo Ahn and Gunhee Kim}, booktitle={Proceedings of the IEEE/CVF International Conference on Computer Vision}, year={2025} }
许可证
本数据集根据知识共享署名4.0国际许可协议(CC BY 4.0)发布。您可以自由共享和改编此数据集用于任何目的,包括商业用途,只要您通过引用我们的论文提供适当的署名。