
HypoGen
收藏资源简介:
HypoGen数据集是由牛津大学等机构的研究人员创建的,包含了从顶级计算机科学会议论文中提取的约5500个结构化问题-假设对。该数据集采用Bit-Flip-Spark模式,其中Bit是传统假设,Flip是创新方法,Spark是关键洞察的简短总结。数据集还包含了一个详细的推理链组件,展示了从传统观点到创新想法的思维过程。该数据集旨在为科学假设生成任务提供支持,解决科学研究中假设生成的问题。
The HypoGen dataset was developed by researchers from the University of Oxford and other institutions, containing approximately 5,500 structured question-hypothesis pairs extracted from top-tier computer science conference papers. The dataset follows the Bit-Flip-Spark pattern, where Bit represents a traditional hypothesis, Flip denotes an innovative methodology, and Spark is a concise summary of key insights. Additionally, the dataset includes a detailed reasoning chain component that illustrates the cognitive process transitioning from traditional perspectives to innovative ideas. This dataset is designed to facilitate scientific hypothesis generation tasks, addressing the core challenges of hypothesis generation in scientific research.
数据集概述
基本信息
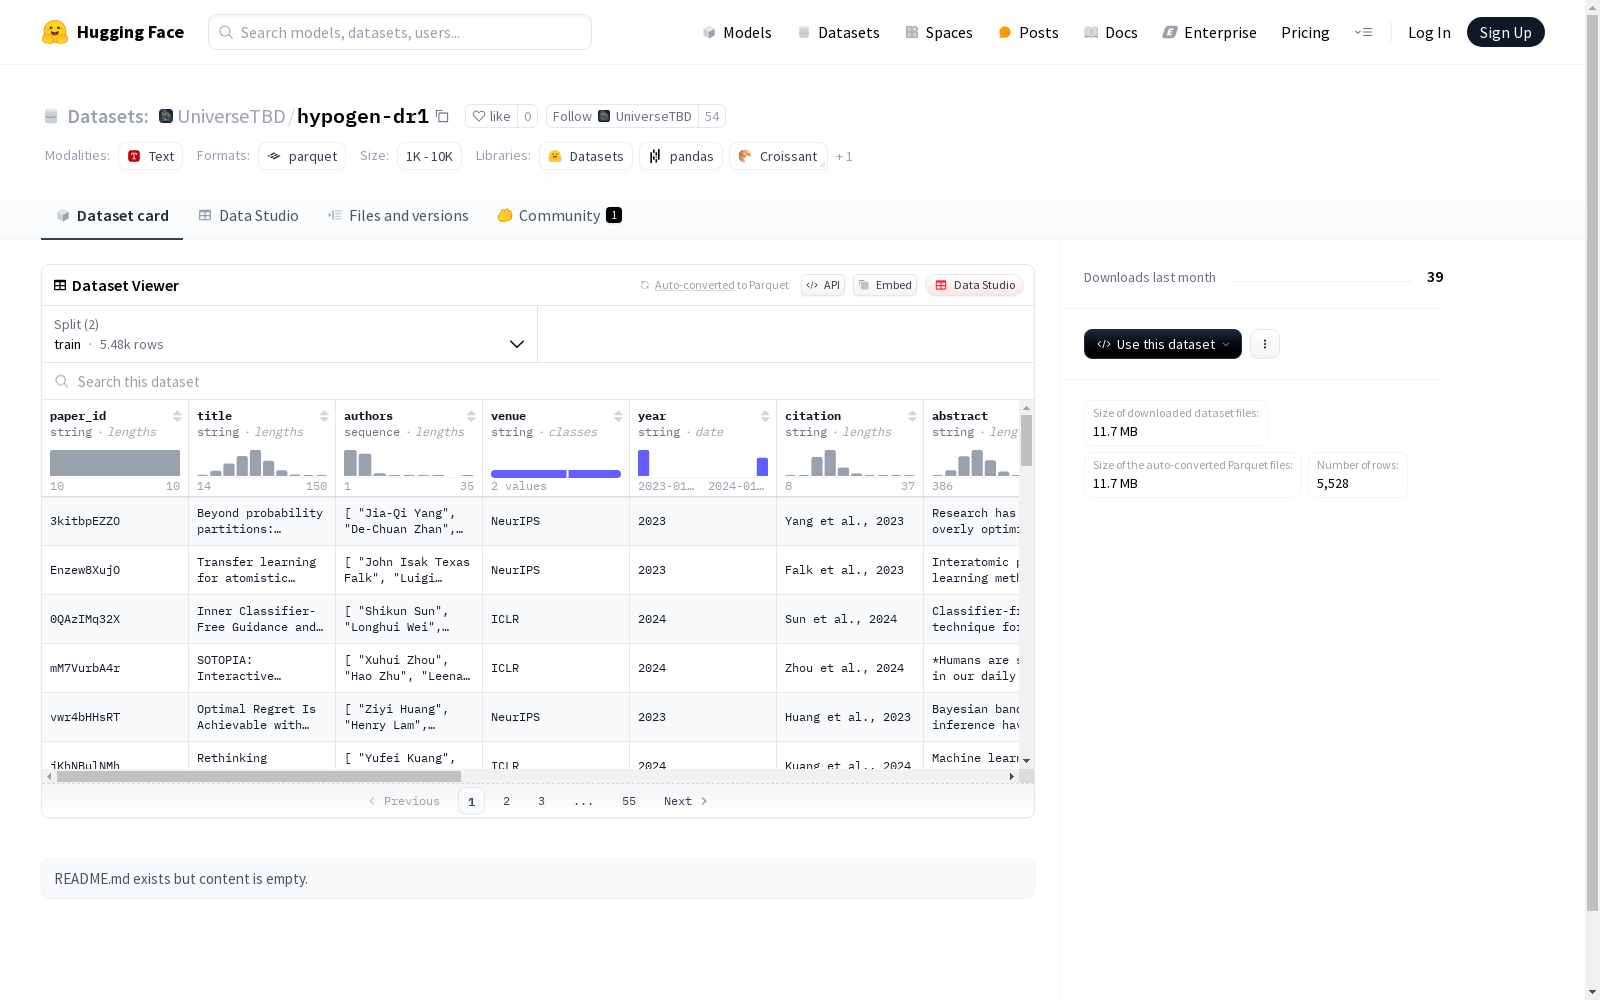
- 数据集名称: hypogen-dr1
- 存储库地址: https://huggingface.co/datasets/UniverseTBD/hypogen-dr1
- 下载大小: 11,657,781 字节
- 数据集大小: 21,437,217 字节
数据集结构
特征
paper_id: 字符串类型,论文IDtitle: 字符串类型,论文标题authors: 字符串序列,作者列表venue: 字符串类型,发表场所year: 字符串类型,发表年份citation: 字符串类型,引用信息abstract: 字符串类型,摘要bit: 字符串类型flip: 字符串类型spark: 字符串类型chain_of_reasoning: 字符串类型url: 字符串类型,论文链接pdf_url: 字符串类型,PDF链接
数据划分
- 训练集 (train)
- 样本数量: 5,478
- 数据大小: 21,242,773 字节
- 测试集 (test)
- 样本数量: 50
- 数据大小: 194,444 字节
配置文件
- 默认配置 (default)
- 训练集路径:
data/train-* - 测试集路径:
data/test-*
- 训练集路径:
- 1Sparks of Science: Hypothesis Generation Using Structured Paper Data牛津大学 · 2025年


