OpenRLHF/preference_dataset_mixture2_and_safe_pku
收藏资源简介:
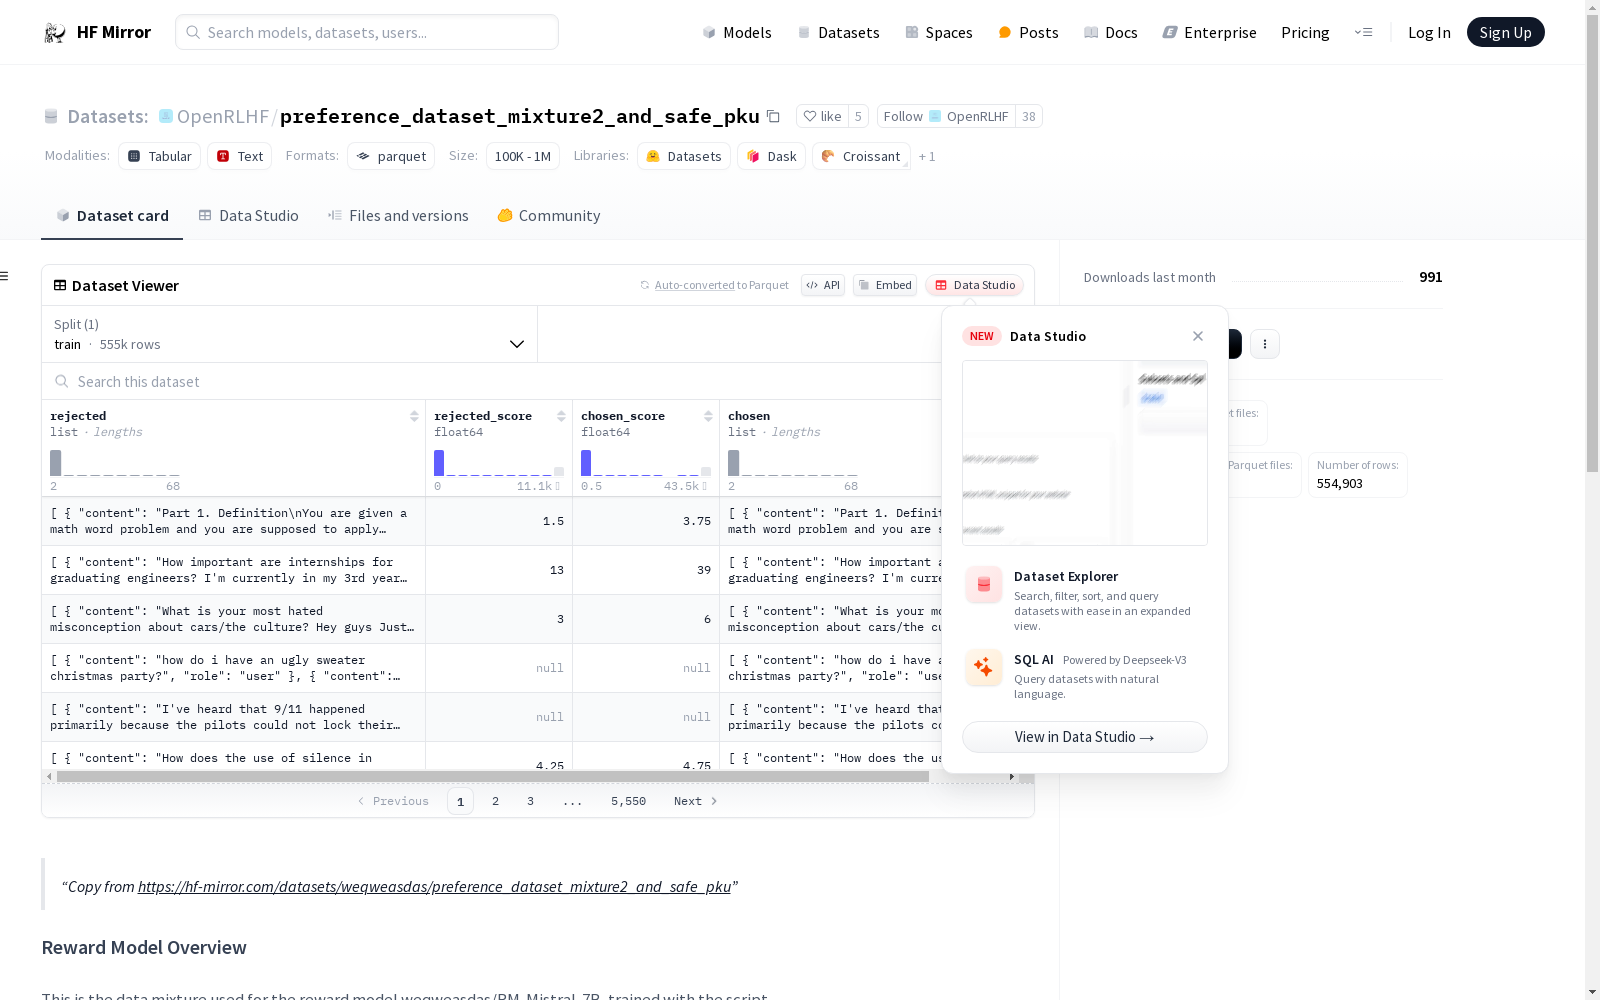
--- {} --- > Copy from https://huggingface.co/datasets/weqweasdas/preference_dataset_mixture2_and_safe_pku # Reward Model Overview <!-- Provide a quick summary of what the model is/does. --> This is the data mixture used for the reward model weqweasdas/RM-Mistral-7B, trained with the script https://github.com/WeiXiongUST/RLHF-Reward-Modeling . Also see a short blog for the training details (data mixture, parameters...): https://www.notion.so/Reward-Modeling-for-RLHF-abe03f9afdac42b9a5bee746844518d0 ## Model Details If you have any question with this reward model and also any question about reward modeling, feel free to drop me an email with wx13@illinois.edu. I would be happy to chat! ### Dataset preprocessing <!-- Provide a longer summary of what this model is. --> The model is trained on a mixture of the following datasets. - [HH-RLHF](https://huggingface.co/datasets/Anthropic/hh-rlhf) - [SHP](https://huggingface.co/datasets/stanfordnlp/SHP) - [UltraFeedback](https://huggingface.co/datasets/openbmb/UltraFeedback) - [Capybara](argilla/distilabel-capybara-dpo-7k-binarized) - [HelpSteer](https://huggingface.co/datasets/nvidia/HelpSteer) - [Orca](argilla/distilabel-intel-orca-dpo-pairs) - [PKU-Alignment/PKU-SafeRLHF-30K](https://huggingface.co/datasets/PKU-Alignment/PKU-SafeRLHF-30K) Difference between this mixture and the original dataset - HH-RLHF: we only use the helpful subset and we delete the noisy samples where chosen_response == rejected_response; - SHP: we only use the samples with score ratio > 2, for each prompt, we take 5 comparison at most, leading to 109526; - Ultrafeedback: similar to UltraFeedback-Binarized, we use the fine-grained score instead of the overall one to rank samples. Meanwhile, for each prompt, we take all possible 6 pairs of comparisons. Finally, we delete the selected pairs with equal scores, leading to 267416. - HelpSteer: we use the mean of helpfulness and correctness to rank samples. Meanwhile, we take all possible 6 pairs of comparisons. Finally, we delete the selected pairs with equal scores, leading to 21576;
This dataset is a mixture used for training the reward model weqweasdas/RM-Mistral-7B, consisting of several preprocessed datasets including HH-RLHF, SHP, UltraFeedback, Capybara, HelpSteer, Orca, and PKU-Alignment/PKU-SafeRLHF-30K. Each dataset is carefully selected and processed to enhance data quality and model performance.
数据集概述
数据集组成
该数据集是用于训练奖励模型 weqweasdas/RM-Mistral-7B 的数据混合体,包含以下子数据集:
数据预处理
- HH-RLHF: 仅使用有帮助的子集,并删除
chosen_response == rejected_response的噪声样本。 - SHP: 仅使用评分比率大于2的样本,每个提示最多取5个比较,最终得到109526个样本。
- UltraFeedback: 使用细粒度评分而非总体评分来排序样本,每个提示取所有可能的6对比较,删除评分相等的选定对,最终得到267416个样本。
- HelpSteer: 使用帮助性和正确性的平均值来排序样本,每个提示取所有可能的6对比较,删除评分相等的选定对,最终得到21576个样本。