gsd-smith-Cebuano
收藏资源简介:
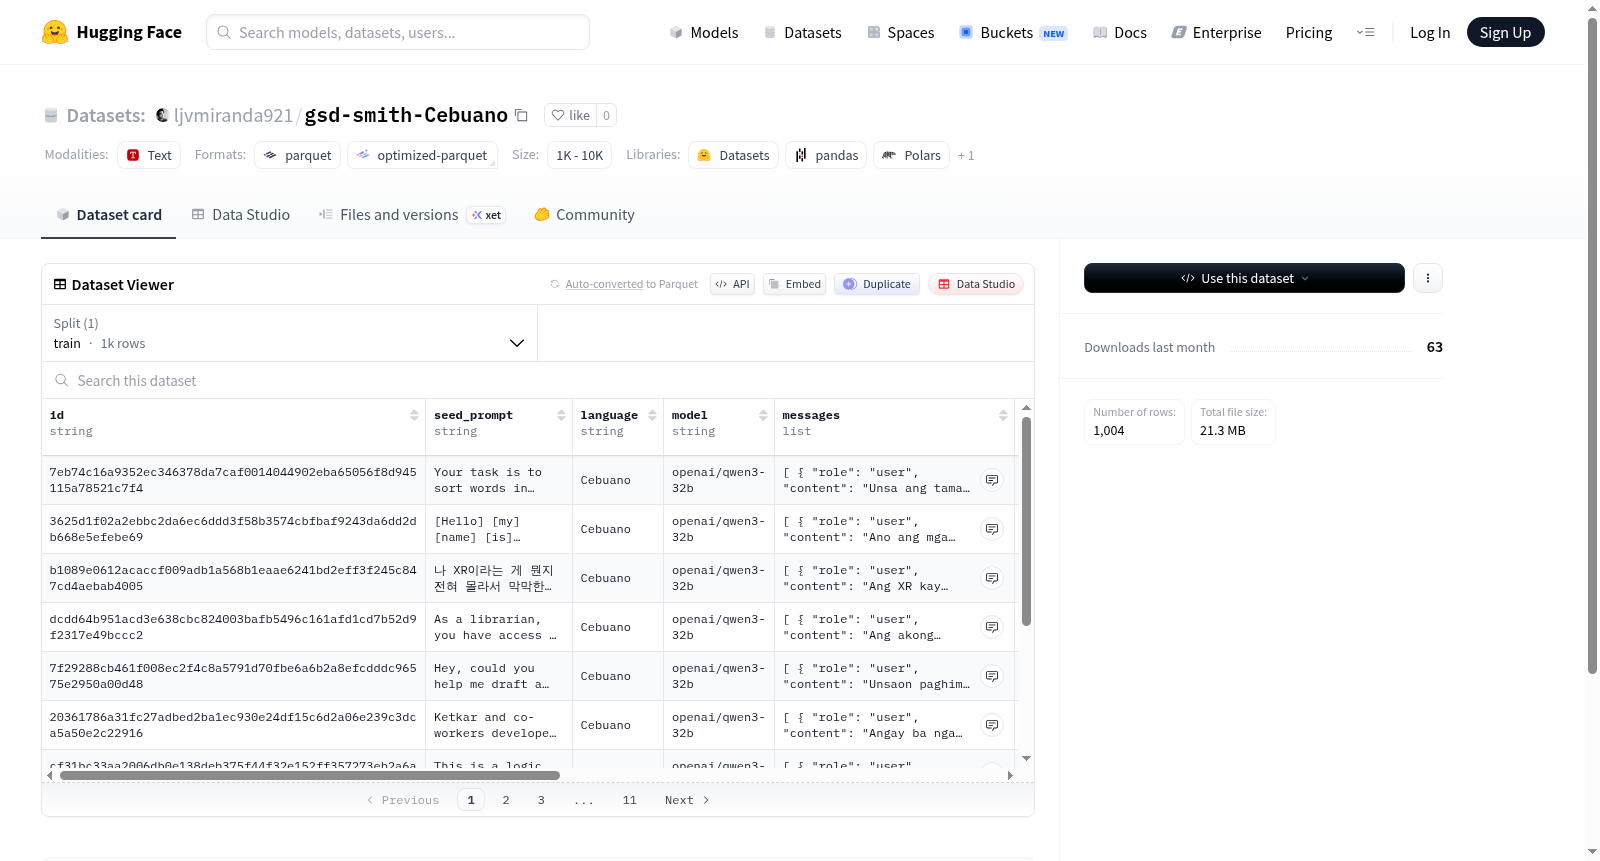
该数据集包含多轮对话记录,适用于对话系统、语言模型训练和代理行为分析等任务。数据集共包含729个训练样本,总大小约为15.9MB。每个样本包含以下字段:唯一标识符(id)、对话的初始种子提示(seed_prompt)、使用的语言(language)、生成对话的模型信息(model)、按顺序排列的消息列表(messages,其中每条消息包含角色(role)和内容(content))、代理执行过程的追踪记录(agent_trace,以JSON列表格式存储)以及原始数据来源标识(source_id)。数据以结构化格式组织,支持对多轮对话交互进行深入分析。
This dataset contains multi-turn dialogue records, suitable for tasks such as dialogue systems, language model training, and agent behavior analysis. The dataset includes 729 training samples with a total size of approximately 15.9MB. Each sample contains the following fields: unique identifier (id), initial seed prompt for the dialogue (seed_prompt), language used (language), model information used to generate the dialogue (model), a sequentially ordered list of messages (messages, where each message includes a role and content), a trace record of the agent execution process (agent_trace, stored in JSON list format), and an identifier for the original data source (source_id). The data is organized in a structured format, supporting in-depth analysis of multi-turn dialogue interactions.