emotional-roleplay-finetuning-dataset
收藏资源简介:
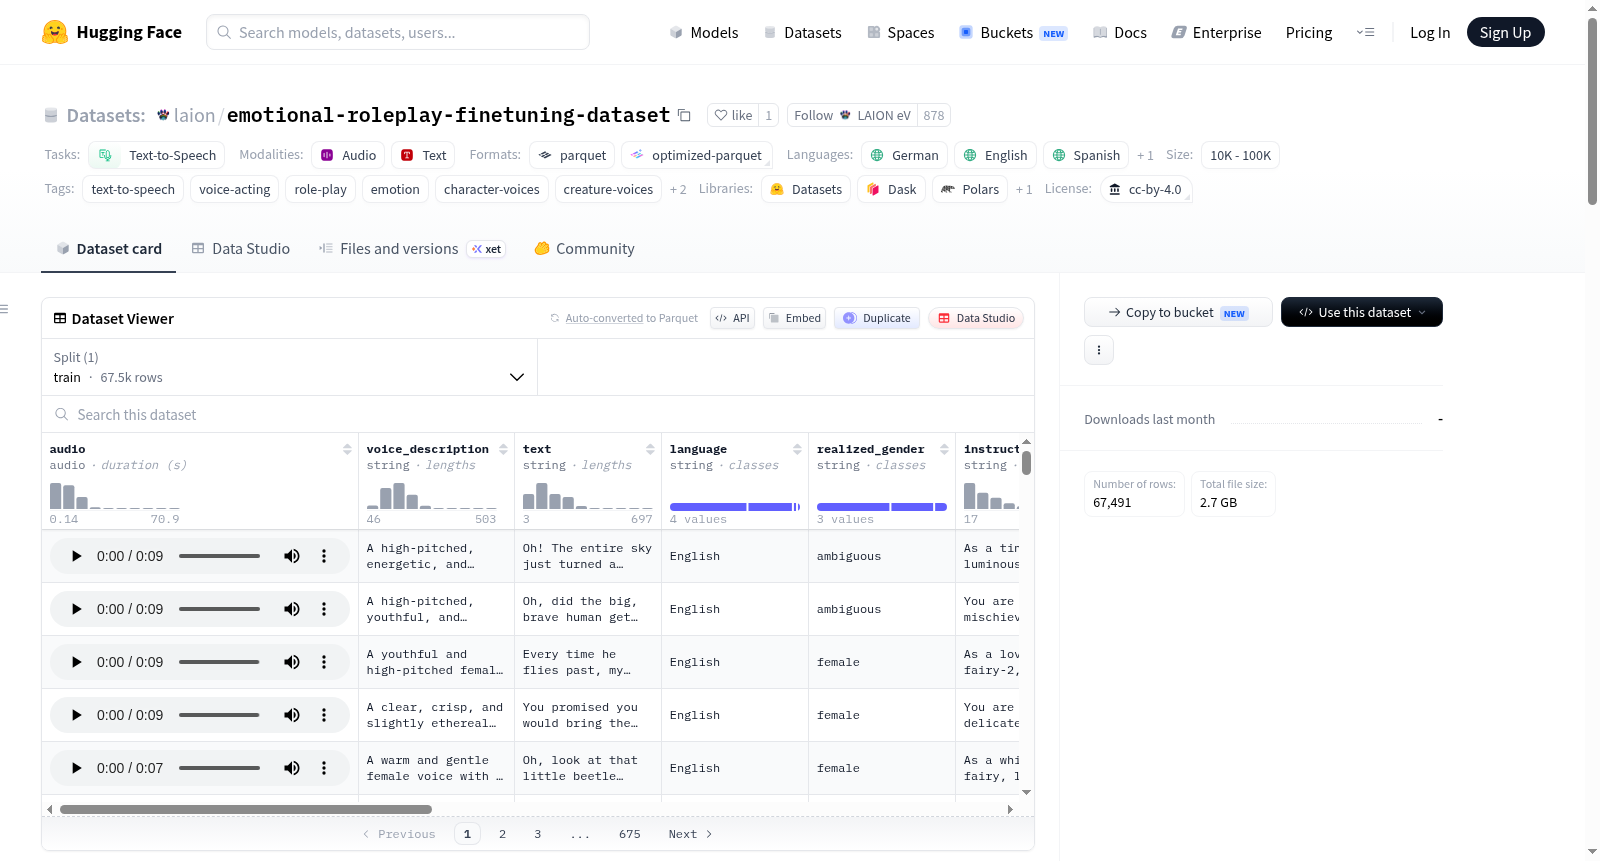
人工语音角色扮演数据集是一个完全合成的多语言语音数据集,专门为语音方向文本到语音(TTS)训练而设计。该数据集包含67,711个语音片段(约184小时),覆盖德语、英语、西班牙语和法语四种语言,其中德语数据占主导。数据集的核心特点是其丰富的表达性角色扮演和角色语音,特别强调夸张的幻想/生物语音(如兽人、地精、巨魔、僵尸、龙、恶魔、女巫、机器人等)以及高唤醒度的情感表达(如愤怒、恐惧、悲伤、威胁)。所有音频均由微调后的MOSS-TTS-Local v1.5模型机器生成,并采用CC-BY-4.0许可发布。每个样本包含多个字段:audio(单声道MP3格式,24kHz采样率的合成音频)、voice_description(由gemini-3.5-flash根据实际生成的音频编写的描述语音听感的标签,是主要训练标签)、text(语音内容文本)、language(语言标识)、realized_gender(音频中实际感知到的性别:女性/男性/模糊)、instruction(用于生成音频的原始语音方向提示词)、adherence_score(音频与提示词匹配度的1-5分评分)以及req_character、req_gender、req_volume、req_emotion等请求属性字段。数据构成方面,约57%的语音被感知为男性,33%为女性,10%为模糊;约41%的片段属于非人类角色语音,涵盖18种以上原型,其中包括约9,000个女性生物语音片段。情感范围涵盖平静、愤怒、恐惧、悲伤、威胁、喜悦、嘲讽等。该数据集适用于训练能够理解和生成具有特定角色特征、情感和风格的语音的TTS模型。其主要优势在于标签是“法官验证”的,即根据实际生成的音频编写,避免了TTS模型漂移导致的标签不匹配。局限性包括生成模型对女性语音和大声/喊叫语音存在抵抗,导致数据集中男性和平静语音占主导;语言分布偏向德语和英语;以及合成语音可能存在的伪影。
Artificial Voice Roleplay Dataset is a fully synthetic multilingual speech dataset specifically designed for voice-directed text-to-speech (TTS) training. It contains 67,711 speech clips (approximately 184 hours), covering four languages: German, English, Spanish, and French, with German data being dominant. The core feature of the dataset is its rich expressive role-playing and character voices, with a particular emphasis on exaggerated fantasy/creature voices (such as orcs, goblins, trolls, zombies, dragons, demons, witches, robots, etc.) and high-arousal emotional expressions (such as anger, fear, sadness, threat). All audio is machine-generated using a fine-tuned MOSS-TTS-Local v1.5 model and is released under the CC-BY-4.0 license. Each sample includes multiple fields: audio (mono MP3 format, synthetic audio at 24kHz sampling rate), voice_description (a label describing the auditory perception of the voice, written by gemini-3.5-flash based on the actual generated audio, serving as the primary training label), text (speech content text), language (language identifier), realized_gender (perceived gender in the audio: female/male/ambiguous), instruction (original voice direction prompt used to generate the audio), adherence_score (a 1-5 score rating the match between the audio and the prompt), and request attribute fields such as req_character, req_gender, req_volume, req_emotion. In terms of data composition, approximately 57% of the voices are perceived as male, 33% as female, and 10% as ambiguous; about 41% of the clips belong to non-human character voices, covering over 18 archetypes, including approximately 9,000 female creature voice clips. The emotional range covers calm, anger, fear, sadness, threat, joy, sarcasm, etc. This dataset is suitable for training TTS models capable of understanding and generating speech with specific character traits, emotions, and styles. Its main advantage is that the labels are judge-verified, meaning they are written based on the actual generated audio, avoiding label mismatches due to TTS model drift. Limitations include the generation models resistance to female voices and loud/shouting voices, leading to a predominance of male and calm voices in the dataset; a language distribution biased towards German and English; and potential artifacts in the synthetic speech.
数据集概述
Artificial Voice Roleplay Dataset 是一个大规模、完全合成的语音数据集,包含 67,711 个语音片段(约 184 小时),专注于角色扮演和情感表达。该数据集由 MOSS-TTS-Local v1.5 模型微调生成,并经过自动标注与质量审核。
核心特征
- 语言:德语(主导)、英语、西班牙语、法语(西班牙语和法语数据量较小)。
- 角色种类:约 41% 的片段为奇幻/生物角色声音(如兽人、哥布林、龙、恶魔、女巫、机器人等 18 种以上原型),包含约 9,000 个女性生物角色声音片段。
- 情感范围:从中性工作室语音到强烈情感表演(愤怒、恐惧、悲伤、威胁、喜悦、嘲讽等),涵盖喊叫和低语。
- 音频格式:单声道 MP3,采样率 24 kHz。
- 许可证:CC-BY-4.0。
数据模式(Schema)
数据集以 Hugging Face AudioFolder 格式组织,主要字段如下:
| 字段 | 描述 |
|---|---|
audio / file_name |
合成的音频文件 |
voice_description |
主要标签——由自动评判模型(gemini-3.5-flash)根据实际音频写出的声音描述 |
text |
语音中的文字内容 |
language |
语言(德语/英语/西班牙语/法语) |
realized_gender |
音频中实际听到的性别(female/male/ambiguous) |
instruction |
生成该片段时使用的原始声音方向提示 |
adherence_score |
评判者对音频与 instruction 匹配程度的 1–5 评分 |
req_character / req_gender / req_volume / req_emotion |
生成时请求的属性(用于目标生成行,未经验证音频) |
source |
提示的来源 |
duration / id |
时长(秒)和唯一 ID |
数据构成
按语言分布(共 67,711 个片段):
| 语言 | 片段数 |
|---|---|
| 德语 | 40,303 |
| 英语 | 23,279 |
| 西班牙语 | 2,106 |
| 法语 | 2,023 |
按实际性别分布:
| 性别 | 片段数(占比) |
|---|---|
| 男性 | 38,270(57%) |
| 女性 | 22,369(33%) |
| 模糊 | 7,072(10%) |
生成流程
- 提示来源:从 DramaBox 风格的声音方向数据集中提取,并补充目标网格(角色 × 性别 × 音量 × 情感)和强制最佳-N 遍历,针对困难分布(如女性生物角色、喊叫)进行增强。
- 音频合成:使用 MOSS 微调模型(
creatures_p9,温度 1.7,top_p 0.8)在 2× RTX 3090 上生成。对于分布外的属性,模型进行 N 次采样,并通过 VoiceCLAP 性别/强度评分器过滤,保留女性/大声候选。 - 标注与质量检查:由 gemini-3.5-flash 为每个音频片段生成
voice_description,同时验证文字内容与可懂度,失败片段被丢弃。
使用示例
python from datasets import load_dataset ds = load_dataset("laion/artificial-voice-roleplay-dataset", split="train") ex = ds[0] print(ex["voice_description"], "||", ex["text"], "||", ex["language"], "||", ex["realized_gender"]) ex["audio"] # {array: ..., sampling_rate: 24000}
已知限制
- 性别与情感偏差:生成模型默认倾向于男性/平静声音,对分布外的女性角色和喊叫表现不佳。尽管通过目标生成与本地过滤改善了女性生物角色覆盖(约 9k 片段),整体仍约 57% 为男性音频。
req_*字段可能夸大了女性/大声属性,应以voice_description和realized_gender为准。 - 音量标签:“喊叫”通过强度词语(激进/有力/命令式)描述,而非实际音量标签;音频振幅因 MOSS 归一化处理并非更高。
- 合成语音:尽管经过可懂度过滤,仍可能存在 TTS 伪影。
- 标签准确性:
voice_description来自单一自动评判模型,未经人工验证。 - 语言偏斜:德语和英语占主导,西班牙语和法语数据量很小。