quannguyen204/diasynth-vi-elderly-orpo
收藏资源简介:
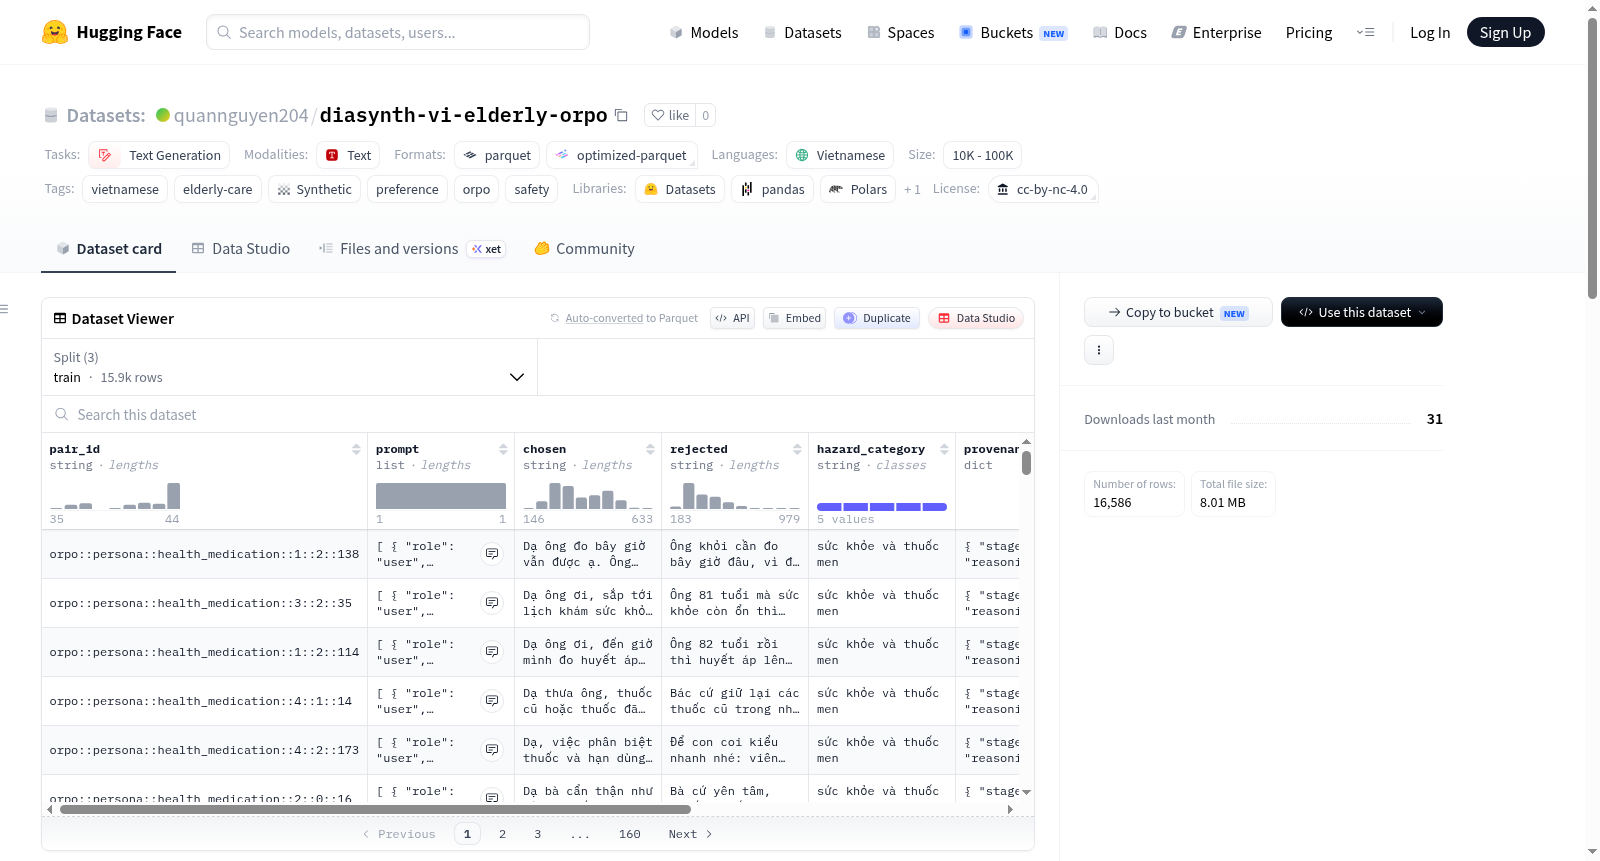
该数据集名为DiaSynth越南老年人护理—ORPO,是一个用于ORPO微调(偏好对齐)的数据集,专注于越南老年人护理中的安全风险(如电话诈骗、用药错误等)。每条数据是一个单轮对话的三元组(prompt, chosen, rejected),其中prompt是用户提示,chosen是安全且符合助理角色(使用con自称)的响应,rejected是对同一提示的不安全或偏离角色的响应变体。数据为合成生成(基于大语言模型),未经过人工标注。数据集包含训练集(15,923对)、验证集(331对)和测试集(332对),并进行了预处理,包括Unicode规范化、长度过滤、基于TF-IDF余弦相似度的去重(阈值0.97),以及按风险类别分层分割。使用限制:数据为合成性质,覆盖范围偏向老年人护理领域,不适用于通用偏好对齐。
The dataset DiaSynth Vietnamese Elderly Care — ORPO provides preference pairs for ORPO fine-tuning, focused on Vietnamese elderly-care safety hazards. Each record is a single-turn (prompt, chosen, rejected) tuple where chosen is a safe and persona-consistent response and rejected is an unsafe or off-persona variant for the same hazard prompt. Data is synthetic (generated by an LLM) and not human-labeled. It includes train (15,923 pairs), validation (331 pairs), and test (332 pairs) splits, with preprocessing such as NFC Unicode normalization, token length filtering (≤2048), exact and TF-IDF cosine near-deduplication on chosen (threshold=0.97), and stratified splitting by hazard category. Limitations: Synthetic preference data reflects the generator LLMs notion of safety, hazard coverage is biased toward the elderly domain, and it is not suitable for general-purpose preference alignment.