harsha-desaraju/telugu-book-line-images
收藏资源简介:
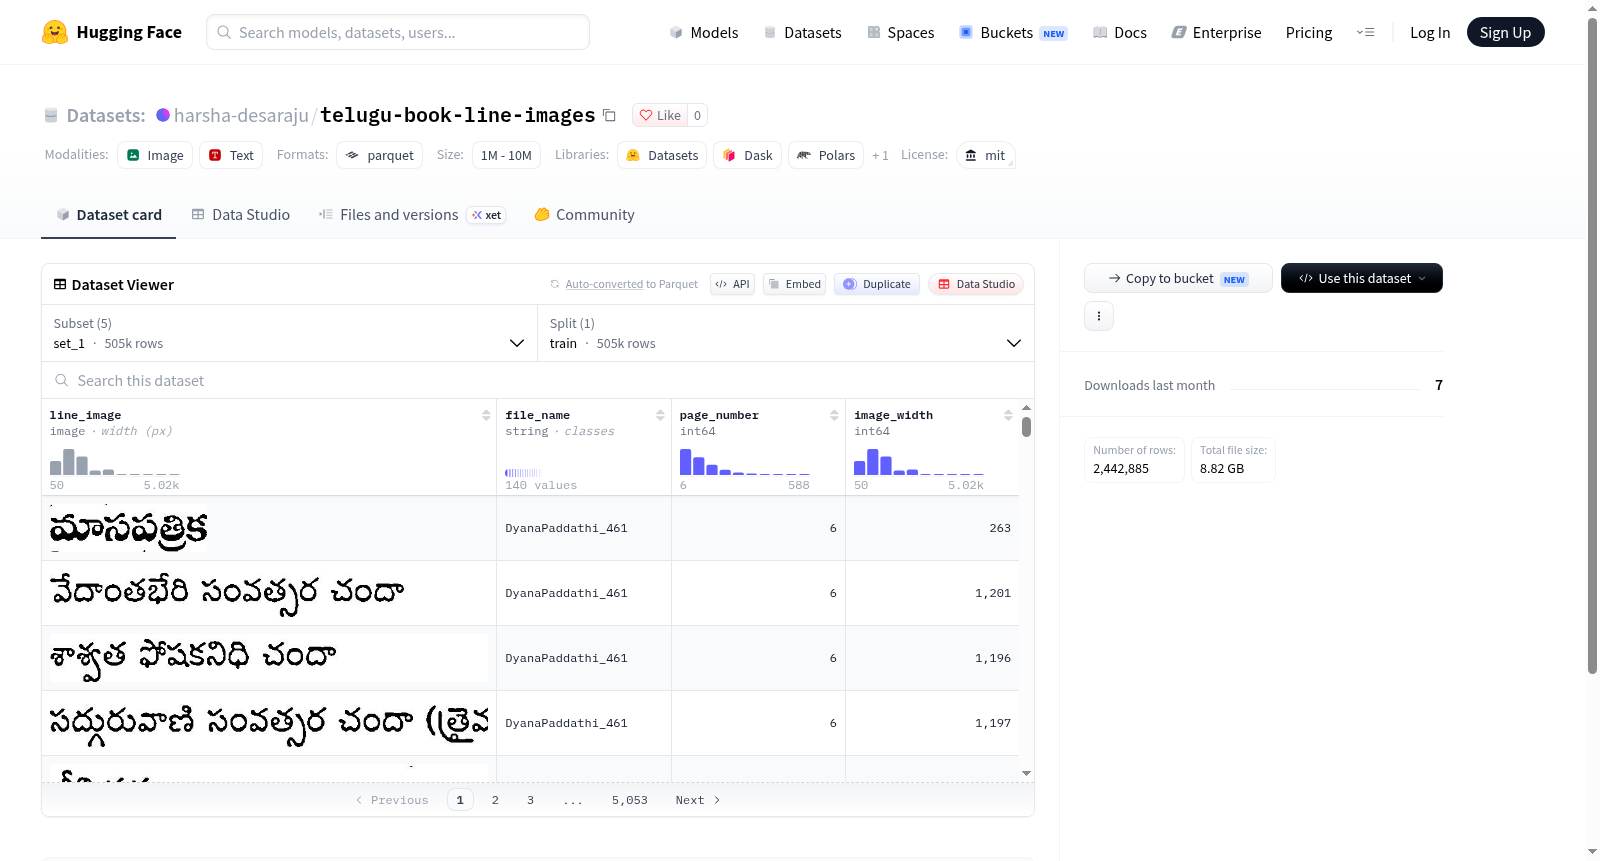
该数据集包含五个配置(set_1到set_5),每个配置均由训练集组成,特征包括行图像(line_image)、文件名(file_name)和页码(page_number)。数据集总训练示例数约为244万(各配置示例数:set_1约50.5万,set_2约50.4万,set_3约50.1万,set_4约50.3万,set_5约43.0万),总数据大小约8.7GB。数据可能用于文档图像处理或光学字符识别(OCR)相关任务,但具体来源和用途未在README中明确说明。
This dataset includes five configurations (set_1 to set_5), each consisting of a training split with features such as line images (line_image), file names (file_name), and page numbers (page_number). The total number of training examples is approximately 2.44 million (with individual configs: set_1 ~505k, set_2 ~504k, set_3 ~501k, set_4 ~503k, set_5 ~430k), and the overall dataset size is about 8.7GB. The data is likely intended for document image processing or optical character recognition (OCR) related tasks, but specific sources and purposes are not detailed in the README.