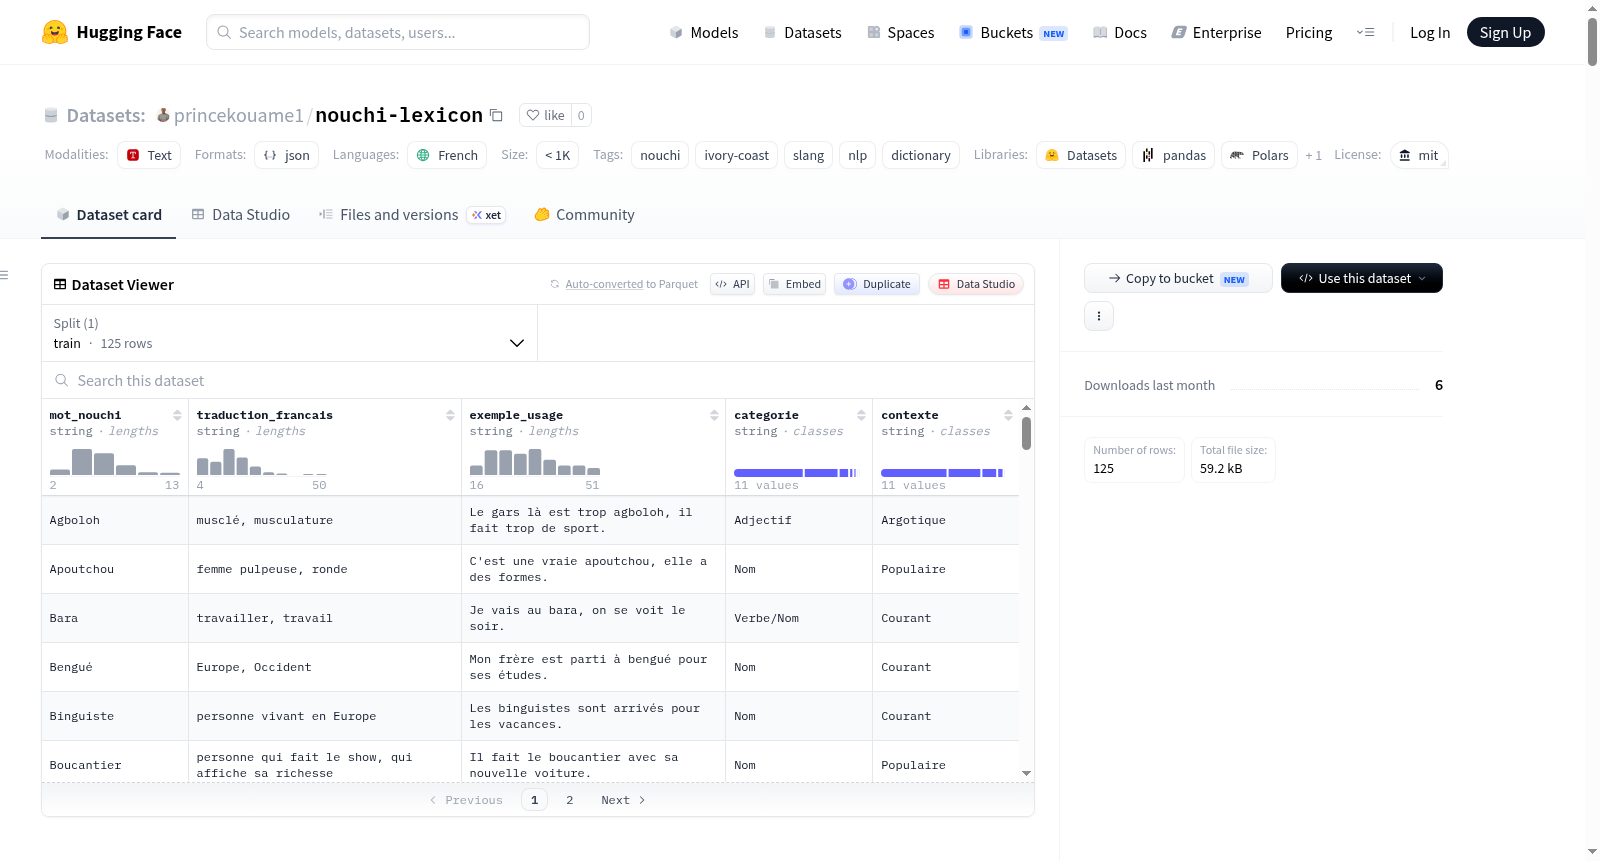
nouchi-lexicon
收藏资源简介:
Nouchi Lexicon是一个专注于科特迪瓦城市俚语Nouchi的词典数据集。Nouchi是一种起源于20世纪70-80年代阿比让的城市混合语,融合了标准法语词汇、当地语言(如马林克语、巴乌莱语、贝特语)和流行创意表达,已发展成为真正的城市克里奥尔语。该数据集旨在记录和保存这种独特的语言现象,支持相关自然语言处理研究。数据集包含125个词条,每个词条提供以下结构化信息:Nouchi术语、法语翻译、使用示例、语法类别(名词、动词、形容词、表达、感叹词)、语言语境(常用、俚语、流行、口语化),以及可选的拼写变体和词源信息。数据分布以名词为主(45%),其次是动词(28%)、形容词(15%)、表达(8%)和感叹词(4%)。该数据集适用于多种自然语言处理任务,包括文本分类、机器翻译(Nouchi↔法语)、文本生成、命名实体识别、词嵌入和对话系统开发。数据通过实地观察、数字内容分析、音频转录和学术资料收集,并经过母语者和语言学家验证,确保语义有效性和分类准确性。数据集采用MIT许可证发布,支持社区贡献新词条。
Nouchi Lexicon is a lexical dataset focused on Nouchi, an urban slang from Côte dIvoire. Nouchi originated in Abidjan during the 1970s-1980s as a mixed urban language, blending standard French vocabulary, local languages (such as Malinke, Baoule, and Bete), and popular creative expressions, evolving into a true urban creole. This dataset aims to document and preserve this unique linguistic phenomenon, supporting natural language processing research. It contains 125 entries, each providing structured information: Nouchi term, French translation, usage examples, grammatical category (noun, verb, adjective, expression, interjection), linguistic context (common, slang, popular, colloquial), and optional spelling variants and etymological details. The data distribution is dominated by nouns (45%), followed by verbs (28%), adjectives (15%), expressions (8%), and interjections (4%). The dataset is suitable for various NLP tasks, including text classification, machine translation (Nouchi↔French), text generation, named entity recognition, word embeddings, and dialogue system development. Data was collected through field observations, digital content analysis, audio transcriptions, and academic sources, and validated by native speakers and linguists to ensure semantic validity and classification accuracy. It is released under the MIT license and supports community contributions of new entries.
数据集概览
Nouchi Lexicon (Ivorian Slang) 是一个专注于科特迪瓦城市俚语 Nouchi 的词库数据集,旨在为自然语言处理(NLP)任务提供结构化的语言资源。
数据集核心信息
| 属性 | 值 |
|---|---|
| 数据集名称 | Nouchi Lexicon (Ivorian Slang) |
| 许可证 | MIT |
| 主要语言 | 法语(fr)、努奇语(nouchi) |
| 标签 | nouchi, ivory-coast, slang, nlp, dictionary, african-languages, code-switching, urban-linguistics |
| 数据集大小 | n<1K(训练集:125条示例) |
| 任务类别 | 文本分类、词元分类、翻译、掩码填充 |
数据特征与结构
数据集包含以下特征字段:
| 字段名 | 数据类型 | 描述 | 示例 |
|---|---|---|---|
mot_nouchi |
string | 努奇语词汇 | "Gbô" |
traduction_francais |
string | 法语翻译/定义 | "Travail, activité rémunérée" |
exemple_usage |
string | 用法示例 | "Gbô là, on va au maquis ce soir !" |
categorie |
enum | 语法类别(名词、动词、形容词、表达、感叹词) | "Nom" |
contexte |
enum | 语境/语域(日常、俚语、通俗、口语) | "Argotique" |
variantes_orthographiques |
string (可选) | 其他拼写变体 | "Gbo, Gboh" |
origine_linguistique |
string (可选) | 语言来源 | "Baoulé" |
date_ajout |
timestamp | 添加日期 | "2026-07-26" |
数据集划分:仅包含训练集(train),共125条数据,文件大小为15,000字节。
数据样例
json [ { "mot_nouchi": "Gbô", "traduction_francais": "Travail, activité rémunérée, business", "exemple_usage": "Mon gbô là, ça rapporte bien cette semaine !", "categorie": "Nom", "contexte": "Argotique", "variantes_orthographiques": "Gbo, Gboh", "origine_linguistique": "Baoulé", "date_ajout": "2026-07-26" }, { "mot_nouchi": "Bluffer", "traduction_francais": "Mentir, exagérer, raconter des histoires", "exemple_usage": "Arrête de bluffer, on sait que cest pas vrai !", "categorie": "Verbe", "contexte": "Populaire", "variantes_orthographiques": "Blufé", "origine_linguistique": "Français (détournement)", "date_ajout": "2026-07-26" } ]
数据收集方法
数据通过以下途径收集并验证:
- 实地观察:在阿比让及其街区进行田野调查。
- 数字内容分析:分析社交媒体、音乐等网络资源。
- 音频记录:记录自然对话。
- 学术来源:参考论文和研究文章。
- 多方验证:由母语者、语言学家进行交叉验证,并确保标注者间达成共识。
潜在应用场景
该数据集可用于多种NLP任务,包括但不限于:
- 文本分类:语言检测、情感分析、内容审核。
- 翻译:努奇语与法语之间的机器翻译、聊天机器人、语音助手。
- 文本生成:创意内容生成、故事叙述。
- 命名实体识别(NER):俚语提取、文化术语识别。
- 词嵌入:语义向量表示、语言模型。
- 对话系统:对话代理、自动回答。
使用方式
可通过 Hugging Face datasets 库加载:
python from datasets import load_dataset dataset = load_dataset("kouame09/nouchi-lexicon")
扩展信息
- 数据集地址:https://huggingface.co/datasets/princekouame1/nouchi-lexicon
- 贡献方式:通过 Fork 仓库、创建分支、提交 Pull Request 的方式贡献新词条,需遵循指定的 YAML 格式,并满足真实性、准确性、完整性等验证标准。