AudioVisualMouseSaliency
收藏资源简介:
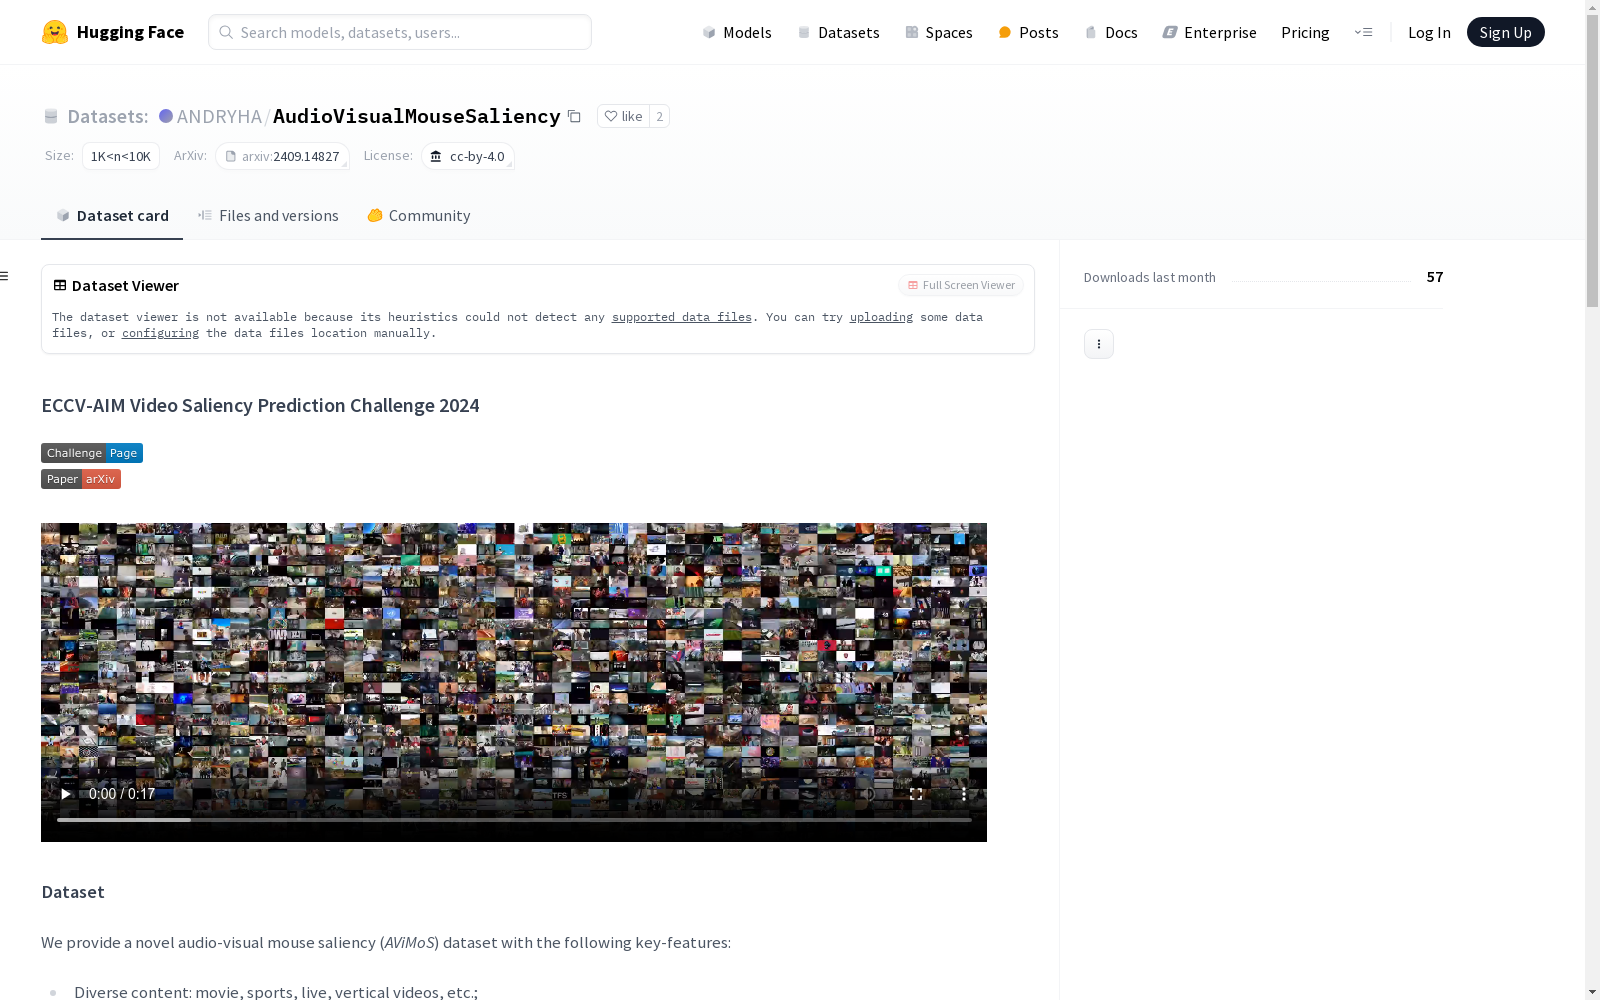
AViMoS数据集是一个用于ECCV-AIM 2024视频显著性预测挑战的新型音频-视觉鼠标显著性数据集。该数据集包含1500个视频,平均时长为19秒,所有视频均为全高清分辨率。视频内容多样,涵盖电影、体育、直播和垂直视频等。每个视频都包含一个音频轨道,观察者在观看视频时播放音频。数据集收集了来自超过5000名观察者的鼠标注视点,平均每个视频有超过70个注视点。数据集采用CC-BY许可。文件结构包括视频、训练/测试分割、显著性图、注视图和视频元数据。该数据集旨在用于视频显著性预测任务,并提供了详细的评估指南。
The AViMoS dataset is a novel audio-visual mouse saliency dataset for the ECCV-AIM 2024 Video Saliency Prediction Challenge. It contains 1500 videos with an average duration of 19 seconds, all at full high-definition resolution. The video content spans diverse categories, including films, sports, live broadcasts, and vertical videos. Each video includes an audio track played synchronously while observers watched the video. The dataset collected mouse gaze points from over 5,000 observers, with an average of more than 70 gaze points per video. The dataset is released under a CC-BY license. Its file structure encompasses videos, train/test splits, saliency maps, fixation maps, and video metadata. This dataset is designed for video saliency prediction tasks, and detailed evaluation guidelines are provided.
AViMoS 数据集
概述
- 名称: AViMoS
- 许可证: CC-BY
- 规模: 1500 个视频,平均时长 19 秒
- 分辨率: 全高清 (FullHD)
- 音频: 包含音频轨道,观察者播放时开启声音
- 观察者: 超过 5000 名观察者,每个视频平均超过 70 名观察者
文件结构
Videos.zip- 包含 1500 个视频,分为 1000 个训练视频和 500 个测试视频。TrainTestSplit.json- 提供所有视频的训练/公开测试/私有测试分割。SaliencyTrain.zip/SaliencyTest.zip- 训练/测试子集的连续显著性图视频,几乎无损压缩。FixationsTrain.zip/FixationsTest.zip- 包含训练/测试子集的以下文件:.../video_name/fixations.json- 每帧的注视点坐标,用于计算指标。.../video_name/fixations/- 二进制注视图,以.png格式保存,用于可视化和帧数检查。
VideoInfo.json- 每个视频的元信息(如许可证)。
评估
环境设置
conda create -n saliency python=3.8.16 conda activate saliency pip install numpy==1.24.2 opencv-python==4.7.0.72 tqdm==4.65.0 conda install ffmpeg=4.4.2 -c conda-forge
运行评估
- 使用
bench.py脚本进行评估,需提供预测的显著性视频和帧,以及相应的真实数据。
引用
@inproceedings{aim2024vsp, title={{AIM} 2024 Challenge on Video Saliency Prediction: Methods and Results}, author={Andrey Moskalenko and Alexey Bryncev and Dmitry Vatolin and Radu Timofte and Gen Zhan and Li Yang and Yunlong Tang and Yiting Liao and Jiongzhi Lin and Baitao Huang and Morteza Moradi and Mohammad Moradi and Francesco Rundo and Concetto Spampinato and Ali Borji and Simone Palazzo and Yuxin Zhu and Yinan Sun and Huiyu Duan and Yuqin Cao and Ziheng Jia and Qiang Hu and Xiongkuo Min and Guangtao Zhai and Hao Fang and Runmin Cong and Xiankai Lu and Xiaofei Zhou and Wei Zhang and Chunyu Zhao and Wentao Mu and Tao Deng and Hamed R. Tavakoli}, booktitle={Proceedings of the European Conference on Computer Vision (ECCV) Workshops}, year={2024} }