dev_set_v2_a1_tulu3_sft_personas_math_20260815_140251
收藏资源简介:
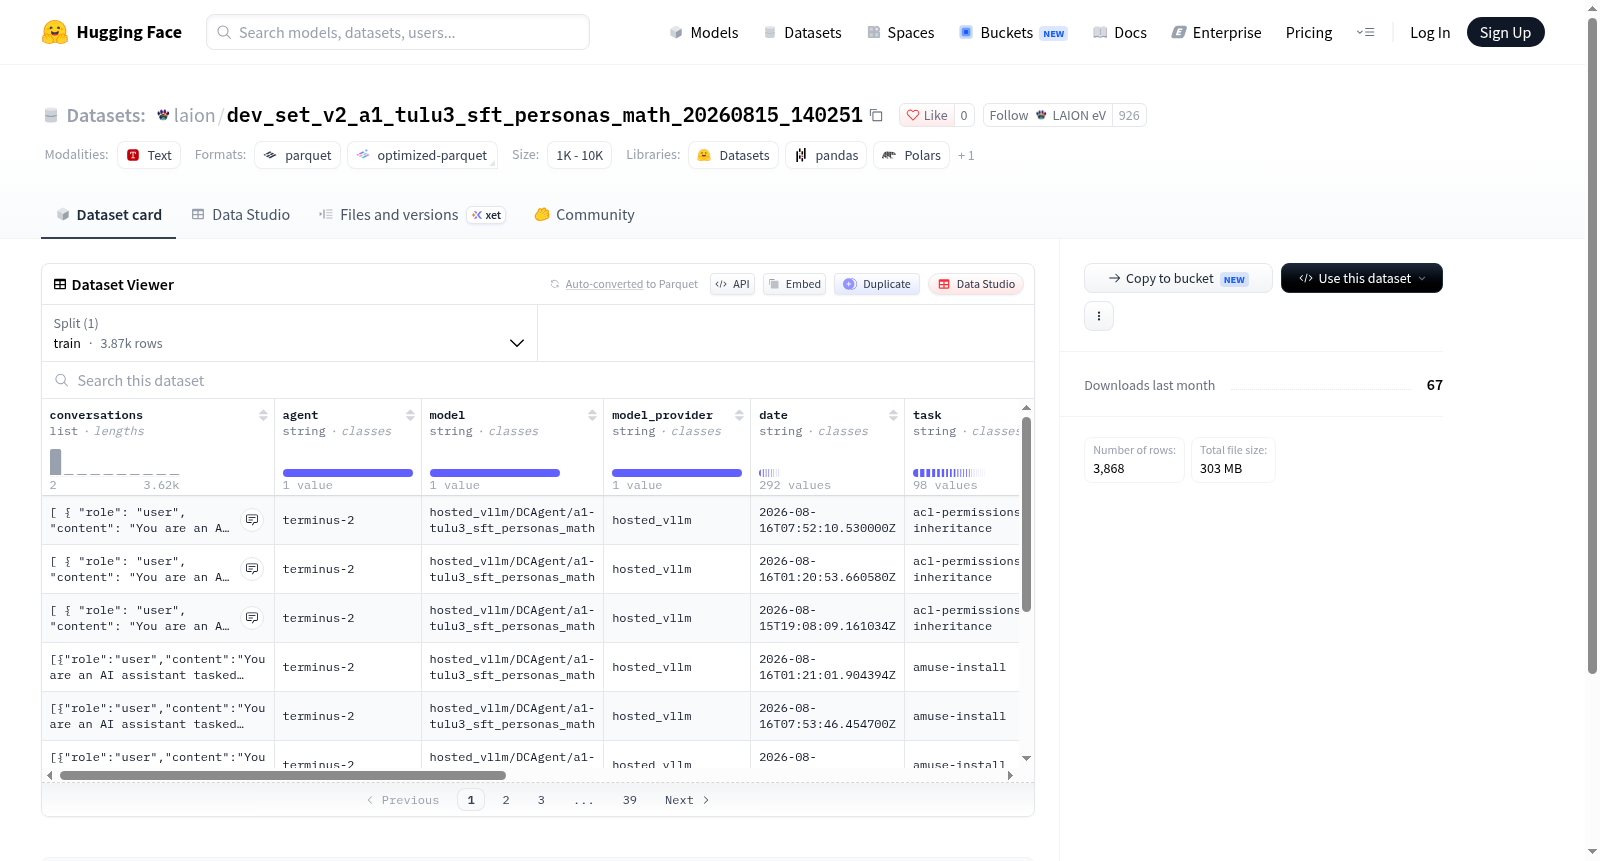
该数据集是一个多轮对话数据集,记录了AI代理与用户或系统之间的交互过程。每个样本包含完整的对话历史(角色与内容)、代理名称、使用的模型及模型提供商、对话日期、任务描述、实验轮次(episode)、运行ID(run_id)、试验名称(trial_name)、最终结果(result)、验证器输出(verifier_output)以及追踪来源(trace_source)。数据集共包含3868个训练样本,总大小约368MB。适用于对话系统评估、模型行为分析、AI代理性能追踪、多轮对话生成等任务。
This dataset is a multi-turn dialogue dataset that records the interaction process between AI agents and users or systems. Each sample contains the complete dialogue history (roles and content), agent name, used model and model provider, conversation date, task description, episode, run_id, trial_name, final result, verifier_output, and trace_source. The dataset includes a total of 3868 training samples, with a total size of approximately 368MB. It is suitable for tasks such as dialogue system evaluation, model behavior analysis, AI agent performance tracking, and multi-turn dialogue generation.
数据集概述
该数据集名为 laion/dev_set_v2_a1_tulu3_sft_personas_math_20260815_140251,托管在 Hugging Face 平台(https://huggingface.co/datasets/laion/dev_set_v2_a1_tulu3_sft_personas_math_20260815_140251),是一个面向数学任务、基于人物角色(personas)微调的数据集。
基本信息
- 数据集大小:约 368.2 MB(下载大小约 303.2 MB)
- 划分:仅包含
train分割,共 3,868 条样本 - 文件格式:数据文件位于
data/train-*,为分片存储
数据结构
每个样本包含以下字段:
| 字段名 | 类型 | 说明 |
|---|---|---|
conversations |
列表(含 role 和 content 字段) |
对话记录,角色与内容 |
agent |
字符串 | 智能体标识 |
model |
字符串 | 模型名称 |
model_provider |
字符串 | 模型提供方 |
date |
字符串 | 日期 |
task |
字符串 | 任务类型 |
episode |
字符串 | 回合编号 |
run_id |
字符串 | 运行标识 |
trial_name |
字符串 | 试验名称 |
result |
字符串 | 结果 |
verifier_output |
字符串 | 验证器输出 |
trace_source |
字符串 | 追踪来源 |
用途
该数据集包含人物角色(personas)和数学(math)相关设定,可能用于训练或评估模型在特定角色情境下解决数学问题的能力,结合了 SFT(监督微调)数据格式,适合用于对话式数学推理任务的微调与验证。