MOMENT-DAPT-Scaling
收藏资源简介:
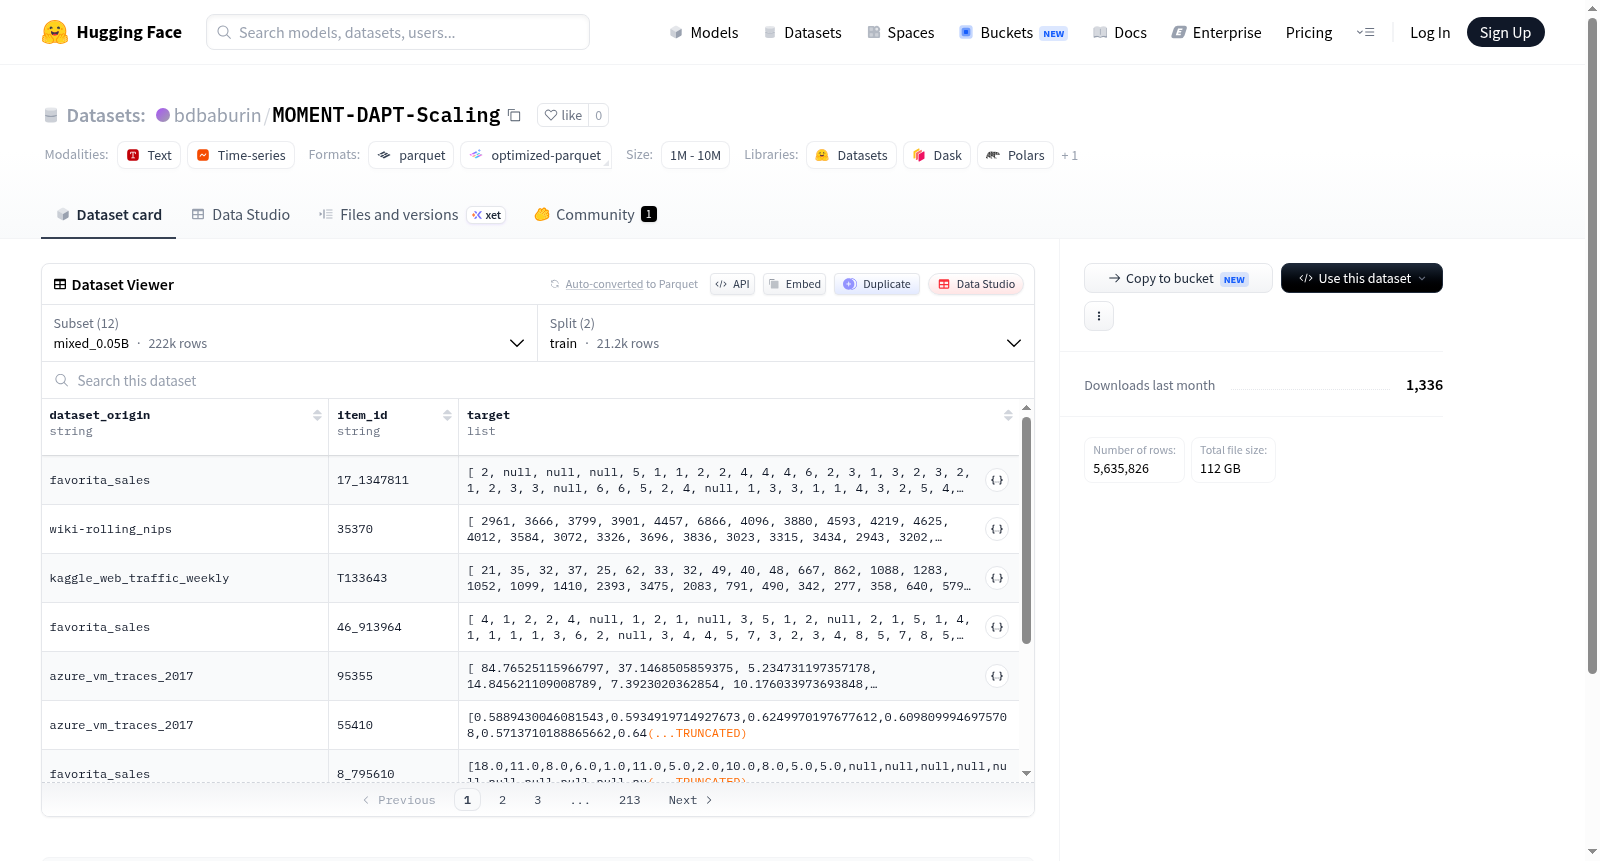
该数据集是一个结构化数据集,包含多个配置,每个配置对应不同的数据规模和类型(混合或纯)。数据集由训练集和验证集组成,每个样本包含三个特征:dataset_origin(字符串类型,标识数据来源)、item_id(字符串类型,唯一项目标识符)和target(浮点数列表,代表目标值)。配置名称以mixed(混合)或pure(纯)开头,后缀数字(如0.05B、0.1B、0.25B、0.5B、1.0B、2.0B)表示不同的数据规模等级(可能以亿计样本)。例如,mixed_0.05B配置的训练集包含21,212个样本,验证集包含201,025个样本;pure_2.0B配置的训练集包含804,030个样本,验证集包含201,025个样本。所有配置的验证集规模保持一致(201,025个样本),而训练集规模随配置等级增加而扩大。数据集适用于需要处理来源标识、项目ID和数值列表目标值的机器学习任务,例如回归、序列预测或多目标预测场景。
This dataset is a structured dataset containing multiple configurations, each corresponding to different data scales and types (mixed or pure). The dataset consists of a training set and a validation set, with each sample containing three features: dataset_origin (string type, identifying the data source), item_id (string type, unique item identifier), and target (a list of floating-point numbers, representing target values). Configuration names start with mixed (mixed) or pure (pure), followed by a suffix number (e.g., 0.05B, 0.1B, 0.25B, 0.5B, 1.0B, 2.0B) indicating different data scale levels (likely in hundreds of millions of samples). For example, the mixed_0.05B configuration has a training set with 21,212 samples and a validation set with 201,025 samples; the pure_2.0B configuration has a training set with 804,030 samples and a validation set with 201,025 samples. The validation set size is consistent across all configurations (201,025 samples), while the training set size increases with higher configuration levels. The dataset is suitable for machine learning tasks that require handling source identifiers, item IDs, and numerical list target values, such as regression, sequence prediction, or multi-target prediction scenarios.