
ZhJiHo/CBRN-JSTOR-History
收藏官方服务:
资源简介:
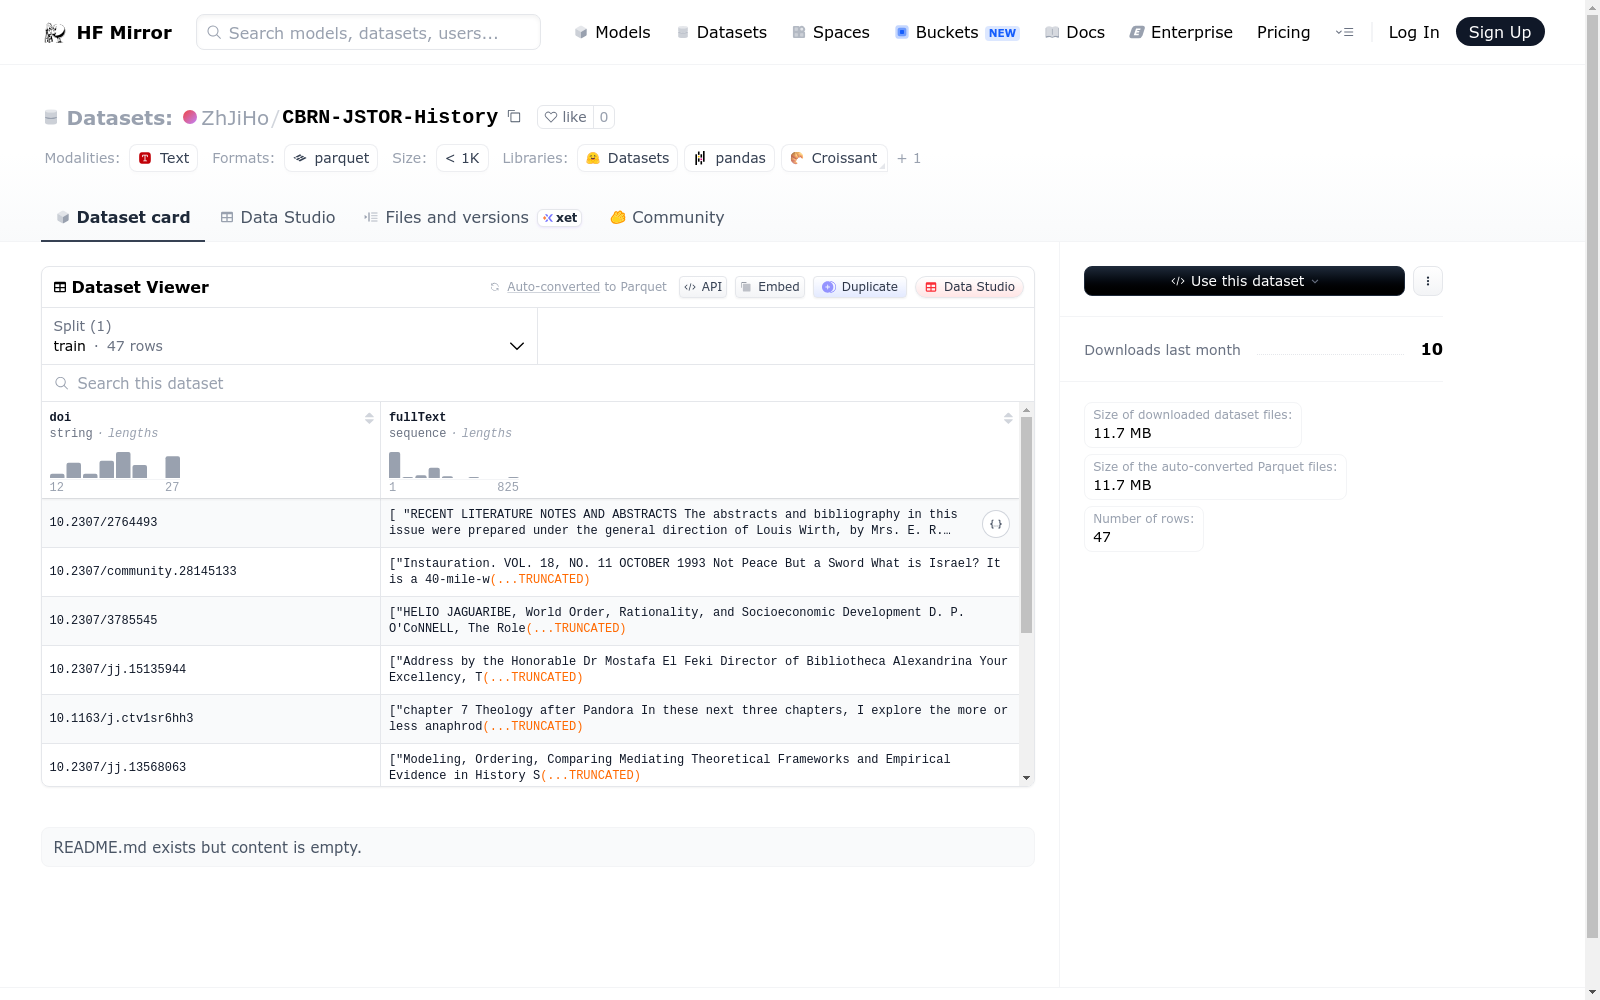
该数据集包含47个训练样本,每个样本包含doi和fullText两个特征。doi是字符串类型,表示文档的唯一标识符;fullText是字符串序列,表示文档的全文内容。数据集总大小为20030598字节,下载大小为11690115字节。数据集的默认配置指定了训练数据文件的路径。
This dataset contains 47 training samples, each with two features: doi and fullText. doi is of string type, representing the unique identifier of the document; fullText is a sequence of strings, representing the full text content of the document. The total size of the dataset is 20030598 bytes, with a download size of 11690115 bytes. The default configuration of the dataset specifies the path to the training data files.
提供机构:
ZhJiHo原始信息汇总
数据集概述
数据集信息
- 特征:
doi: 数据类型为字符串。fullText: 数据类型为字符串序列。
数据分割
- 训练集:
- 名称:
train - 字节数: 20030598
- 样本数: 47
- 名称:
数据集大小
- 下载大小: 11690115 字节
- 数据集大小: 20030598 字节
配置
- 配置名称:
default- 数据文件:
- 分割:
train - 路径:
data/train-*
- 分割:
- 数据文件:
搜集汇总
数据集介绍
背景与挑战
背景概述
该数据集是一个小型历史文献数据集,包含47条JSTOR文献记录,每条记录有DOI和全文文本两个字段,全文文本长度不等。数据集采用parquet格式,总大小为11.7MB,适合用于文本分析或历史研究。
以上内容由遇见数据集搜集并总结生成


