Oxford NINJAL Corpus of Old Japanese (ONCOJ)
收藏资源简介:
牛津-NINJAL古日语语料库(简称ONCOJ)是一个对古日语时期日本诗歌文本进行词形还原、解析和全面注释的数字语料库。该语料库自2011年开始创建(至2017年称为“牛津古日语语料库(OCOJ)”),作为牛津大学与国立日本语言与语言学研究所(NINJAL)之间的长期合作研究项目持续发展。
The Oxford-NINJAL Corpus of Old Japanese (ONCOJ) is a digital corpus that provides lemmatization, parsing, and comprehensive annotation of Japanese poetic texts from the Old Japanese period. Initiated in 2011 (known as the Oxford Corpus of Old Japanese (OCOJ) until 2017), this corpus has been developed as a long-term collaborative research project between the University of Oxford and the National Institute for Japanese Language and Linguistics (NINJAL).
数据集概述
数据集名称
Oxford NINJAL Corpus of Old Japanese (ONCOJ)
数据集描述
ONCOJ是一个数字化的、经过词形还原、解析和全面注释的古日语诗歌文本语料库。该语料库自2011年开始创建,是一个长期合作研究项目,由牛津大学与日本国立国语研究所(NINJAL)共同开发。
数据集格式
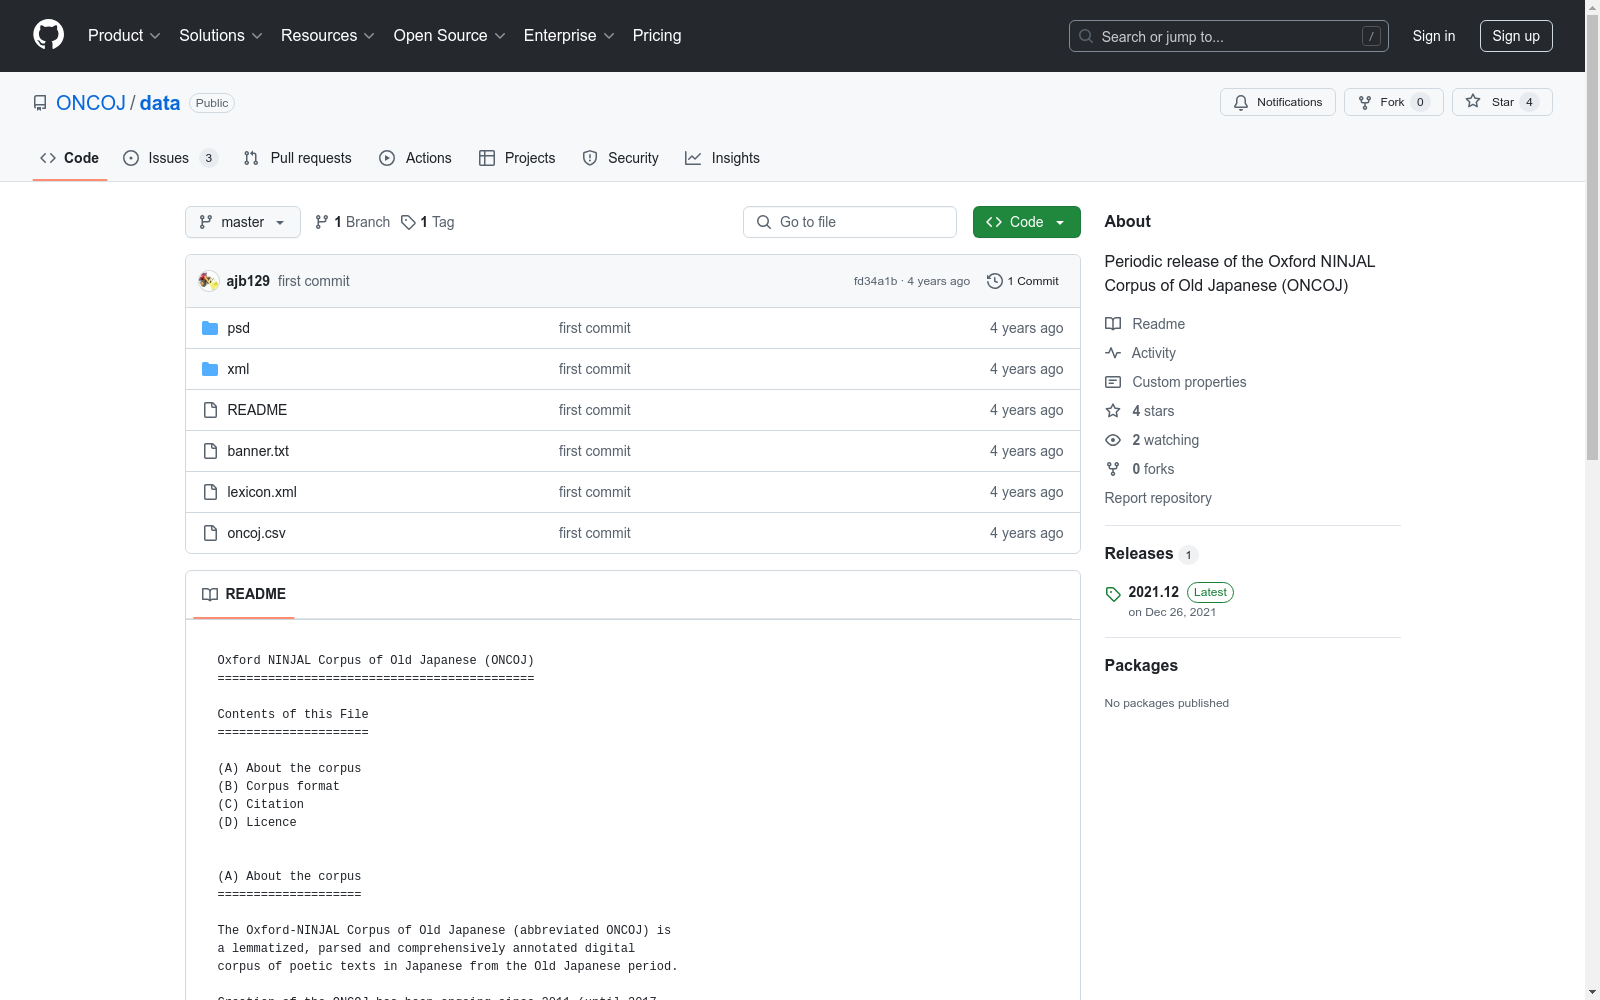
- lexicon.xml: 语料库的字典数据库,采用XML格式。
- oncoj.csv: 包含所有语料库数据的CSV文件,可通过电子表格程序查看。
- psd文件夹: 包含26个.psd文件,格式与CorpusSearch兼容。
- xml文件夹: 包含4991个独立的XML文件,每个文件对应一个文本,格式与TEI兼容。
引用格式
使用该语料库的研究成果应按照以下格式引用:
National Institute for Japanese Language and Linguistics (2021) “Oxford-NINJAL Corpus of Old Japanese” http://oncoj.ninjal.ac.jp/ (accessed 26 December 2021)
许可证
语料库的注释(语法分析)根据Creative Commons Attribution 4.0 International License授权。