hopchain-v40-1080p
收藏资源简介:
HopChain v4.0 + Vript 是一个专为强化学习可验证奖励(RLVR)训练设计的大规模多跳视频推理数据集。它整合了HopChain v4.0和Vript两个来源的数据,共包含28,865个多跳视频问题,覆盖7,396个视频。每个问题都附带一个可通过确定性规则验证的整数答案,无需在训练时依赖大型语言模型作为评判器。数据被划分为训练集(25,975行)和验证集(2,890行),划分确保没有视频同时出现在两个集合中。每个问题由3到7个“跳跃”组成(最常见的为4-5跳),每个跳跃涉及观察视频场景中的一个事实,并通过一个“如果<事实>则A否则B”的二元规则将其转化为一个数字,最终使用加法和乘法聚合成一个可验证的整数答案。问题涵盖了11种推理类型,包括存在、颜色、动作、共现、场景、算术、顺序、首尾、属性匹配、重复和状态变化。数据集中,HopChain v4.0部分包含6,692个问答对,基于1,748个多样化的YouTube视频(通常20-60秒),并使用1080p级别的字幕。Vript部分包含22,173个问答对,基于5,648个更长的视频(中位数7分12秒),这些视频带有密集的场景标注并经过重新字幕生成。两个来源都通过相同的HopChain流水线处理,确保问题格式、系统提示和奖励契约一致。每条数据记录都是一个完整的、与verl框架兼容的提示,结构化为JSON格式。它包含系统提示、用户问题(结合了视频和文本问题)、视频元数据(路径、帧率、最大帧数等)、数据源标识、能力标签、奖励模型信息(包含真实答案)以及一个“extra_info”字段。该额外信息字段提供了答案、跳跃数量、跳跃类型列表、解决率(基于一个训练模型在8次运行中的成功率,可用于课程学习采样)和难度等级(绝大多数为“困难”)。该数据集适用于训练和评估视频多跳推理模型,特别侧重于需要可验证、逐步推理能力的强化学习场景。其设计通过“过易过滤器”和“盲解过滤器”旨在消除简单或仅依赖语言线索即可解决的问题,确保推理挑战的真实性。
HopChain v4.0 + Vript is a large-scale multi-hop video reasoning dataset designed for reinforcement learning with verifiable rewards (RLVR) training. It integrates data from two sources, HopChain v4.0 and Vript, containing a total of 28,865 multi-hop video questions covering 7,396 videos. Each question comes with a verifiable integer answer that can be validated through deterministic rules, eliminating the need to rely on large language models as judges during training. The data is split into a training set (25,975 rows) and a validation set (2,890 rows), with the split ensuring no video appears in both sets. Each question consists of 3 to 7 hops (most commonly 4-5 hops), where each hop involves observing a fact in a video scene and transforming it into a number via a binary if <fact> then A else B rule, ultimately aggregated using addition and multiplication into a verifiable integer answer. The questions cover 11 reasoning types, including existence, color, action, co-occurrence, scene, arithmetic, order, first/last, attribute matching, repetition, and state change. In the dataset, the HopChain v4.0 portion includes 6,692 question-answer pairs based on 1,748 diverse YouTube videos (typically 20-60 seconds) with 1080p-level captions. The Vript portion includes 22,173 question-answer pairs based on 5,648 longer videos (median 7 minutes 12 seconds) that feature dense scene annotations and have been re-captioned. Both sources are processed through the same HopChain pipeline to ensure consistency in question format, system prompts, and reward contracts. Each data record is a complete prompt compatible with the verl framework, structured in JSON format. It includes a system prompt, user question (combining video and text questions), video metadata (path, frame rate, maximum frames, etc.), data source identifier, capability labels, reward model information (including the true answer), and an extra_info field. This extra info field provides the answer, number of hops, list of hop types, solve rate (based on a trained models success rate over 8 runs, usable for curriculum learning sampling), and difficulty level (mostly hard). The dataset is suitable for training and evaluating video multi-hop reasoning models, with a particular focus on reinforcement learning scenarios requiring verifiable, step-by-step reasoning capabilities. Its design incorporates too-easy filters and blind-solution filters to eliminate problems that are trivial or solvable solely through language cues, ensuring the authenticity of the reasoning challenge.
数据集概述:HopChain v4.0 + Vript — 多跳视频推理数据集
基本信息
- 数据集名称: HopChain v4.0 + Vript
- 许可协议: Apache-2.0
- 任务类型: 视频-文本到文本(Video-Text-to-Text)、问答(Question-Answering)
- 语言: 英语(en)
- 数据集规模: 10K < n < 100K(共 28,865 条问答对)
- 标签: 视频、多跳推理、RLVR、可验证奖励、强化学习
数据规模与构成
| 划分 | 行数 | HopChain来源 | Vript来源 | 视频数量 | 跳数分布(3/4/5/6/7) | 解决率 |
|---|---|---|---|---|---|---|
| 训练集 | 25,975 | 6,004 | 19,971 | 6,657 | 523 / 4,957 / 9,438 / 8,013 / 3,044 | 0.0081 |
| 验证集 | 2,890 | 688 | 2,202 | 739 | 46 / 557 / 1,071 / 879 / 337 | 0.0088 |
| 总计 | 28,865 | 6,692 | 22,173 | 7,396 | 569 / 5,514 / 10,509 / 8,892 / 3,381 | 0.0082 |
- 视频去重划分:使用种子值 42 确保训练集和验证集之间无视频重叠。
数据来源
HopChain v4.0
- 问答对数量: 6,692 / 视频数量: 1,748
- 视频质量: 1080p,基于字幕的多跳条件谓词推理
- 视频来源: 多样化的YouTube视频
- 视频时长: 20–60秒
Vript
- 问答对数量: 22,173 / 视频数量: 5,648
- 视频来源: 高质量YouTube视频,具有密集场景级注释(镜头类型、摄像机运动、内容、画外音)
- 原始视频数量: ~11,000,筛选后使用8,046个视频(>3分钟,中位数7分12秒,平均9分钟)
- 视频时长: 3–7分钟,提供更丰富的时序推理机会
数据集核心特性
多跳推理
- 每个问题包含 3–6 个条件谓词跳数(模式:4–5 跳)
- 每跳观察一个场景的稳健事实,通过二元规则转换为数字(
if <事实> then A else B),再通过+ *聚合为单个可验证整数
11种推理类型
- 原始类型(6种): 存在性(existence)、颜色(color)、动作(action)、共现(cooccur)、场景(setting)、算术(arithmetic)
- 跨场景新类型(5种): 顺序(order)、首尾(first_last)、属性匹配(attr_match)、重复(recurrence)、状态变化(state_change)
可验证答案
- 每个问题有 整数地面真实答案,可通过规则检查(无需LLM裁判)
- 专为 RLVR(强化学习与可验证奖励) 训练设计
难度过滤
- 使用训练模型(Qwen3-VL-8B-Instruct,140帧)进行8次运行探测,若解决率 ≥ 6/8 则剔除(过于简单的问题)
数据模式(Schema)
每条记录包含完整兼容的提示格式:
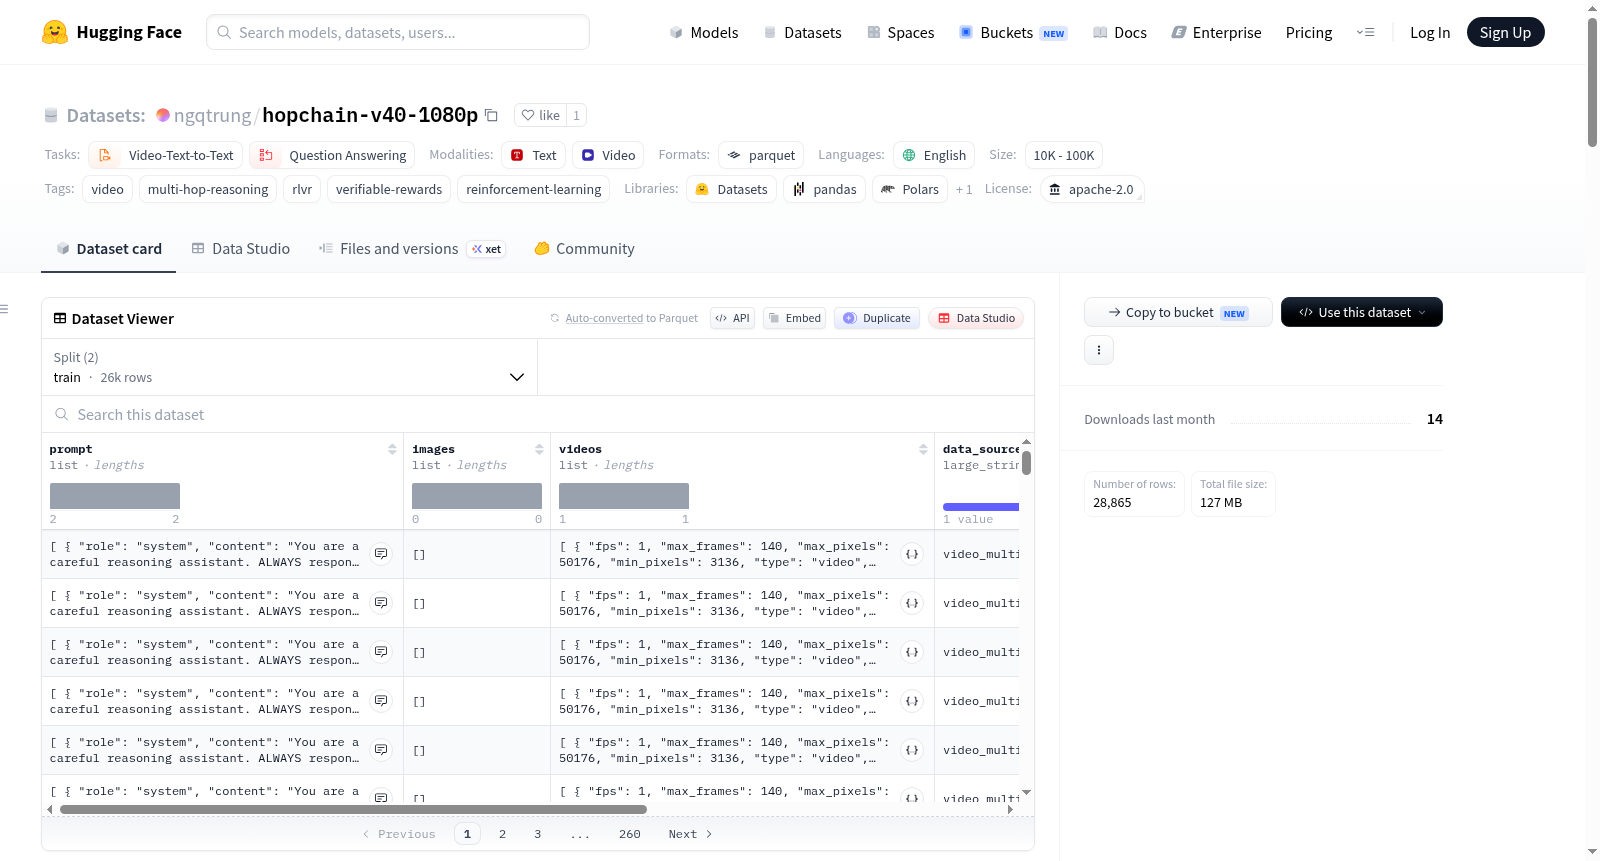
json { "prompt": [ {"role": "system", "content": "你是细心的推理助手..."}, {"role": "user", "content": "<video> <问题>"} ], "videos": [{"type": "video", "video": "路径/视频.mp4", "fps": 1, "max_frames": 140, "min_pixels": 3136, "max_pixels": 50176}], "reward_model": {"ground_truth": "42", "style": "rule"}, "extra_info": { "reward_type": "numeric", "answer": "42", "answer_type": "numeric", "num_hops": 5, "hop_types": ["order", "cooccur", "action", "color", "arithmetic"], "question_id": "VIDEOID_hq000", "video_id": "VIDEOID", "solve_rate": 0.0, "difficulty_band": "hard" } }
关键字段
reward_model.ground_truth: 整数答案(精确匹配奖励)extra_info.num_hops: 条件谓词观察跳数extra_info.hop_types: 每跳的推理类型列表extra_info.solve_rate: 训练模型8次运行中解决的比例(用于课程采样)extra_info.difficulty_band: 难度等级("hard" 99.5%,"medium","easy")
数据处理流程
数据生成流水线
- 字幕生成: 使用397B-FP8模型从视频帧生成密集字幕(HopChain: 1080p原始字幕;Vript: 从场景注释重新生成字幕)
- 问题生成: 397B-FP8模型为每个视频生成5个候选问题
- 评判筛选: 27B模型对候选问题评分,选择最佳
- 过易过滤: 8B-VL模型对每个问题探测8次,解决率 ≥ 6/8 则剔除
- 盲解过滤: 移除仅依赖语言的快捷方式(比率0.071)
数据规模过滤漏斗
HopChain v4.0:
| 阶段 | 数量 |
|---|---|
| 输入视频 | 1,818 |
| 处理视频 | 1,787(98.3%) |
| 候选问题 | 14,021 |
| 评判幸存 | 7,539(53.8%) |
| 最终保留 | 6,692(3.74/视频) |
Vript:
| 阶段 | 数量 |
|---|---|
| 输入视频 | 8,046 |
| 处理视频 | ~5,800 |
| 最终保留 | 22,173(3.82/视频) |
课程采样建议
利用 solve_rate 字段进行课程训练:
- 热身阶段: 选择 solve_rate > 0 的样本(较简单,3–4跳,简单推理类型)
- 退火阶段: 进入 solve_rate = 0 的困难尾部(5–7跳,99.5% 困难样本)
注意事项
- 混合字幕模型: HopChain视频中144/1,818由122B模型生成字幕,其余由397B-FP8生成;Vript全部由397B重新生成字幕
- 生成过程不访问原始帧: 字幕是唯一地面真实信息,盲解率(0.071)为快捷方式上限
- 视频去重划分: 确保训练集和验证集之间无视频泄漏
引用
bibtex @misc{hopchain2026, title={HopChain: Harder Multi-Hop Video Reasoning with Verifiable Answers}, author={Trung, Ng Quang}, year={2026}, howpublished={\url{https://huggingface.co/datasets/ngqtrung/hopchain-v40-1080p}} }