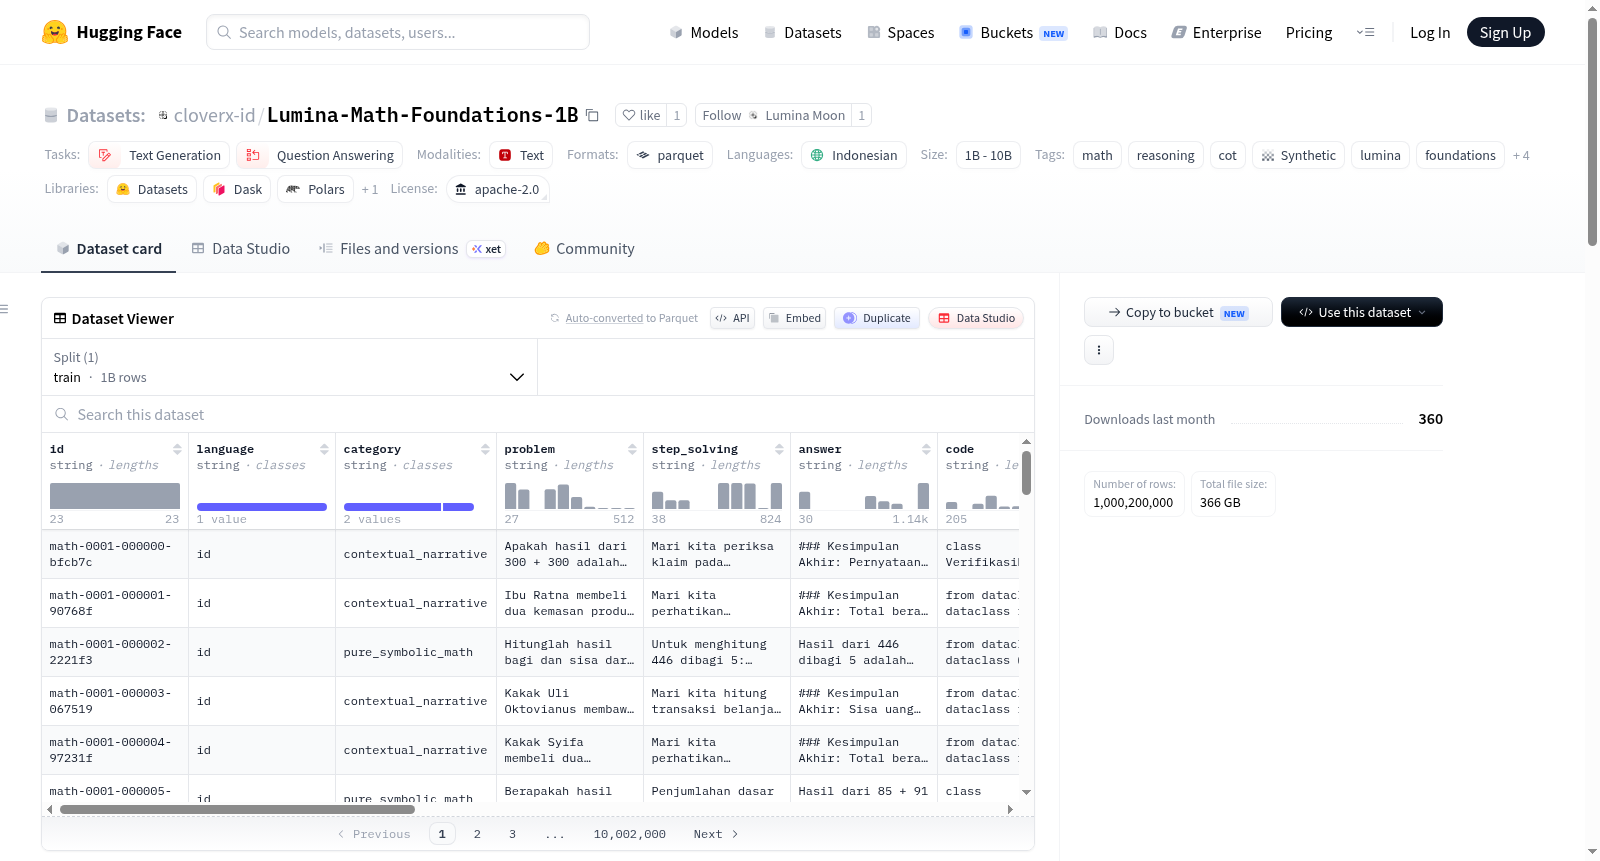
Lumina-Math-Foundations-1B
收藏资源简介:
Lumina-Math-Foundations-1B 是一个大规模、工业级的基础数学推理数据集,使用印尼语编写,并包含 LaTeX 数学公式。该数据集基于 V18.0 自适应面向对象编程与密码学熵引擎构建,包含 10 亿个高质量合成数学推理样本。每个样本包含纯自然语言问题陈述、逐步链式思维推理、最终答案、完整的 Python 实现代码(基础问题使用动态函数代码,高阶问题使用企业级 @dataclass OOP 架构)、用于智能体工作流的函数/工具调用 JSON 载荷、外部解释器/求解器的执行结果,以及用于程序化可验证奖励强化学习(RLVR)的确定性验证标准。数据集适用于文本生成和问答任务,特别是数学推理场景,支持链式思维(CoT)模式和智能体代码解释器模式。数据采用 Apache-2.0 许可证发布。
Lumina-Math-Foundations-1B is a large-scale, industrial-grade foundational mathematical reasoning dataset, written in Indonesian (id) and containing LaTeX mathematical formulas. The dataset is built based on the V18.0 adaptive object-oriented programming and cryptographic entropy engine, containing 1 billion high-quality synthetic mathematical reasoning samples. Each sample includes a pure natural language problem statement, step-by-step chain-of-thought reasoning, final answer, complete Python implementation code (dynamic function code for basic problems, enterprise-level @dataclass OOP architecture for advanced problems), function/tool call JSON payloads for agent workflows, execution results from external interpreters/solvers, and deterministic verification criteria for programmatically verifiable reward reinforcement learning (RLVR). The dataset is suitable for text generation and question answering tasks, especially mathematical reasoning scenarios, supporting chain-of-thought (CoT) mode and agent code interpreter mode. The data is released under the Apache-2.0 license.
数据集概述
Lumina-Math-Foundations-1B 是一个工业级、大规模的基础数学推理数据集,使用印度尼西亚语(id)编写,并包含 LaTeX 数学公式,规模达 10 亿条合成的高保真数学推理样本。该数据集基于 V18.0 自适应 OOP 与密码学熵引擎构建,旨在为数学推理、思维链(CoT)和基于可验证奖励的强化学习(RLVR)提供支持。
核心特性
- 语言: 印度尼西亚语(
id),数学公式采用 LaTeX 格式。 - 规模: 10 亿(1B)条合成数学推理实例。
- 架构范式: 纯自然语言思维链(CoT)+ 企业级面向对象编程(OOP)代码 + 可编程验证负载。
- 引擎: V18.0 密码学硬件熵(
os.urandom),具备严格去重和模式一致性。 - 许可证: Apache-2.0
数据模式(字段说明)
| 字段名 | 类型 | 描述 |
|---|---|---|
id |
string |
样本唯一标识符 |
language |
string |
语言标识 |
category |
string |
题目类别 |
problem |
string |
100% 纯自然语言问题陈述,含标准 LaTeX 数学格式 |
step_solving |
string |
逐步的严谨逻辑思维链(CoT)数学推理过程 |
answer |
string |
提取的规范最终答案或解值 |
code |
string |
完整 Python 实现。基础问题使用动态函数式代码;高级问题严格采用企业级 @dataclass OOP 架构 |
ground_truth |
string |
标准答案 |
tool_calls_json |
string |
隔离的 JSON 负载,指定代理工作流的函数/工具调用模式 |
tool_responses_json |
string |
外部解释器/求解器的执行结果 |
verification_payload |
string |
用于程序化可验证奖励强化学习(RLVR)的确定性验证标准 |
length_bucket |
string |
长度分桶 |
difficulty |
string |
难度等级 |
cluster |
string |
聚类信息 |
created_at |
string |
创建时间 |
数据集划分
- 划分名称:
train - 样本数量: 1,000,000,000(10 亿)
- 文件格式: Parquet(
data/*.parquet)
推荐使用格式
1. 思维链(CoT)模式(ChatML)
<|im_start|>user {problem}<|im_end|> <|im_start|>assistant <thought> {step_solving} </thought> Jawaban akhir: {answer}<|im_end|>
2. 代理式代码解释器模式
<|im_start|>user {problem}<|im_end|> <|im_start|>assistant <thought> {step_solving} </thought> {code} <|im_end|>
任务类型与标签
- 任务类别: 文本生成、问答
- 标签: 数学、推理、思维链、合成数据、基础模型、代理式、企业OOP、urandom熵、RLVR
引用信息
bibtex @dataset{luminamath1b2026, author = {XoneMi, Third Prince and Lumina AI Research Laboratories}, title = {Lumina-Math-Foundations-1B: Industrial Foundational Mathematical Reasoning Dataset}, year = {2026}, publisher = {Hugging Face}, url = {https://huggingface.co/datasets/cloverx-id/Lumina-Math-Foundations-1B} }