gene-llm-agents-corpus
收藏资源简介:
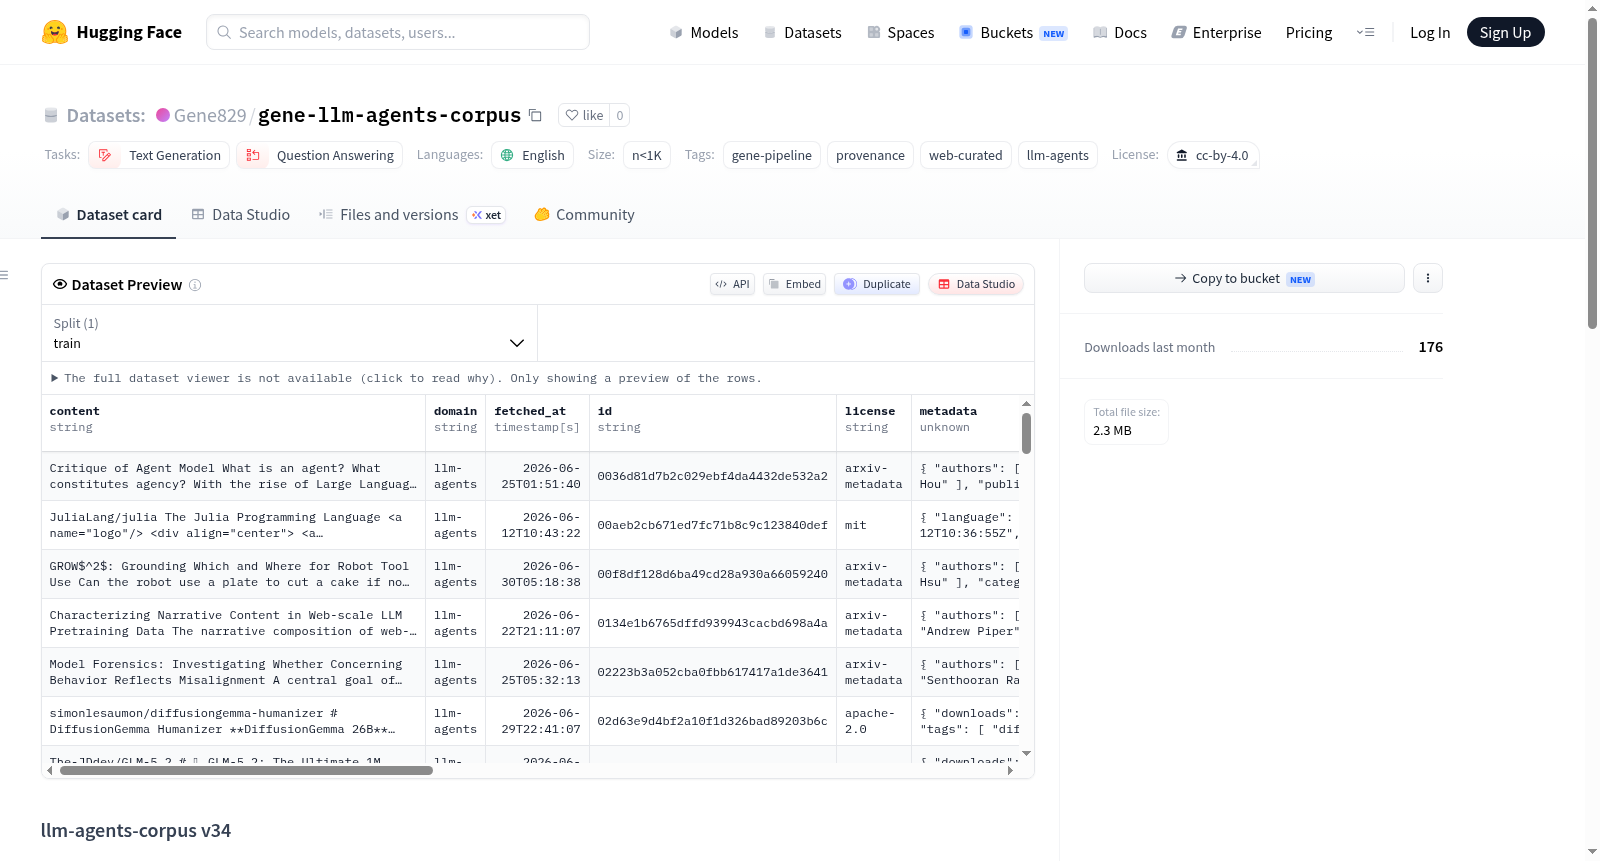
llm-agents-corpus v8 是一个专注于大型语言模型代理领域的文本语料库数据集,通过Gene管道构建,该管道注重数据来源和可重现性。数据来源包括Hugging Face、学术论文、ArXiv和GitHub,仅使用宽松许可证(如Apache-2.0、MIT、CC BY 4.0等)的内容。数据集包含449条记录,每条记录都携带其来源信息,确保可追溯性。数据构建过程经过严格的六阶段筛选:生成、批判与修订编辑、LLM评判、对抗性第二评判、证据验证(每条保留的数据对都包含可证明出现在原始来源中的引用)以及代码的沙箱执行。数据集支持通过manifest.json文件完全重现,保证字节级一致性(SHA-256验证)。该数据集适用于文本生成和问答等自然语言处理任务,旨在为LLM代理相关研究提供高质量、可验证的训练数据。
llm-agents-corpus v8 is a text corpus dataset focused on the field of large language model agents, constructed through the Gene pipeline, which emphasizes data provenance and reproducibility. Data sources include Hugging Face, academic papers, ArXiv, and GitHub, using only content under permissive licenses such as Apache-2.0, MIT, CC BY 4.0, etc. The dataset contains 449 records, each carrying its source information to ensure traceability. The data construction process undergoes rigorous six-stage filtering: generation, critique and revision editing, LLM judging, adversarial second judging, evidence verification (each retained data pair includes citations that can be proven to appear in the original source), and sandbox execution of code. The dataset supports full reproducibility via a manifest.json file, ensuring byte-level consistency (SHA-256 verification). It is suitable for natural language processing tasks such as text generation and question answering, aiming to provide high-quality, verifiable training data for LLM agent-related research.