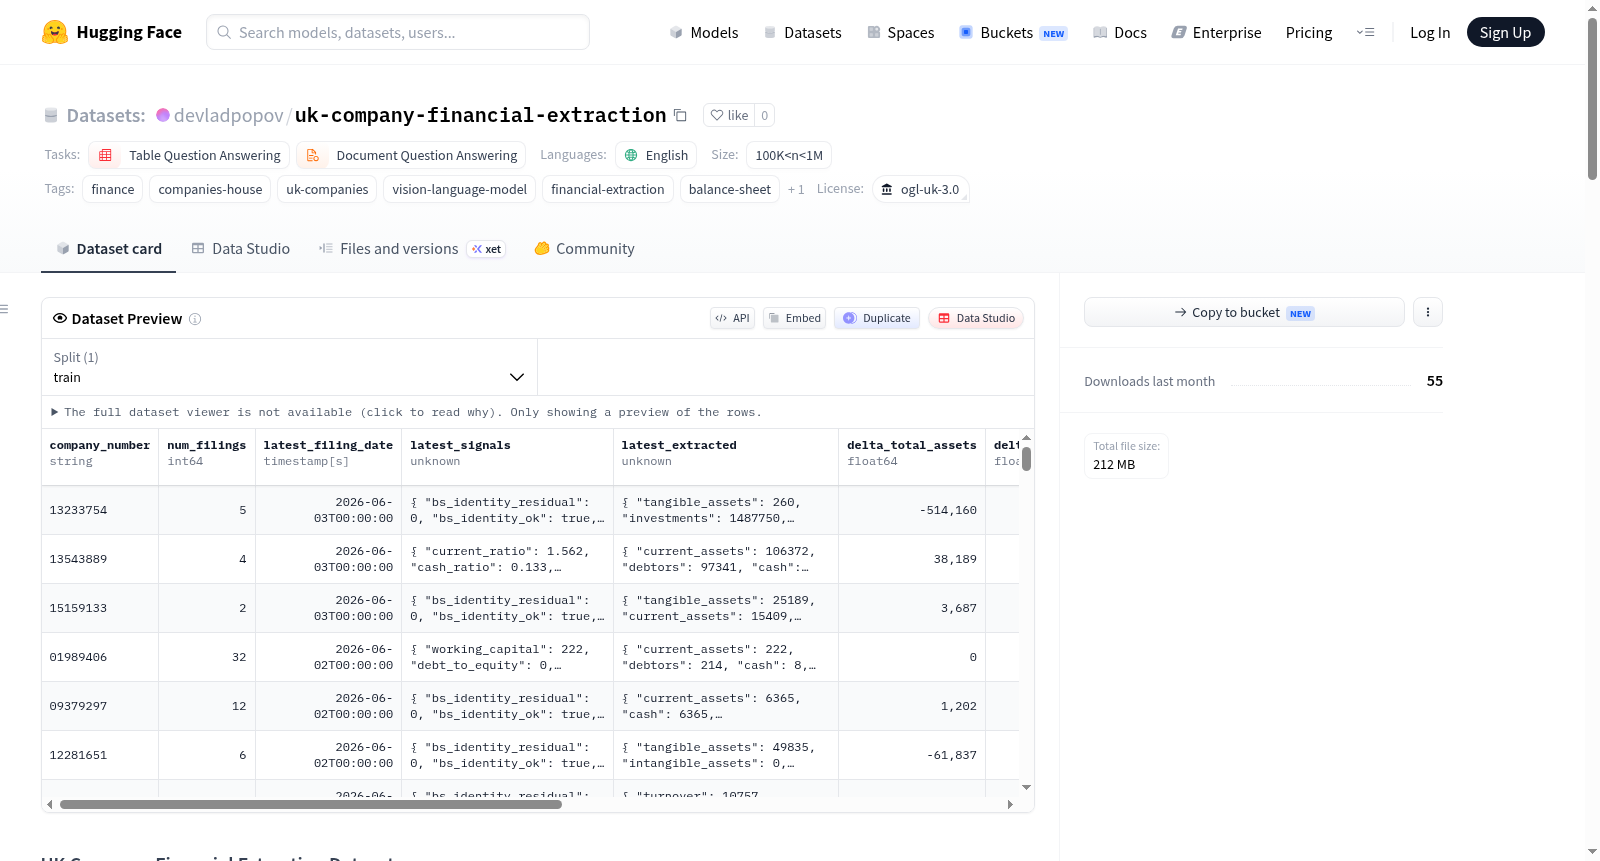
uk-company-financial-extraction
收藏资源简介:
UK Company Financial Extraction Dataset 是一个从英国公司注册处(Companies House)公开的 PDF 年度账目文件中,利用 Qwen2.5-VL-72B-Instruct 视觉语言模型提取并结构化财务数据的数据集。该数据集旨在为金融分析、公司风险评分、表格问答和文档问答等任务提供高质量的财务信息。数据集核心内容包含公司申报级别的资产负债表、损益表数据以及一系列计算得出的衍生财务信号,具体包含 124,273 条申报记录,覆盖 43,789 家独特的英国公司,其中 11,731 家公司拥有多个时期的申报数据。每条记录包含从 PDF 中直接提取的字段(如公司编号、总资产、营业额等)和衍生信号(如流动性指标、杠杆指标、风险评分等),并提供了平衡表恒等式检查和质量标志。根据评估,字段级提取准确率为 86.6%,文档级准确率为 56.9%,平衡表恒等式通过率为 97.7%。数据在 Open Government Licence v3.0 许可下提供。
UK Company Financial Extraction Dataset is a dataset that extracts and structures financial data from publicly available PDF annual account files of the UK Companies House using the Qwen2.5-VL-72B-Instruct vision-language model. It aims to provide high-quality financial information for tasks such as financial analysis, company risk scoring, table question answering, and document question answering. The core content includes company filing-level balance sheet and profit and loss statement data, along with a series of calculated derivative financial signals, specifically containing 124,273 filing records covering 43,789 unique UK companies, with 11,731 companies having multiple period filing data. Each record includes fields directly extracted from PDFs (such as company number, total assets, turnover, etc.) and derivative signals (such as liquidity indicators, leverage indicators, risk scores, etc.), and provides balance sheet identity checks and quality flags. According to evaluations, the field-level extraction accuracy is 86.6%, document-level accuracy is 56.9%, and balance sheet identity pass rate is 97.7%. The data is provided under the Open Government Licence v3.0.
数据集概述
数据集名称:UK Company Financial Extraction Dataset
数据集地址:https://huggingface.co/datasets/devladpopov/uk-company-financial-extraction
语言:英语
任务类别:表格问答、文档问答
标签:金融、公司注册、英国公司、视觉语言模型、财务提取、资产负债表、风险评分
许可协议:开放政府许可证 v3.0(OGL-UK-3.0)
数据集描述
该数据集包含从英国公司注册处(Companies House)PDF年度账目中提取的结构化财务数据。提取过程使用了Qwen2.5-VL-72B-Instruct视觉语言模型,运行于NVIDIA GH200 Grace Hopper节点(Isambard-AI Phase 2, BriCS)。
数据来源
所有输入PDF均来自公司注册处,在开放政府许可证v3.0下公开可用,不包含专有或个人数据。
提取流程
- 模型:Qwen2.5-VL-72B-Instruct(bfloat16,2×GH200 GPU张量并行)
- 流程:v4.5c单次多层级提取
- 准确率:
- 150文档开发集:字段级88.8%
- 2,656文档保留集:字段级86.6%,文档级56.9%
- 一致性:资产负债表恒等式通过率97.3%
文件内容
| 文件 | 记录数 | 说明 |
|---|---|---|
filing_signals.jsonl |
124,273 | 每份申报的提取字段及衍生信号 |
company_signals.jsonl |
43,789 | 每家公司的汇总及轨迹标签 |
inference_predictions_merged.jsonl |
124,273 | 原始预测结果(信号输入) |
schema.json |
1 | 字段定义与类型 |
数据模式(filing_signals.jsonl)
提取字段(来自PDF):
company_number、filing_date、pdf_pathtotal_assets、net_assets、current_assets、current_liabilitiescash、debtors、stocks、tangible_assets、intangible_assetsinvestments、share_capital、turnover、operating_profitprofit_before_tax、profit_after_tax、employees
衍生信号(计算所得):
- 流动性:
current_ratio、quick_ratio、cash_ratio、working_capital - 杠杆:
debt_to_equity、gearing - 偿付能力:
negative_net_assets、negative_working_capital、insolvency_proxy - 盈利能力:
operating_margin、pretax_margin、net_margin - 规模:
size_class(micro/small/medium/large) - 质量:
bs_identity_ok(资产负债表恒等式校验) - 综合:
risk_score(0-100)、risk_band(clean/low/medium/high)
关键统计
- 总申报数:124,273
- 涵盖公司数:43,789
- 多期公司数:11,731(占26.8%,至少有2份申报)
风险分布:
| 风险等级 | 占比 |
|---|---|
| clean | 49.7% |
| low | 8.8% |
| medium | 15.7% |
| high | 25.8% |
多期轨迹(占多期公司比例):
| 轨迹 | 占比 |
|---|---|
| stable | 46.6% |
| improving | 31.3% |
| deteriorating | 20.1% |
资产负债表恒等式通过率:97.7%
字段级准确率(2,656文档保留集):
- cash 95.7%、current_assets 92.6%、share_capital 91.8%、turnover 91.5%
- operating_profit 90.1%、tangible_assets 88.8%、debtors 88.2%
- total_assets 87.8%、employees 84.9%、profit_before_tax 83.2%
- net_assets 80.7%、intangible_assets 64.3%、profit_after_tax 49.4%
- 总体:86.6%
版本历史
- v3(2026年7月):124,273份申报。新增约53,500份历史申报,多期覆盖率从8.7%提升至26.8%
- v2(2026年6月):70,722份申报,43,789家公司
- v1(2026年6月):49,625份申报