kupe-asr-en-data
收藏资源简介:
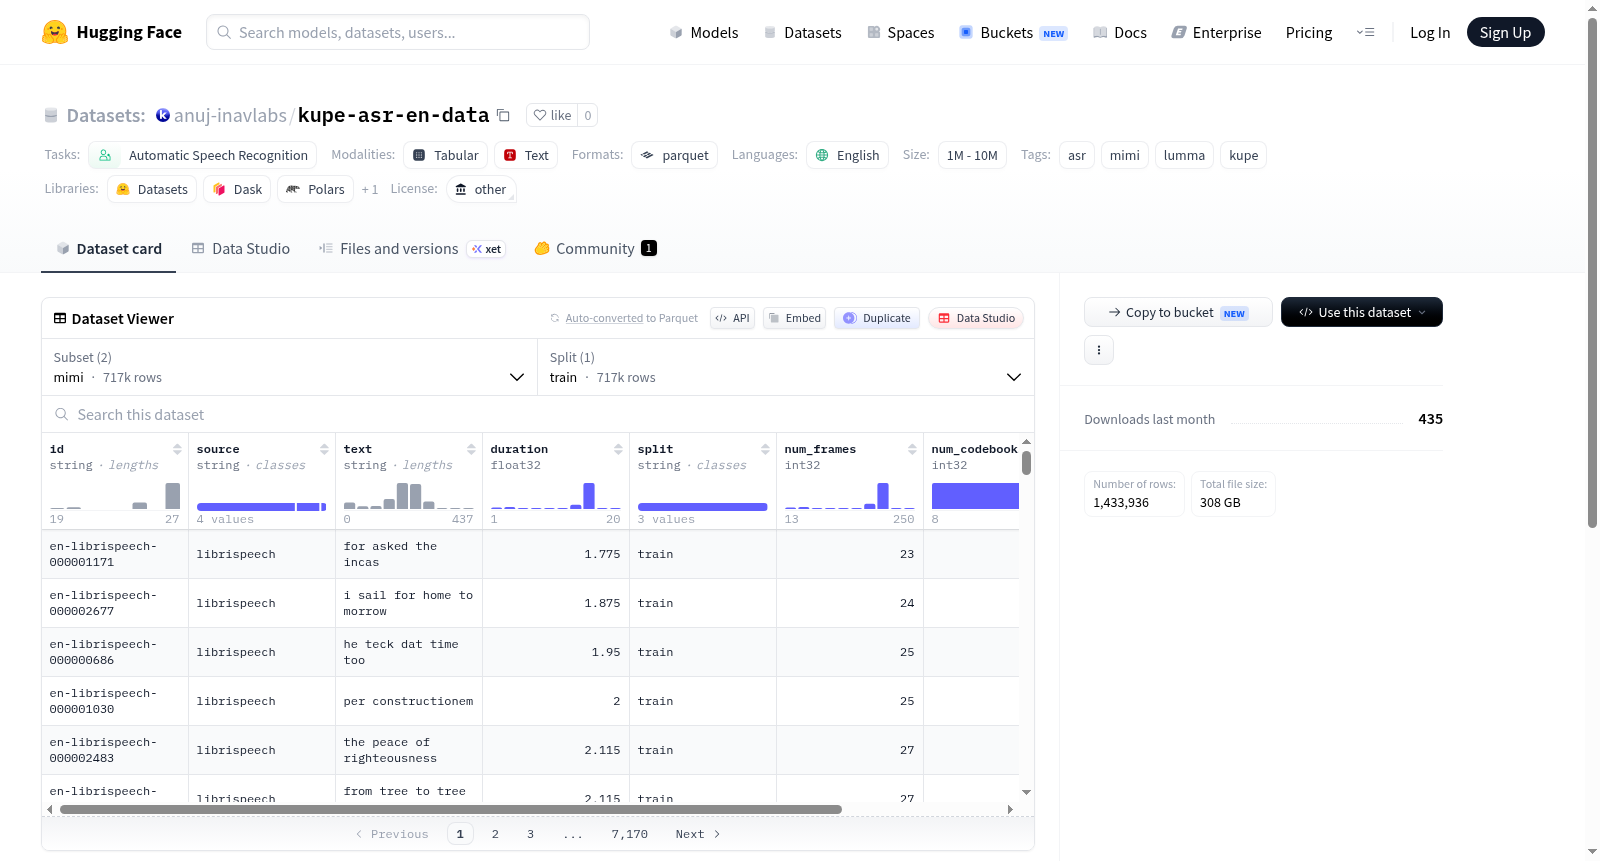
该数据集为英语自动语音识别(ASR)任务设计,包含两个可加载配置:raw和mimi。raw配置提供24 kHz单声道英语音频(以FLAC格式存储)及其对应的文本转录;mimi配置提供Mimi编码器生成的c0至c7编码(帧率为12.5 Hz)以及对应的文本。每个配置的数据以约20-25个parquet文件(bunch_*.parquet)形式组织,便于在Hugging Face Hub上高效存储和加载。此外,数据集中还包含ledger目录,用于跟踪已收集和已编码的音频时长以及恢复状态。该数据集适用于训练和评估语音识别模型,以及基于离散编码的语音表示学习。
This dataset is designed for English automatic speech recognition (ASR) tasks. It provides two configurable subsets: raw and mimi. The raw subset offers 24 kHz mono English audio stored in FLAC format along with corresponding text transcriptions. The mimi subset provides c0 to c7 encodings generated by the Mimi encoder at a frame rate of 12.5 Hz, along with the corresponding text. Each subset is organized into approximately 20-25 parquet files (bunch_*.parquet) for efficient storage and loading on the Hugging Face Hub. Additionally, the dataset includes a ledger directory to track the duration of collected and encoded audio and recovery status. This dataset is suitable for training and evaluating speech recognition models, as well as representation learning based on discrete encodings.
数据集概述
kupe-asr-en-mini-150m — data 是一个用于英语自动语音识别(ASR)的数据集,支持两种加载配置,旨在为模型训练和编码阶段提供灵活的数据格式。
主要配置
raw配置:包含 24 kHz 单声道英语音频(以 FLAC 字节存储)及对应的文本转录。此配置用于编码步骤,即从原始音频生成特征表示。数据文件存储在raw/data/bunch_*.parquet路径中。mimi配置:包含 Mimi 编码器的 c0 至 c7 码本(采样率为 12.5 Hz)及文本转录。此配置直接用于模型训练过程。数据文件存储在mimi/data/bunch_*.parquet路径中。
文件结构
- 每个配置包含约 20 至 25 个
bunch_*.parquet文件,方便 Hub 配额管理。 - 在
ledger/目录下保留账本文件(data.json和mimi.json),用于跟踪已收集和已编码的音频时长,并记录处理状态的恢复点。
加载示例
用户可通过以下 Python 代码加载 mimi 配置的数据:
python
from datasets import load_dataset
ds = load_dataset("anuj-inavlabs/kupe-asr-en-data", "mimi", split="train")
元数据
- 许可证:
other(非标准自定义许可) - 任务类型:自动语音识别(automatic-speech-recognition)
- 语言:英语(
en) - 相关标签:
asr、mimi、lumma、kupe