
VRU-Accident
收藏资源简介:
VRU-Accident是一个大规模的视觉-语言基准数据集,旨在评估多模态大型语言模型(MLLMs)在高风险交通场景中,特别是涉及脆弱道路用户(VRUs)的场景中的推理和描述能力。该数据集包含1000个真实世界的事故和近事故视频,这些视频被标注了6000个多项选择题问答对,涵盖六个安全关键类别(共有24000个候选选项和3400个独特答案选择),以及1000个密集的场景描述。VRU-Accident数据集的创建过程包括从网络资源中检索事故视频,并由人类专家手动筛选。对于每个视频,首先由人类专家为每个问题标注一组答案,然后VQA生成器生成三个反事实答案,同时使用密集描述生成器为每个视频生成一个密集的事故描述。所有标注均由人类专家验证后最终确定。该数据集的创建旨在解决自动驾驶系统中对脆弱道路用户安全性的挑战,并推动多模态语言模型在交通事故理解和推理方面的研究。
VRU-Accident is a large-scale vision-language benchmark dataset designed to evaluate the reasoning and description capabilities of multimodal large language models (MLLMs) in high-risk traffic scenarios, particularly those involving vulnerable road users (VRUs). This dataset contains 1,000 real-world accident and near-accident videos, annotated with 6,000 multiple-choice question-answer pairs spanning six safety-critical categories (with a total of 24,000 candidate options and 3,400 unique answer choices), as well as 1,000 dense scene descriptions. The creation of the VRU-Accident dataset involves retrieving accident videos from web resources and manually screening them by human experts. For each video, human experts first annotate a set of answers for each question, then the VQA generator generates three counterfactual answers, while a dense caption generator generates one dense accident description for each video. All annotations are finally finalized after being verified by human experts. This dataset is developed to address the challenges of vulnerable road user safety in autonomous driving systems and advance research on traffic accident understanding and reasoning for multimodal language models.
VRU-Accident 数据集概述
数据集基本信息
- 数据集名称: VRU-Accident
- 研究团队: Younggun Kim, Ahmed S. Abdelrahman*, Mohamed Abdel-Aty (University of Central Florida)
- 对应作者: Ahmed S. Abdelrahman
- 数据集类型: 视觉-语言基准测试
- 应用领域: 自动驾驶、事故分析
- 数据内容: 涉及弱势道路使用者(VRUs)的真实交通事故视频
数据集特点
- 首创性: 首个专注于VRU相关交通事故的视觉语言基准测试
- 任务支持:
- 视频问答(Video Question Answering)
- 密集描述生成(Dense Captioning)
- 核心目标: 评估多模态大语言模型(MLLMs)在安全关键场景中的表现
数据规模与标注
- 视频数量: 1,000个真实行车记录仪事故视频
- 问答标注:
- 6,000个多选题问答对
- 覆盖6个安全关键类别
- 24,000个候选选项
- 3,400个唯一答案选项
- 描述标注: 1,000个密集场景描述
标注特性
- 细粒度分析: 捕捉事故的时空动态和因果语义
- 平衡设计: 答案选项分布均衡,减少位置偏差
- 挑战性干扰项: 干扰项与问题具有高语义相似性
- 丰富词汇: 各类别包含多样化的语义丰富词汇
评估发现
- MLLMs表现:
- 在视觉基础属性上表现良好
- 在事故原因、类型和可预防性推理方面面临显著挑战
- 评估模型数量: 17个最先进的MLLMs
学术资源
- 论文状态: Coming Soon
- 代码状态: Coming Soon
- arXiv状态: Coming Soon
- BibTeX状态: Coming Soon
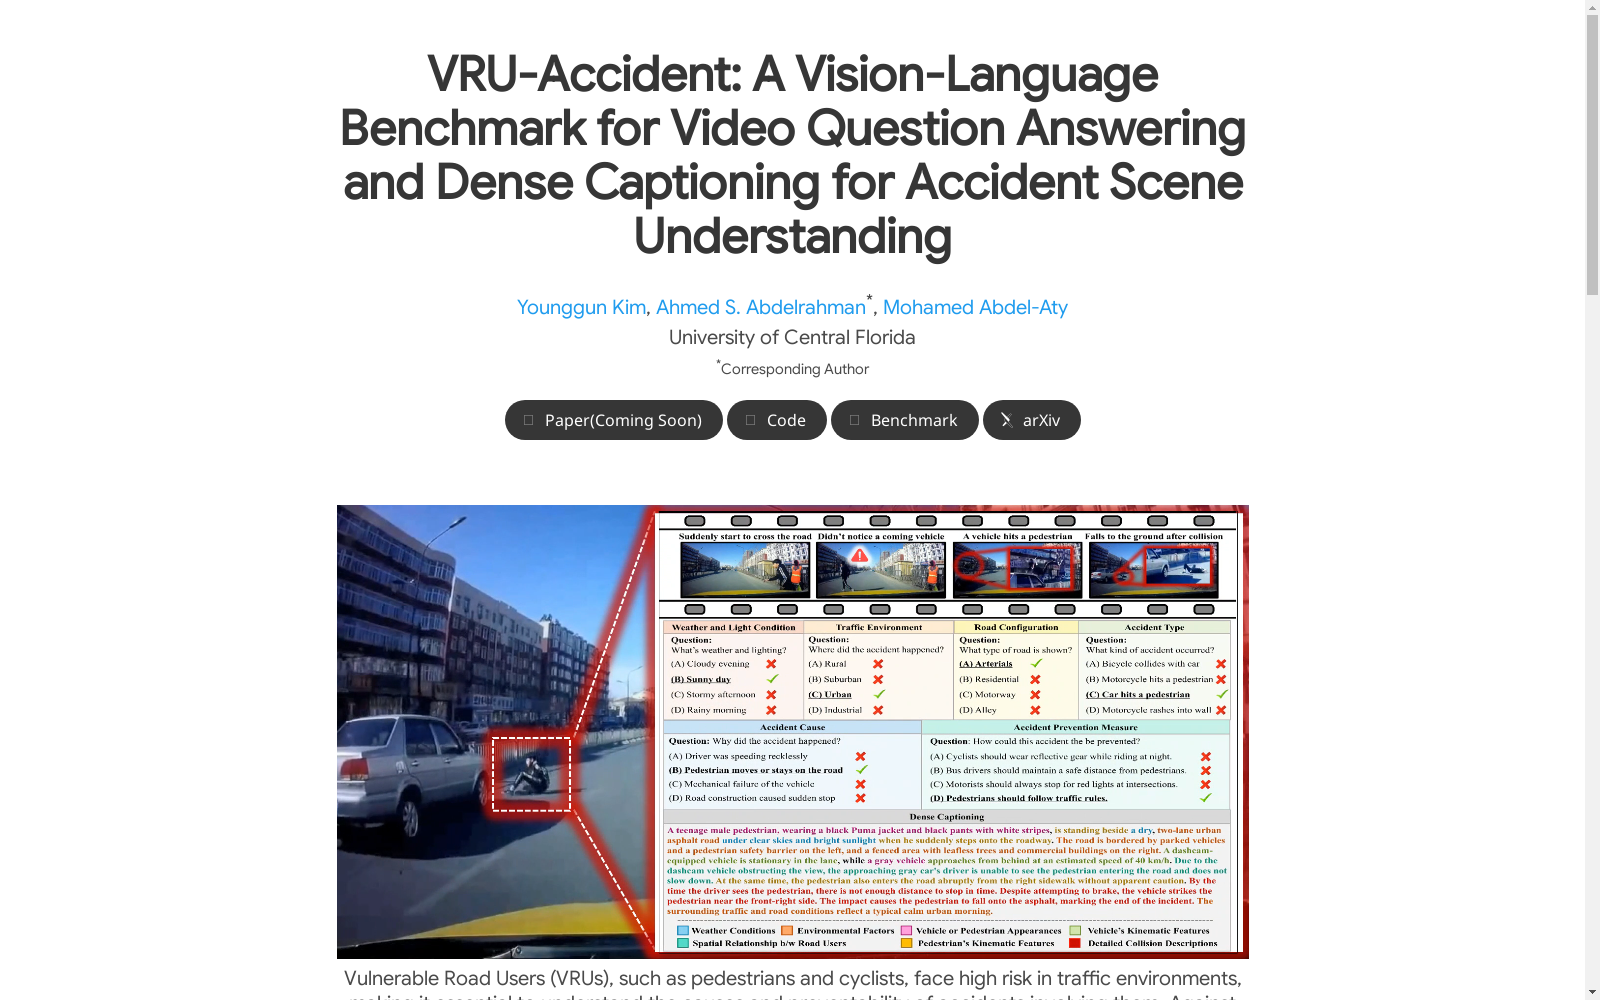
- 1VRU-Accident: A Vision-Language Benchmark for Video Question Answering and Dense Captioning for Accident Scene Understanding美国中佛罗里达大学 · 2025年


