model-specs/blbooksgenre-spec
收藏资源简介:
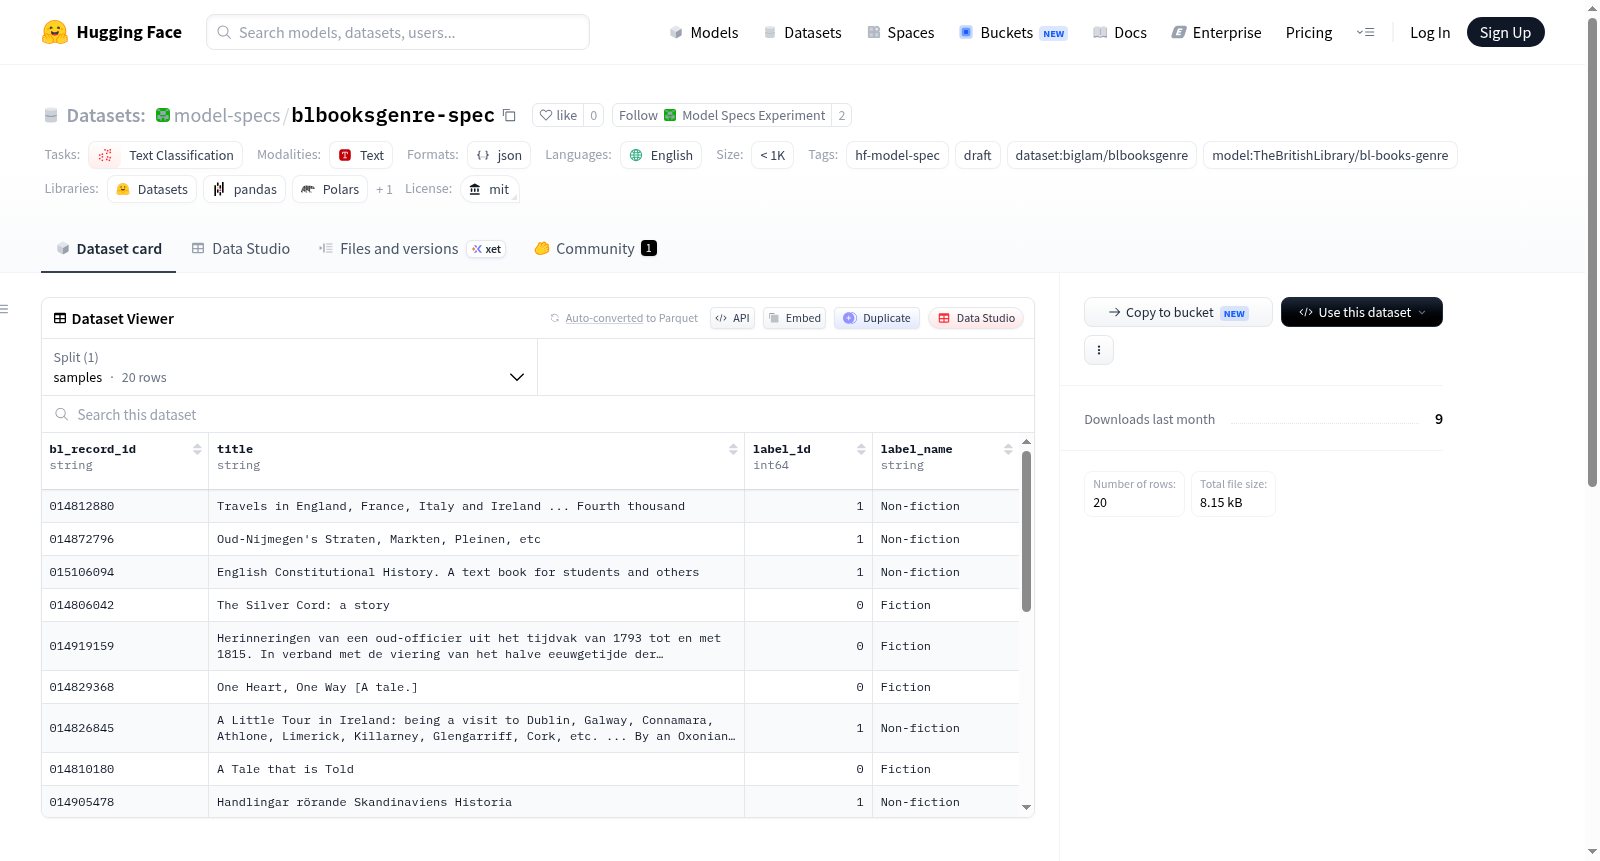
该数据集用于训练一个二元文本分类器,旨在根据19世纪图书的标题判断其属于小说(Fiction)或非小说(Non-fiction)。特别设计用于重新分类大英图书馆目录元数据,尤其是那些现有杜威分类或类型注释缺失或不可靠的标题。数据涵盖维多利亚时代的英文出版物,遵循大英图书馆编目惯例,标题通常包含5-30个单词。数据集主要来自biglam/blbooksgenre中的title_genre_classifiction配置,包含1,736行数据,并提供了20个分层随机样本(10个小说和10个非小说标题)作为示例。
A binary text classifier dataset that takes a 19th-century book title and outputs Fiction or Non-fiction. Designed for re-classifying British Library catalogue metadata — especially titles where the existing Dewey or genre annotation is missing or unreliable. Victorian-era English-language publications, BL cataloguing conventions; titles typically 5–30 words. The dataset is primarily based on the title_genre_classifiction config from biglam/blbooksgenre, containing 1,736 rows, and includes a stratified random sample of 20 titles (10 Fiction + 10 Non-fiction).