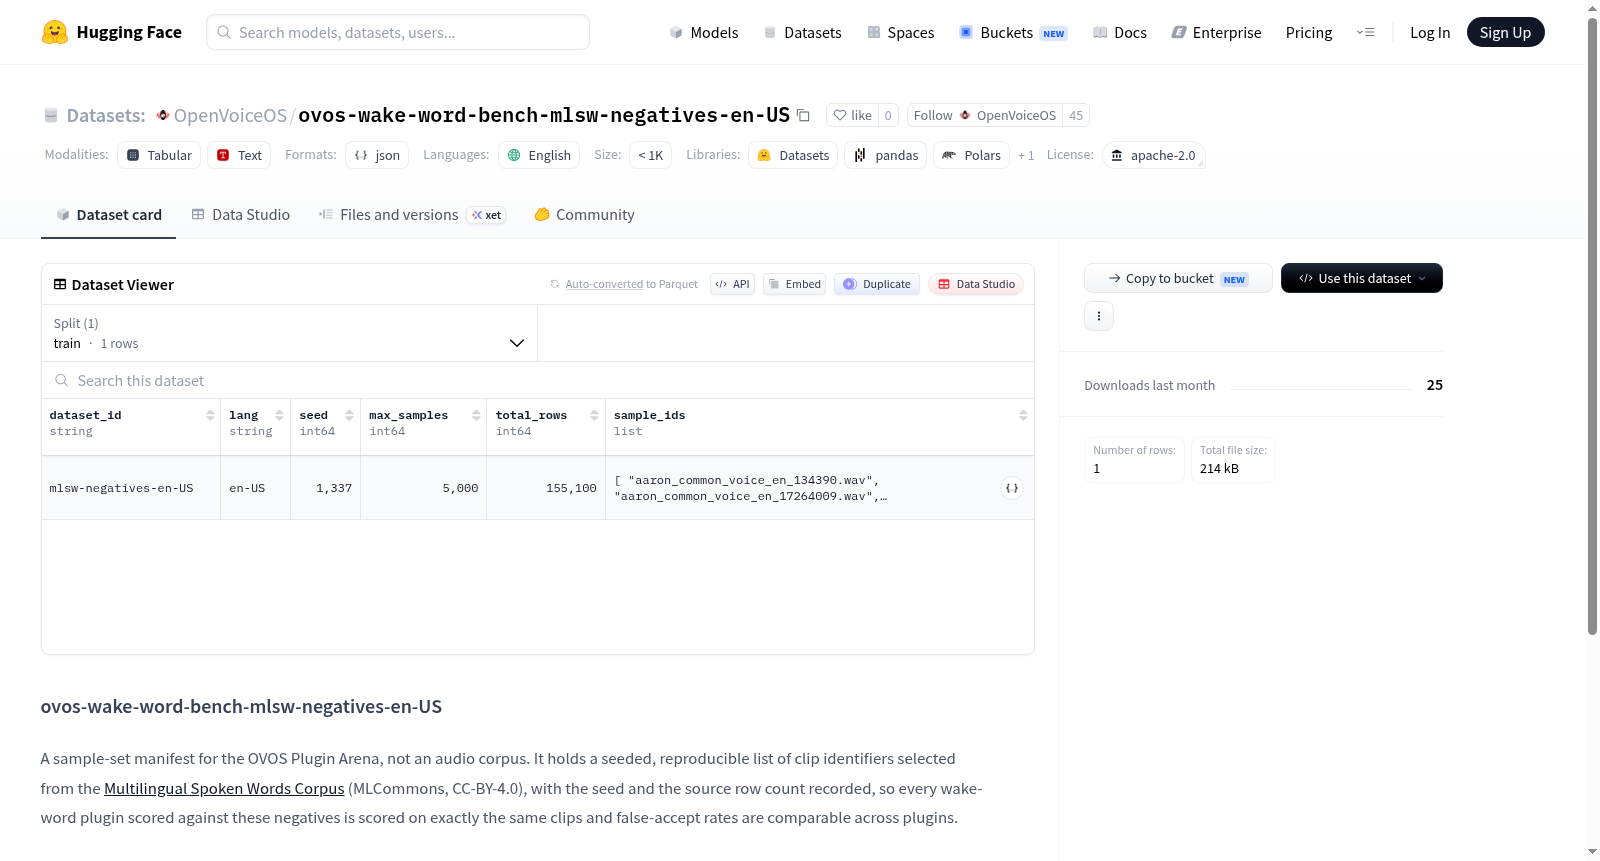
ovos-wake-word-bench-mlsw-negatives-en-US
收藏资源简介:
该数据集是 OVOS 唤醒词基准测试的负样本清单,仅包含剪辑标识符,而非音频文件。它从 Multilingual Spoken Words Corpus(MLCommons, CC-BY-4.0)中通过固定种子选取可复现的剪辑标识符列表,并记录种子和源行数,用于评估唤醒词插件在非唤醒词音频上的误接受率,确保不同插件之间的评分具有可比性。该清单以 Apache-2.0 许可证发布,音频数据需从原始语料库获取。
This dataset is a negative sample list for the OVOS wake word benchmark, containing only clip identifiers, not audio files. It selects a reproducible list of clip identifiers from the Multilingual Spoken Words Corpus (MLCommons, CC-BY-4.0) using a fixed seed, recording the seed and source line count, to evaluate the false acceptance rate of wake word plugins on non-wake-word audio, ensuring comparability of scores across different plugins. The list is released under the Apache-2.0 license, and audio data must be obtained from the original corpus.
数据集概述
数据集名称:ovos-wake-word-bench-mlsw-negatives-en-US
数据集类型:样本集清单(Manifest),非音频语料库
许可证:Apache-2.0
语言:英语(en)
核心功能与用途
该数据集是 OVOS 插件竞技场(Plugin Arena) 的基准测试样本集,并非直接提供音频内容。它主要用于:
- 为唤醒词插件测试提供固定、可复现的负样本集(即非唤醒词的干扰音频)
- 实现不同唤醒词插件在相同音频片段上的公平性能比较,特别是误唤醒率(False-Accept Rate)的对比
数据来源与构建方式
- 底层音频来源:从 Multilingual Spoken Words Corpus(MLCommons,许可证为 CC-BY-4.0)中选取音频片段
- 抽样机制:使用固定随机种子(seeded)进行可复现的抽样,并记录了种子值及源数据行数
- 不重新分发音频:原始音频仍由 MLCommons 独立存储,本数据仅提供片段标识符列表
许可与归属说明
| 项目 | 说明 |
|---|---|
| 本清单数据集 | 采用 Apache-2.0 许可证 |
| 底层音频数据 | 归属 MLCommons,遵循其 CC-BY-4.0 许可证及归属条款 |
相关链接
- 排行榜与结果:OVOS Plugin Arena 结果页面
- 清单格式规范:specification.md
- 源存储库:ovos-plugin-arena