
ComicScene154
收藏资源简介:
ComicScene154是一个由公共领域的漫画书籍组成的场景级叙事弧手动标注数据集,涵盖了多种类型的漫画。该数据集旨在促进多模态叙事理解计算方法的进步,并扩展自然语言处理中漫画分析的范畴。数据集包含4个公共领域的漫画杂志,共34个独特的故事,分布在154页的不同类型和出版年份中。数据集的创建过程包括从漫画页面中提取面板,并对其编号,以保持一致性。此外,数据集还进行了可重复性和可靠性评估。该数据集的应用领域包括叙事理解、故事摘要、实体跟踪等。
ComicScene154 is a manually annotated dataset of scene-level narrative arcs constructed from public-domain comic books, covering various comic genres. This dataset aims to advance computational methods for multimodal narrative understanding and expand the scope of comic analysis in natural language processing. The dataset consists of 4 public-domain comic magazines, totaling 34 unique stories spanning 154 pages across different genres and publication years. The dataset creation process involves extracting panels from comic pages and numbering them to ensure consistency. In addition, the dataset has undergone reproducibility and reliability evaluations. Application scenarios of this dataset include narrative understanding, story summarization, entity tracking, and more.
ComicScene154 数据集概述
数据集简介
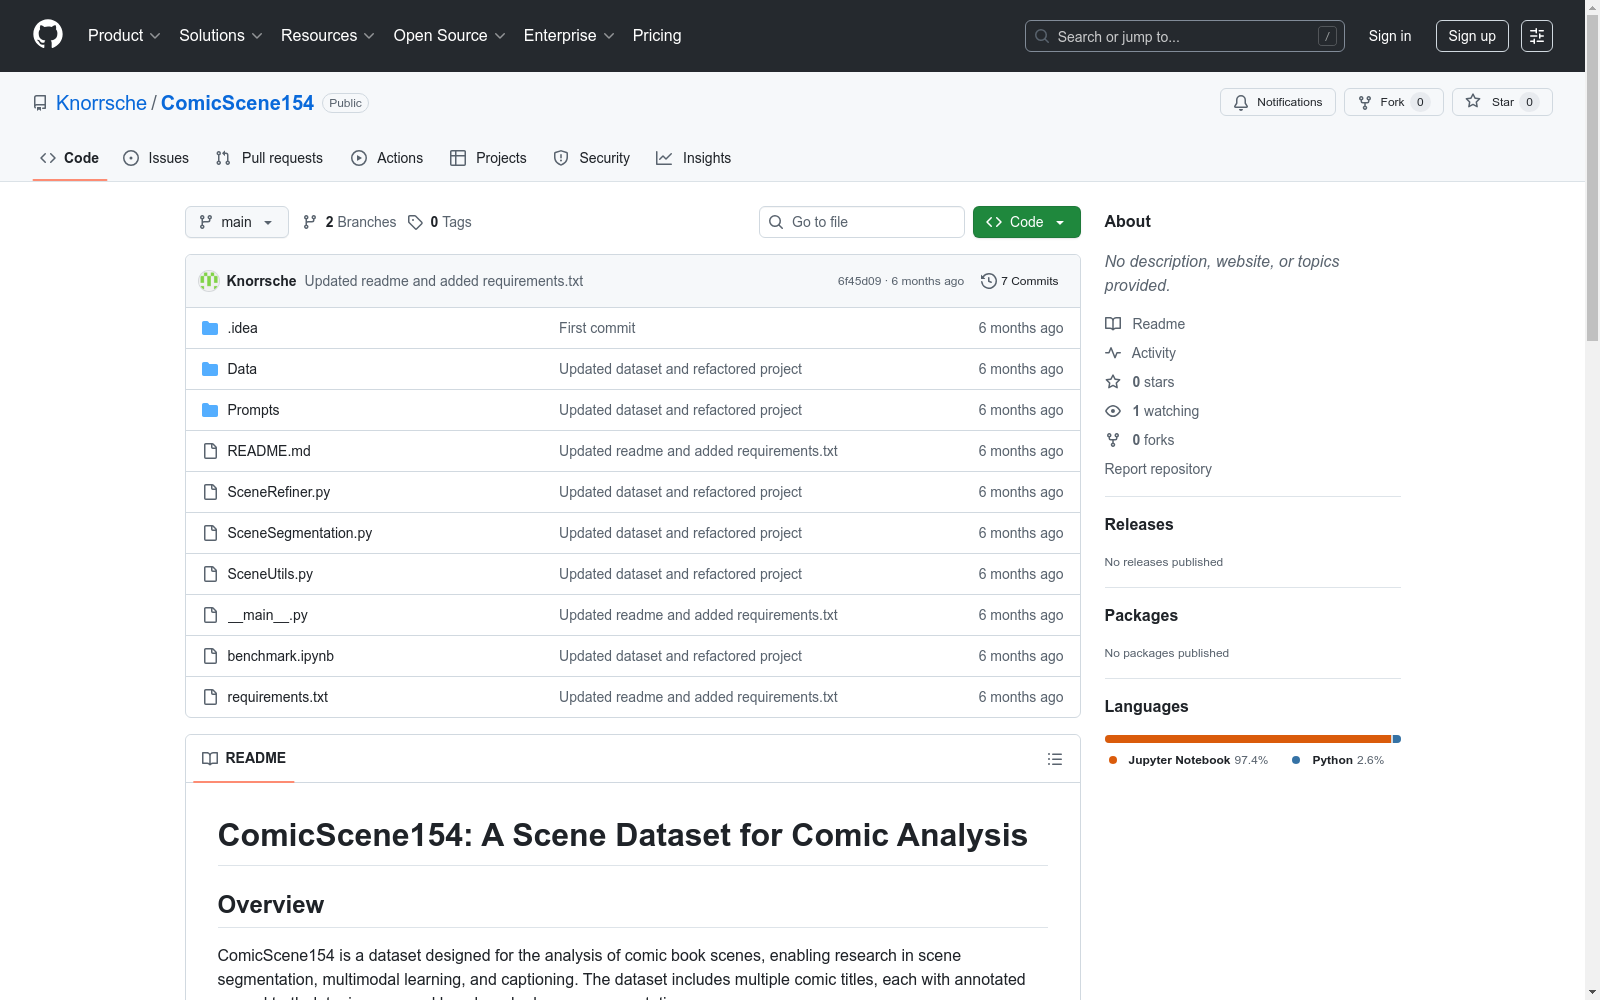
ComicScene154 是一个专为漫画书场景分析设计的数据集,支持场景分割、多模态学习和字幕生成等研究方向。该数据集包含多部漫画标题,每部漫画均带有标注的真实数据、图像以及基准场景分割结果。
项目结构
- 文档目录(docs/)
- 数据子目录(Data/)
- Alley_Oop(漫画1)
- Alley_Oop.json:包含场景和面板标注的真实数据
- images:漫画图像
- benchmarked_scenes:多模态场景的基准数据
- benchmarked_refined_scenes:论文中使用的精炼基准数据
- Champ(漫画2)
- Champ.json:包含场景和面板标注的真实数据
- images:漫画图像
- benchmarked_scenes:多模态场景的基准数据
- benchmarked_refined_scenes:论文中使用的精炼基准数据
- Treasure_Comics(漫画3)
- Treasure_Comics.json:包含场景和面板标注的真实数据
- images:漫画图像
- benchmarked_scenes:多模态场景的基准数据
- benchmarked_refined_scenes:论文中使用的精炼基准数据
- Western_Love(漫画4)
- Western_Love.json:包含场景和面板标注的真实数据
- images:漫画图像
- benchmarked_scenes:多模态场景的基准数据
- benchmarked_refined_scenes:论文中使用的精炼基准数据
- Alley_Oop(漫画1)
- 提示词目录(Prompts/)
- ScenePrompt.txt:场景分割提示词
- SceneRefinerPrompt.txt:精炼场景分割提示词
- 代码文件
- main.py:场景分割主函数
- SceneSegmentation.py:场景分割功能函数
- SceneRefiner.py:精炼场景分割功能函数
- SceneUtils.py:工具函数
- requirements.txt:环境依赖文件
- benchmark.ipynb:场景分割基准评估笔记本
- 数据子目录(Data/)
数据集内容
每部漫画标题包含以下内容:
- 真实数据:以JSON格式存储,包含场景和面板的标注信息。
- 图像:漫画页面的图像文件。
- 基准场景:用于多模态场景分析的基准数据。
- 精炼基准:在初始分割基础上改进的基准数据。
使用方式
环境安装
安装所需依赖: bash pip install -r requirements.txt
运行场景分割
执行场景分割: bash python main.py
基准评估
使用Jupyter Notebook进行基准评估: bash jupyter notebook benchmark.ipynb
其他信息
- 贡献:欢迎通过提交拉取请求来改进或添加功能。
- 许可证:未提供许可证信息。
- 联系:如有问题或疑问,请在GitHub上提交问题或联系维护者。
- 1ComicScene154: A Scene Dataset for Comic AnalysisCAIRO,THWS,Technical University of Applied Sciences Würzburg-Schweinfurt · 2025年


