mteb/STSBenchmarkv2
收藏资源简介:
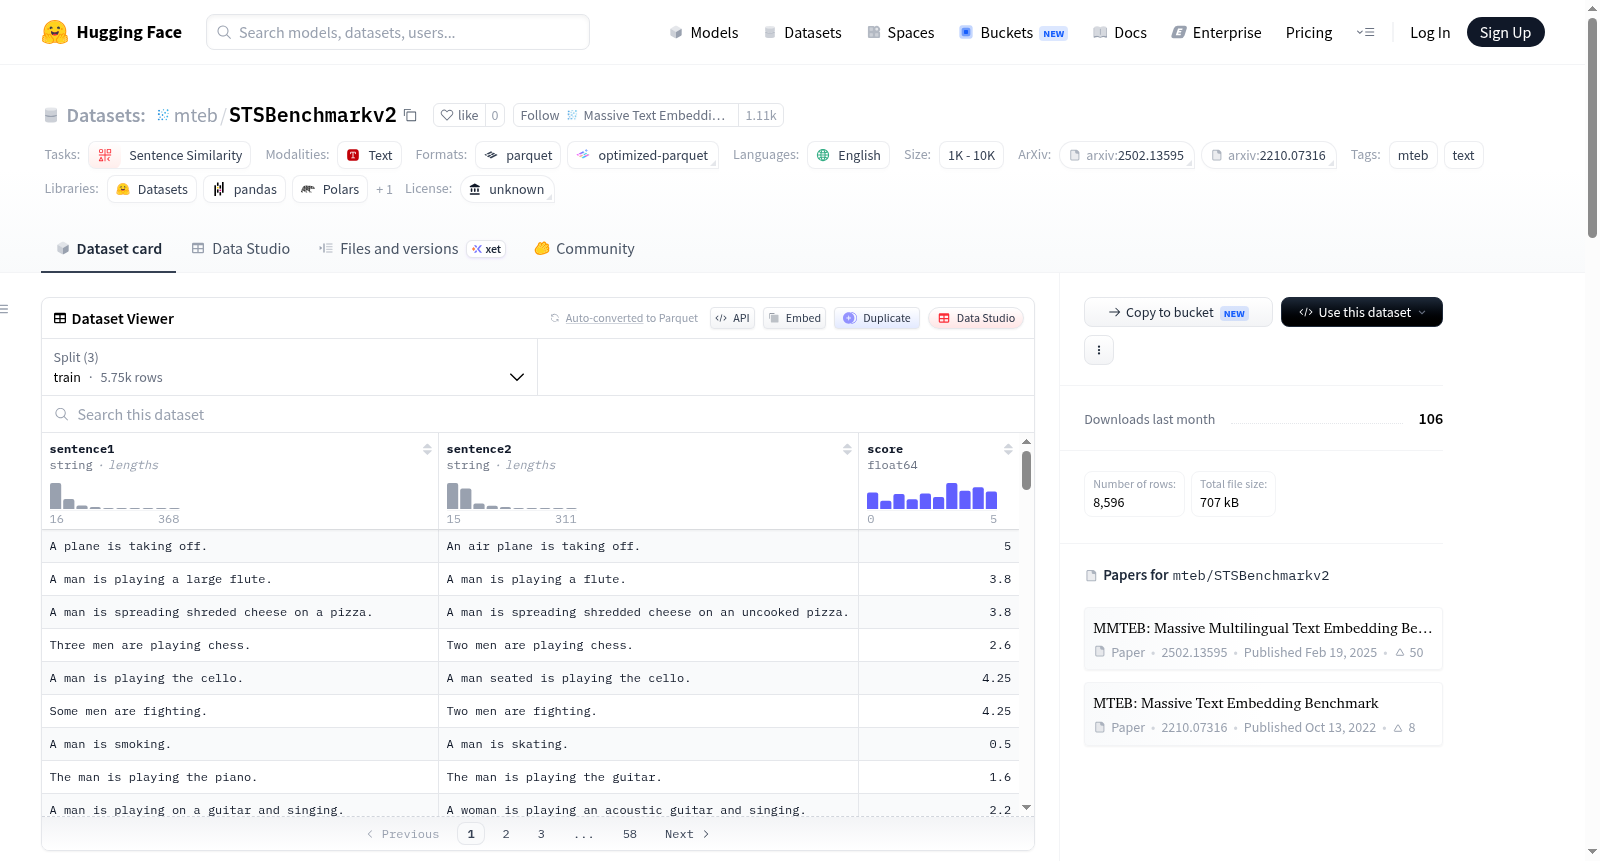
STSBenchmark.v2是一个语义文本相似性基准数据集,属于大规模文本嵌入基准(MTEB)的一部分。该数据集用于评估模型对句子之间语义相似性的理解能力,任务类别为句子相似性。数据集包含来自博客、新闻和书面文本领域的句子对,每个句子对都有一个0到5分的相似性评分。此版本移除了验证集和测试集中的重复句子对,确保同一顺序无关的句子对在评估分割中不重复出现。数据集分为训练集(5749个样本)、验证集(1485个样本)和测试集(1362个样本),每个样本包括两个句子(sentence1和sentence2)和一个浮点数分数(score)。数据来源于mteb/stsbenchmark-sts,并经过额外处理以符合MTEB标准。
STSBenchmark.v2 is a semantic textual similarity benchmark dataset, part of the Massive Text Embedding Benchmark (MTEB). This dataset is designed for evaluating model performance on sentence similarity tasks, where the goal is to measure semantic similarity between sentence pairs. It covers domains including blog posts, news articles, and written texts. Each sentence pair is annotated with a similarity score ranging from 0 to 5. This version removes duplicate sentence pairs from the validation and test splits to ensure that the same order-insensitive pair does not appear more than once in an evaluation split or across splits. The dataset is split into train (5,749 examples), validation (1,485 examples), and test (1,362 examples) sets, with each example containing two sentences (sentence1 and sentence2) and a float score. It is sourced from mteb/stsbenchmark-sts and includes additional processing as part of the MTEB framework.