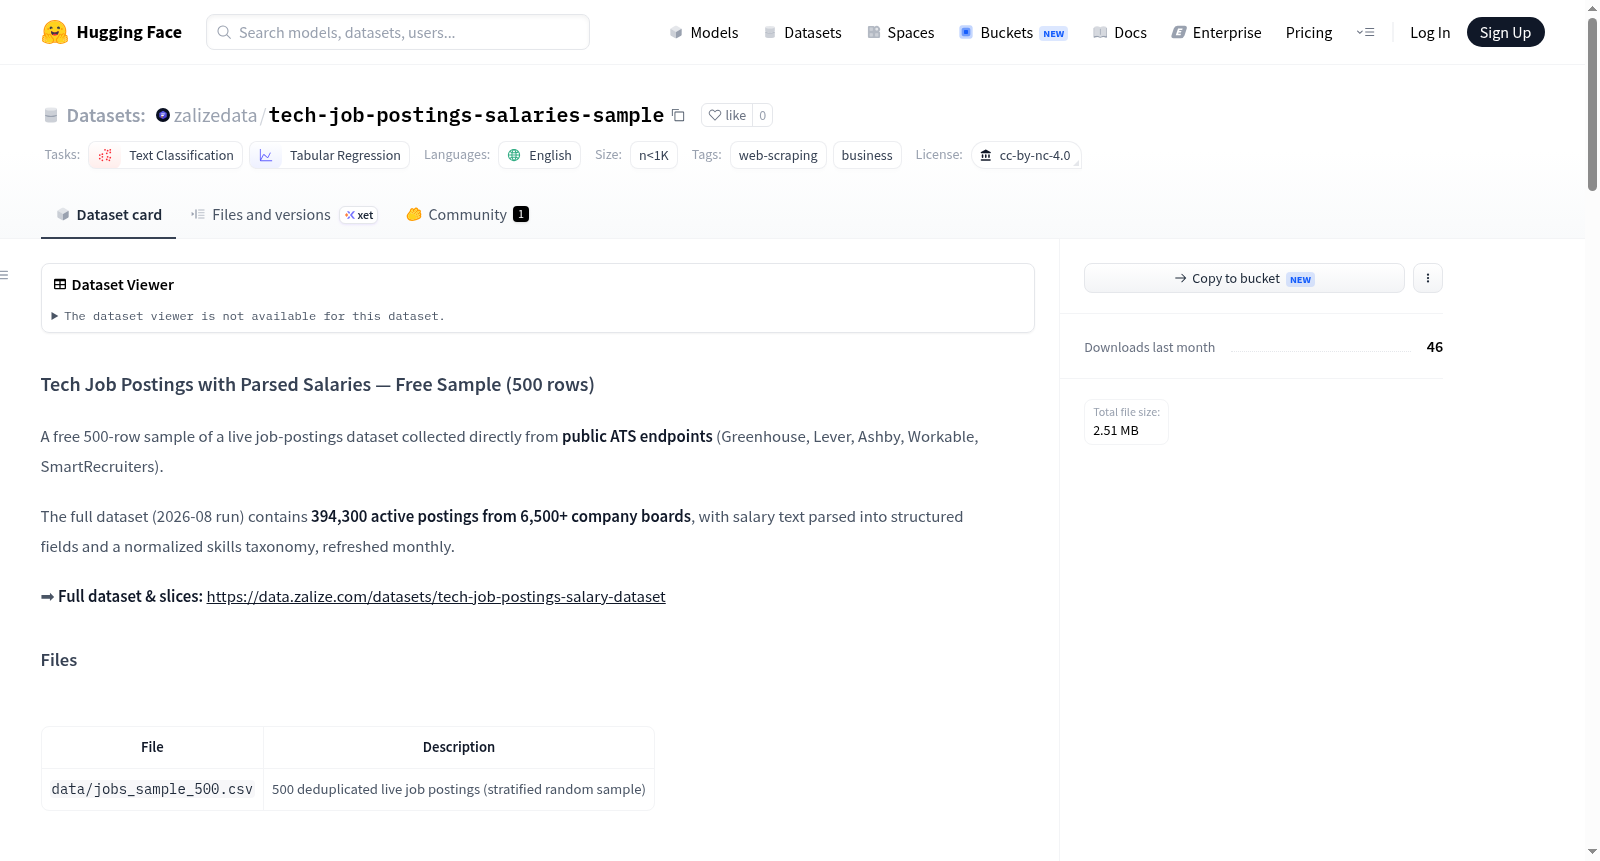
tech-job-postings-salaries-sample
收藏资源简介:
该数据集是技术职位招聘信息的一个免费样本(500行),来源于公共ATS端点(Greenhouse、Lever、Ashby、Workable、SmartRecruiters)收集的实时职位数据。样本为分层随机抽样的去重活跃职位,包含23个字段,涵盖公司名称、公司域名、行业、ATS来源、职位ID、职位标题、部门、原始地点、国家、城市、远程标识、雇佣类型、薪资下限、薪资上限、薪资货币、薪资周期、薪资是否来自文本、技能标签(标准化分类,约110个标签)、发布日期、收集时间戳、原始职位URL、完整职位描述文本。该数据集适用于薪资基准与薪酬透明度研究、招聘速度与劳动力市场信号分析、技能需求分析、以及薪资预测或职位分类模型的训练与评估。数据收集仅访问公开、无需登录的ATS端点,自适应速率限制,无反爬规避,不包含任何个人数据。每行均提供原始URL和收集时间戳以供溯源。薪资覆盖在美国薪资透明州及英国/欧盟地区最为充分,公司偏向于使用上述五种ATS的科技公司。样本采用CC BY-NC 4.0许可,完整数据集(每月更新,约394,300条活跃职位)提供分层商业许可。
This dataset is a free sample (500 rows) of technical job posting information, collected from public ATS endpoints (Greenhouse, Lever, Ashby, Workable, SmartRecruiters) with real-time job data. The sample is a stratified random sample of deduplicated active jobs, containing 23 fields: company name, company domain, industry, ATS source, job ID, job title, department, original location, country, city, remote flag, employment type, salary floor, salary ceiling, salary currency, salary period, salary from text, skill tags (standardized classification, ~110 tags), posting date, collection timestamp, original job URL, and full job description text. The dataset is suitable for salary benchmarking and pay transparency research, hiring speed and labor market signal analysis, skill demand analysis, and training/evaluation of salary prediction or job classification models. Data collection only accesses public, no-login-required ATS endpoints, with adaptive rate limiting, no anti-scraping evasion, and contains no personal data. Each row provides an original URL and collection timestamp for traceability. Salary coverage is most comprehensive in US pay transparency states and UK/EU regions, with companies biased toward tech firms using the five mentioned ATS. The sample is licensed under CC BY-NC 4.0, and the full dataset (monthly updated, ~394,300 active jobs) offers tiered commercial licenses.
数据集概述
- 名称: Tech Job Postings with Parsed Salaries — Free Sample (500 rows)
- 许可证: CC BY-NC 4.0(非商业评估用途)
- 语言: 英语
- 规模: 少于 1,000 行(具体为 500 行)
- 任务类型: 文本分类、表格回归
数据来源与内容
- 采集来源: 直接提取自公开的 ATS 端点(Greenhouse、Lever、Ashby、Workable、SmartRecruiters)
- 样本说明: 500 行去重后的真实职位发布数据,采用分层随机抽样
- 完整数据集: 约 394,300 条活跃职位(2026-08 运行),来自 6,500+ 公司招聘页面,按月更新,完整版可通过 data.zalize.com 获取
数据结构
- 文件格式: CSV(
data/jobs_sample_500.csv) - 字段数量: 23 列,涵盖以下类别:
- 公司信息: 公司名称、域名、行业
- 职位信息: 职位名称、部门、地点(原始/国家/城市)、远程标志、雇佣类型
- 薪资数据: 最低/最高薪资、货币(ISO 4217)、薪资周期(年/月/周/日/小时)、薪资来源(结构化字段或文本解析)
- 技能标签: 标准化技能分类(约 110 个标签,如 python、kubernetes),CSV 中以
|分隔 - 时间与来源: 发布日期、抓取时间(ISO 8601 UTC)、原始职位 URL
- 描述文本: 清洗后的完整职位描述(去除 HTML)
适用场景
- 薪资基准分析与薪酬透明度研究
- 招聘速度与劳动力市场信号分析
- 技能需求分析
- 训练薪资预测或职位分类模型
合规性与来源声明
- 仅采集公开、无需登录的 ATS 端点,采用自适应速率限制,无规避反爬机制
- 仅包含公司与职位层面信息,不涉及个人数据(如招聘人员姓名/邮箱)
- 每行数据均包含
url与scraped_at以保证可溯源性,并设有 DMCA 下架渠道
已知限制
- 薪资覆盖在美国薪酬透明州及英国/欧盟地区最强
- 公司集偏向使用上述五种 ATS 平台的科技公司
使用方式
- 加载数据:
load_dataset("zalizedata/tech-job-postings-salaries-sample", split="train") - 引用要求: 需注明数据来源为“DataForge (data.zalize.com)”,并附上链接 https://data.zalize.com,同时按数据表要求引用上游数据提供方
相关数据集