global-lei-company-registry-dataset
收藏资源简介:
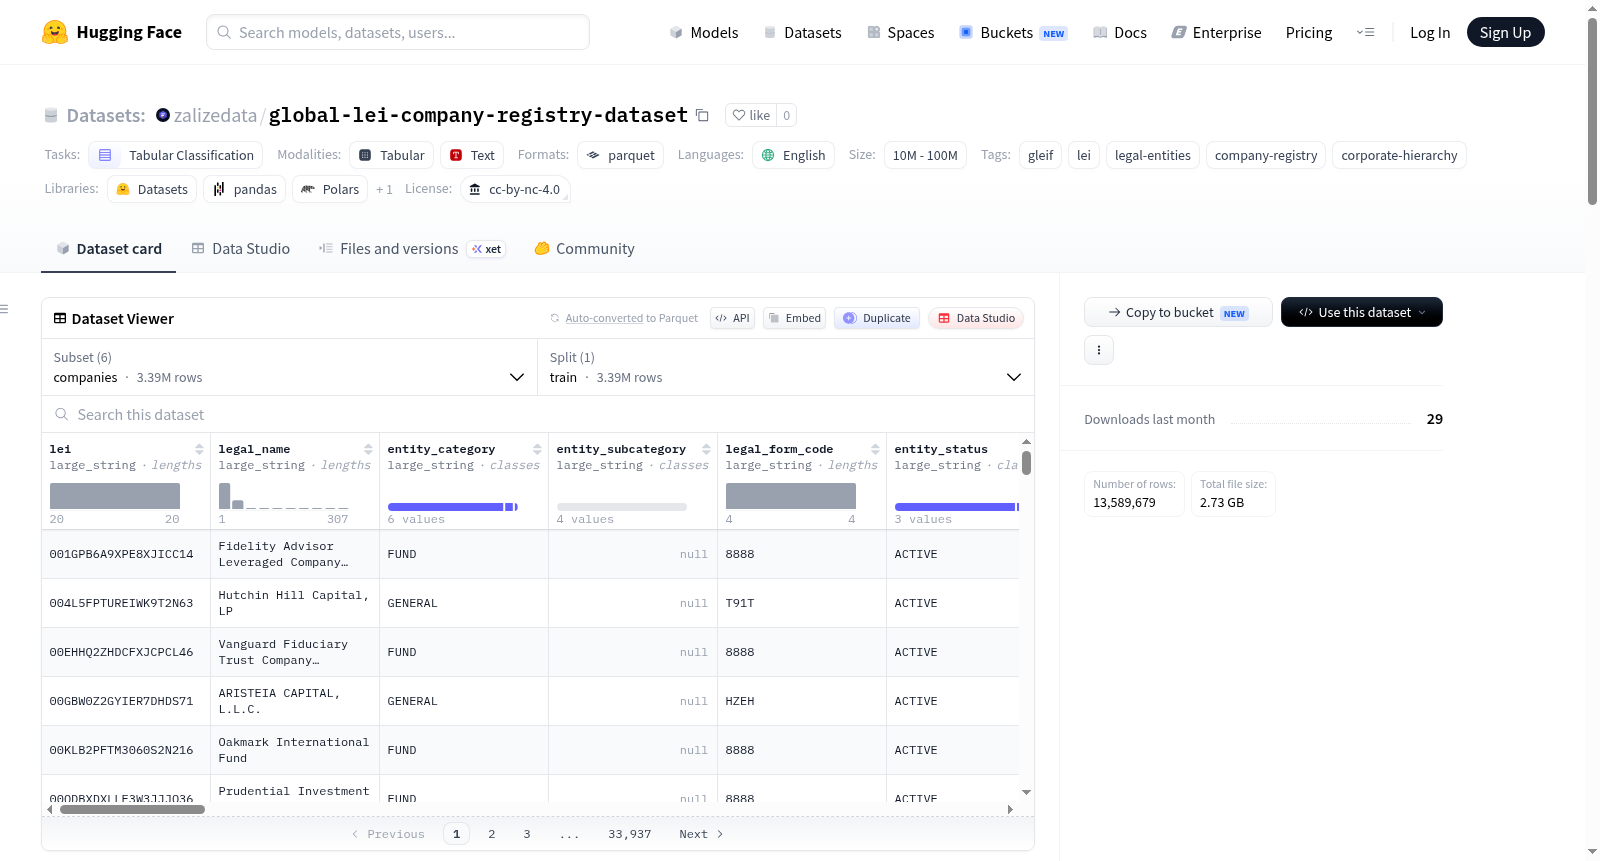
Global LEI Company Registry (GLEIF) 数据集是基于 GLEIF 黄金副本构建的分析就绪表,收录了约340万个法律实体的注册地址、企业层级关系及报告异常信息。该数据集由 DataForge 开放数据计划提供,适用于学术和个人免费使用。数据以多个分片包的形式发布,包括S(起始切片,72万实体)、M(研究包,678万行,含二级关系)和L(完整黄金副本,1359万行,含实体、关系及报告异常)。数据集包含六个配置:companies(公司)、country_summary(国家摘要)、crosswalk(交叉引用)、groups(集团)、ownership_edges(所有权边)和reporting_exceptions(报告异常)。数据格式为Parquet,每包附带数据字典、数据表和质量报告。典型用途包括实体解析、KYC参考数据、企业层级映射、将LEI与申报文件、交易和注册信息关联,以及市场结构研究。底层数据遵循CC0 1.0许可,DataForge策展层采用CC BY-NC 4.0许可(学术/个人使用需署名并链接回data.zalize.com),商业使用需获得DataForge商业许可。
The Global LEI Company Registry (GLEIF) dataset is an analysis-ready table built from the GLEIF Golden Copy, containing approximately 3.4 million legal entities registered addresses, corporate hierarchy relationships, and reporting exception information. It is provided by the DataForge Open Data Program and is free for academic and personal use. The data is published in multiple shard packages: S (starting slice, 720,000 entities), M (research package, 6.78 million rows with second-level relationships), and L (full Golden Copy, 13.59 million rows with entities, relationships, and reporting exceptions). The dataset includes six configurations: companies, country_summary, crosswalk, groups, ownership_edges, and reporting_exceptions. Data format is Parquet, each package comes with a data dictionary, data table, and quality report. Typical uses include entity resolution, KYC reference data, corporate hierarchy mapping, linking LEI to filings, transactions, and registration information, as well as market structure research. The underlying data follows CC0 1.0 license, and the DataForge curation layer uses CC BY-NC 4.0 license (academic/personal use requires attribution and link back to data.zalize.com), commercial use requires a DataForge commercial license.
数据集概述
Global LEI Company Registry (GLEIF) 是一个完整的全球法律实体标识符(LEI)金标准副本数据集,以分析就绪的表格形式呈现,包含340万个法律实体及其注册地址、公司层级关系和报告例外情况。
基本信息
- 许可协议:CC BY-NC 4.0(非商业用途);商业用途需另行获取DataForge商业许可
- 语言:英文(en)
- 任务类别:表格分类(tabular-classification)
- 数据规模:10M < n < 100M 行
- 数据来源:GLEIF金标准副本(上游数据为CC0 1.0许可)
数据集内容
数据集包含以下6个配置(configs):
| 配置名称 | 说明 |
|---|---|
companies |
公司实体数据 |
country_summary |
国家汇总数据 |
crosswalk |
交叉引用数据 |
ownership_edges |
股权关系边数据 |
groups |
集团数据 |
reporting_exceptions |
报告例外数据 |
数据包分类
数据集提供三个层级的数据包:
| 数据包 | 层级 | 行数 | 大小 |
|---|---|---|---|
gleif-tier1-S-2026-08-04.zip |
S(入门版) | 719,985 | 86.9 MB |
gleif-tier1-M-2026-08-04.zip |
M(研究版) | 6,788,250 | 853.5 MB |
gleif-tier2-L-2026-08-04.zip |
L(完整版) | 13,589,679 | 1.00 GB |
- S(入门版):包含72万实体
- M(研究版):包含680万行,涵盖二级关系
- L(完整版):包含实体、关系和报告例外的完整金标准副本
- 每个数据包均附带数据字典、数据表和QA报告
应用场景
- 实体解析和KYC参考数据
- 公司层级映射
- 将LEI与申报文件、交易和注册信息进行关联
- 市场结构研究
使用方法
python from datasets import load_dataset
ds = load_dataset("zalizedata/global-lei-company-registry-dataset", "companies", split="train") print(ds[0])
引用信息
text DataForge (data.zalize.com), built from GLEIF CC0 golden-copy data — https://data.zalize.com/datasets/global-lei-company-registry-dataset
DOI(Zenodo镜像):10.5281/zenodo.21837354