stefanocarrera/autophagycode_D_he_train-mercury_Qwen3-4B_strategy_trust_t1.25_g4_run0
收藏资源简介:
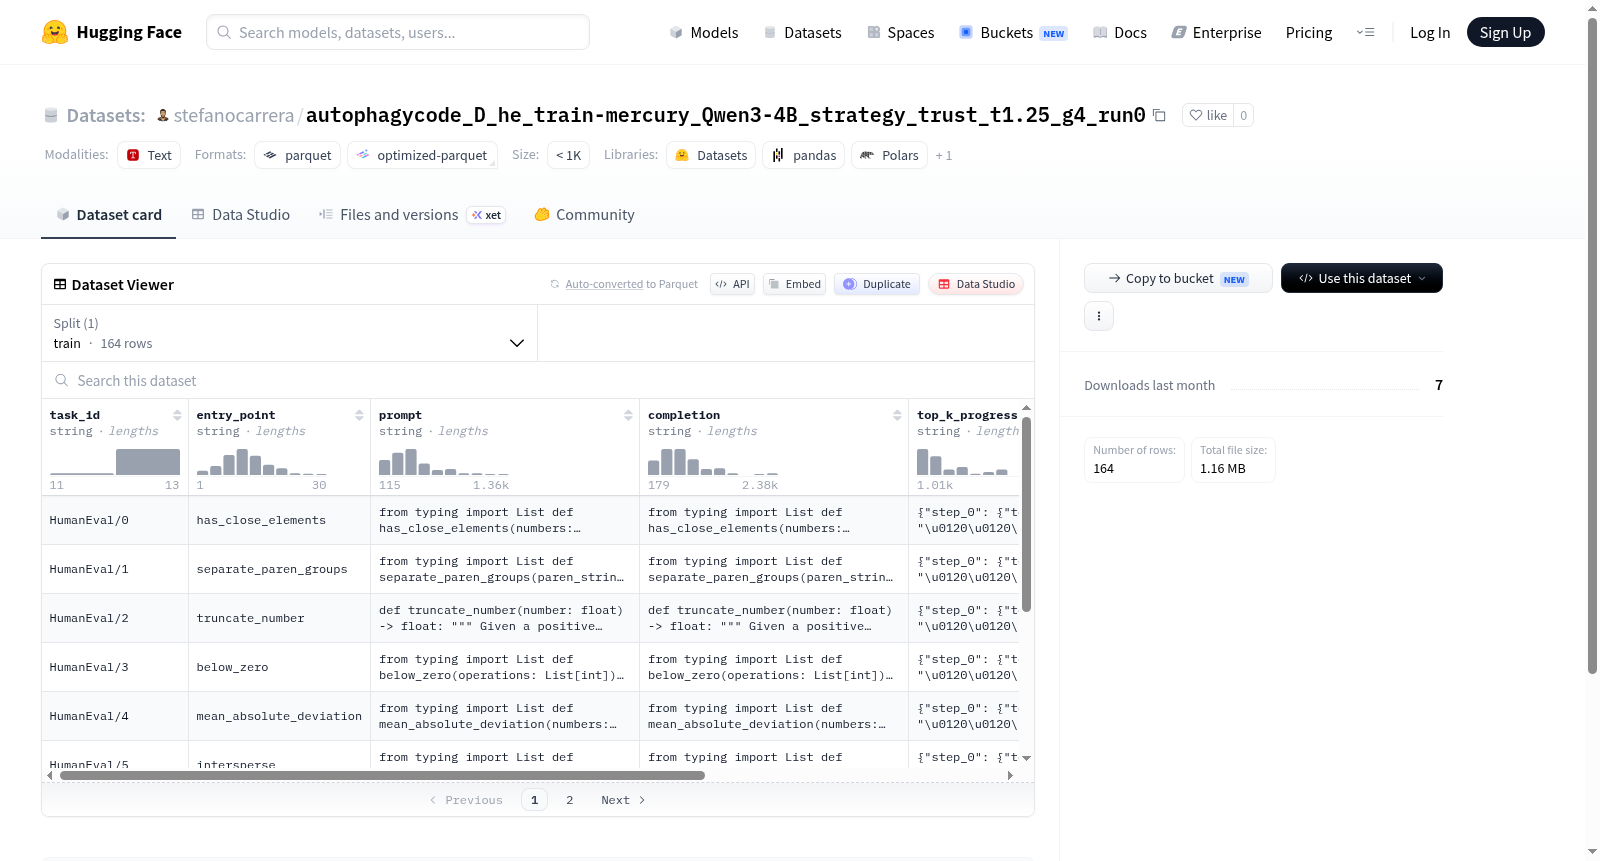
该数据集是一个用于自然语言处理或代码生成任务的数据集,包含164个训练样本。每个样本具有多个特征:task_id(任务标识符)、entry_point(可能表示入口点或函数名)、prompt(输入提示文本)、completion(完成文本或代码)、top_k_progression(可能表示生成过程中的top-k选择)和test(可能关联测试信息)。数据集结构紧凑,总大小约为4.23MB,适用于模型训练或评估,但具体用途和背景未在README中明确说明。
This dataset is designed for natural language processing or code generation tasks, containing 164 training examples. Each example includes multiple features: task_id (task identifier), entry_point (possibly indicating an entry point or function name), prompt (input prompt text), completion (completion text or code), top_k_progression (likely representing top-k selections in generation processes), and test (possibly related to testing information). The dataset is compact with a total size of approximately 4.23MB, suitable for model training or evaluation, but its specific purpose and background are not explicitly detailed in the README.