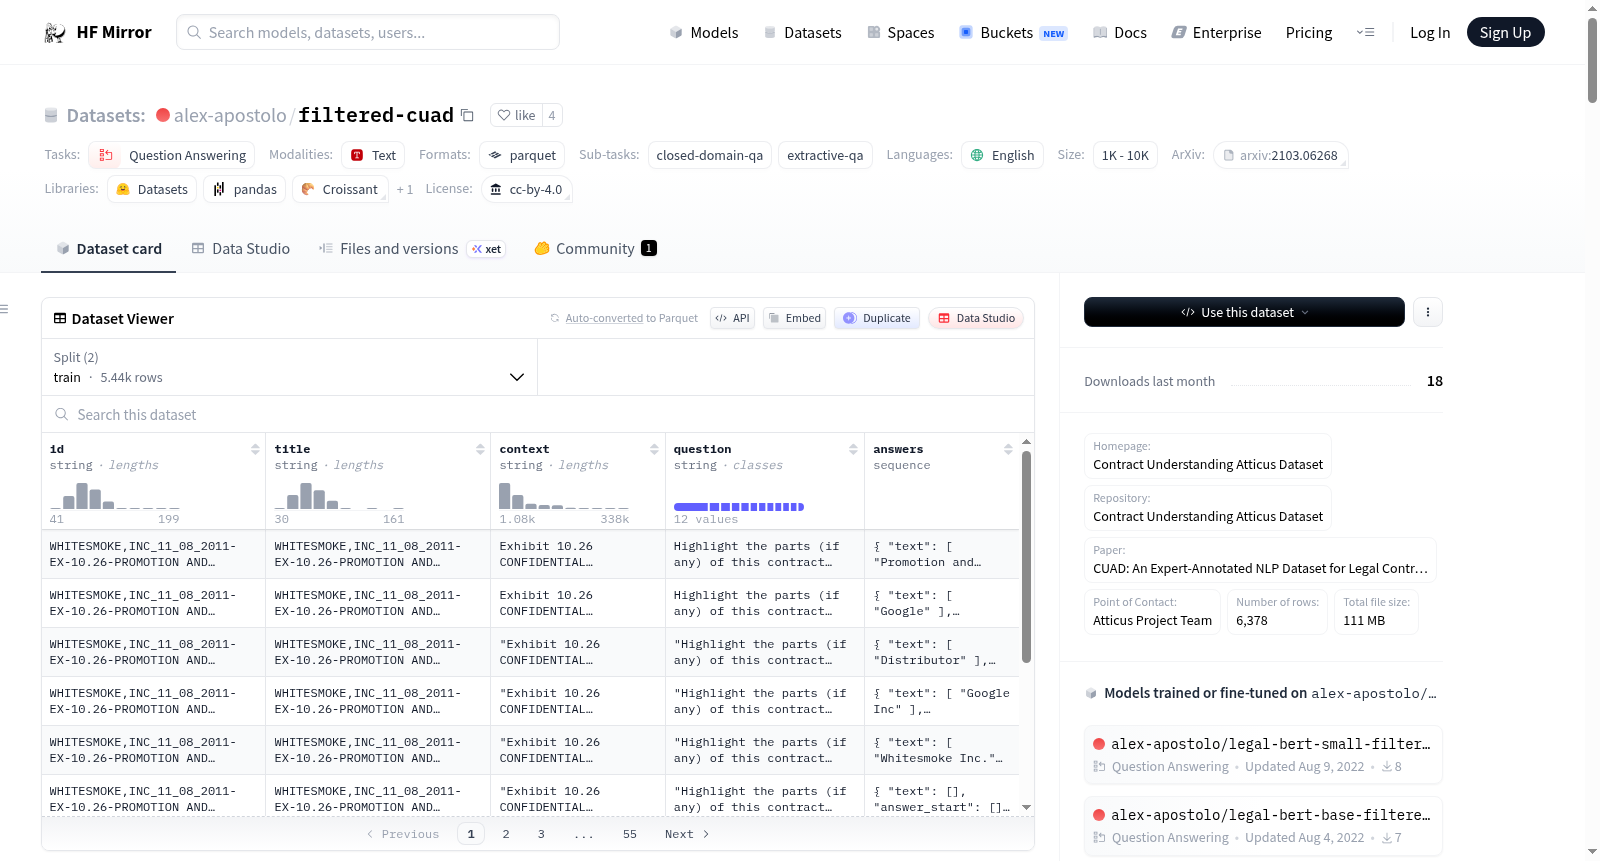
alex-apostolo/filtered-cuad
收藏资源简介:
CUAD(Contract Understanding Atticus Dataset)是一个用于法律合同审查的自然语言处理数据集。该数据集包含了510份商业法律合同中的13,000多个标签,涵盖了41个重要条款类别。该数据集是CUAD的过滤版本,排除了2002年之前的合同和非B2B合同,并将41个类别过滤为12个最重要的类别。数据集的主要任务是问答任务,特别是封闭域问答和抽取式问答。数据集的语言为英语,且是单语言的。数据集的创建目的是为了支持法律合同审查的NLP研究和开发,减少合同审查的社会成本,并研究NLP模型在专业领域的泛化能力。
CUAD (Contract Understanding Atticus Dataset) is a natural language processing dataset designed for legal contract review. This dataset includes over 13,000 labels spanning 510 commercial legal contracts, covering 41 critical clause categories. This is a filtered variant of the original CUAD, which excludes contracts created prior to 2002 and non-B2B contracts, and reduces the 41 original categories to the 12 most important ones. The core task supported by this dataset is question answering, specifically closed-domain question answering and extractive question answering. The dataset is entirely in English and is a monolingual corpus. It was developed to support NLP research and development for legal contract review, mitigate the social costs associated with contract review, and investigate the generalization capability of NLP models in professional domains.
数据集概述
名称: CUAD (Contract Understanding Atticus Dataset)
描述: CUAD是一个专注于法律合同审查的NLP数据集,包含超过13,000个标签,分布在510个商业法律合同中。这些合同被手动标记以识别律师在审查合同时寻找的41个重要条款类别。此数据集是CUAD的过滤版本,排除了2002年之前的合同和非B2B合同,并从41个类别中筛选出12个最关键的类别。
语言: 英语
许可证: CC-BY-4.0
数据集大小: 10K<n<100K
任务类型: 问答(Closed-Domain QA, Extractive QA)
训练/评估索引:
- 配置: 默认
- 任务: 问答
- 任务ID: Extractive_Question_Answering
- 分割:
- 训练分割: train
- 评估分割: test
- 列映射:
- 问题: question
- 上下文: context
- 答案:
- 文本: text
- 答案开始位置: answer_start
- 度量标准:
- 类型: CUAD
- 名称: CUAD
数据集结构
数据实例
每个数据实例包括以下字段:
- id: 字符串类型
- title: 字符串类型
- context: 字符串类型
- question: 字符串类型
- answers: 字典类型,包含:
- text: 字符串类型
- answer_start: 整数类型
数据分割
- 训练集: 5442样本
- 测试集: 936样本
数据集创建
来源数据
- 类型: 商业合同
- 数量: 总共385份合同,涵盖25种不同类型
注释
- 注释者: 法律学生和律师
- 注释过程: 包括法律学生培训、手动合同审查和标记、关键词搜索、类别报告审查、律师审查和最终报告生成。
个人和敏感信息
- 部分合同条款因保护隐私而被编辑,显示为星号或下划线。