JackHsieh/32B-predict.rule-r-1.0-k-256.L-16.statml-arxiv
收藏资源简介:
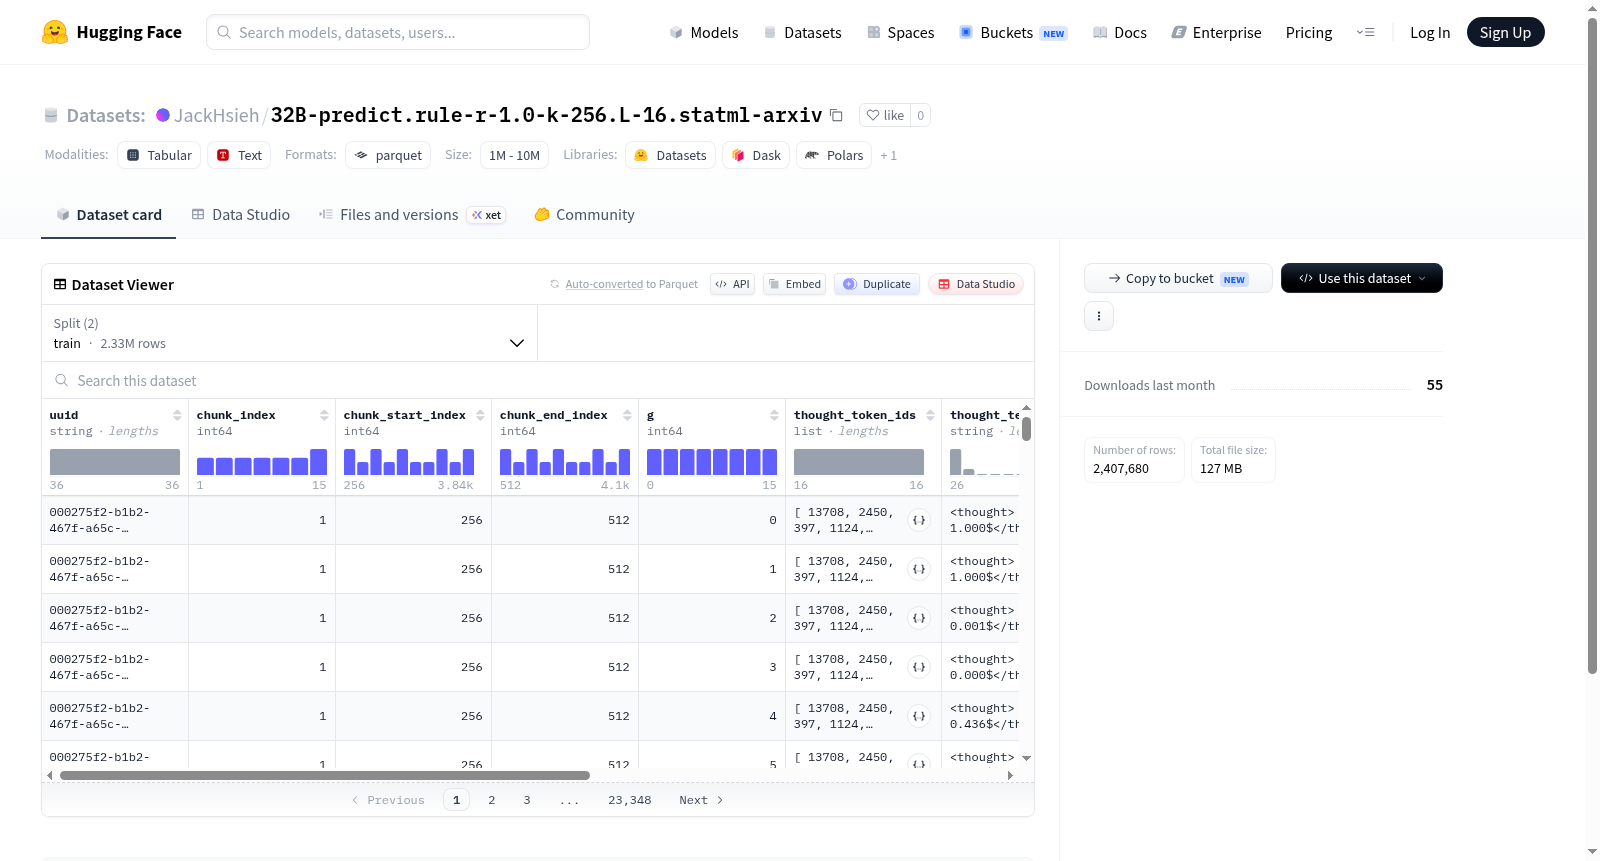
该数据集是一个用于文本生成或推理任务的数据集,包含思维链相关的信息,如思维令牌ID和思维文本。数据集结构包括唯一标识符、块索引、生成参数(如g值)、截断状态、完成原因、生成时间和生成时长等元数据。数据分为训练集和测试集,训练集有2,334,720个示例,测试集有72,960个示例,总大小约为758 MB。数据集可能用于模型训练和评估,支持自然语言处理中的生成任务。
This dataset is designed for text generation or reasoning tasks, incorporating chain-of-thought related information such as thought token IDs and thought text. It includes features like unique identifiers, chunk indices, generation parameters (e.g., g value), truncation status, finish reason, generation timestamp, and generation duration. The data is split into train and test sets, with 2,334,720 examples in the train set and 72,960 examples in the test set, totaling approximately 758 MB in size. It is likely used for model training and evaluation in natural language processing generation tasks.