
COMPOSE 数据集
收藏资源简介:
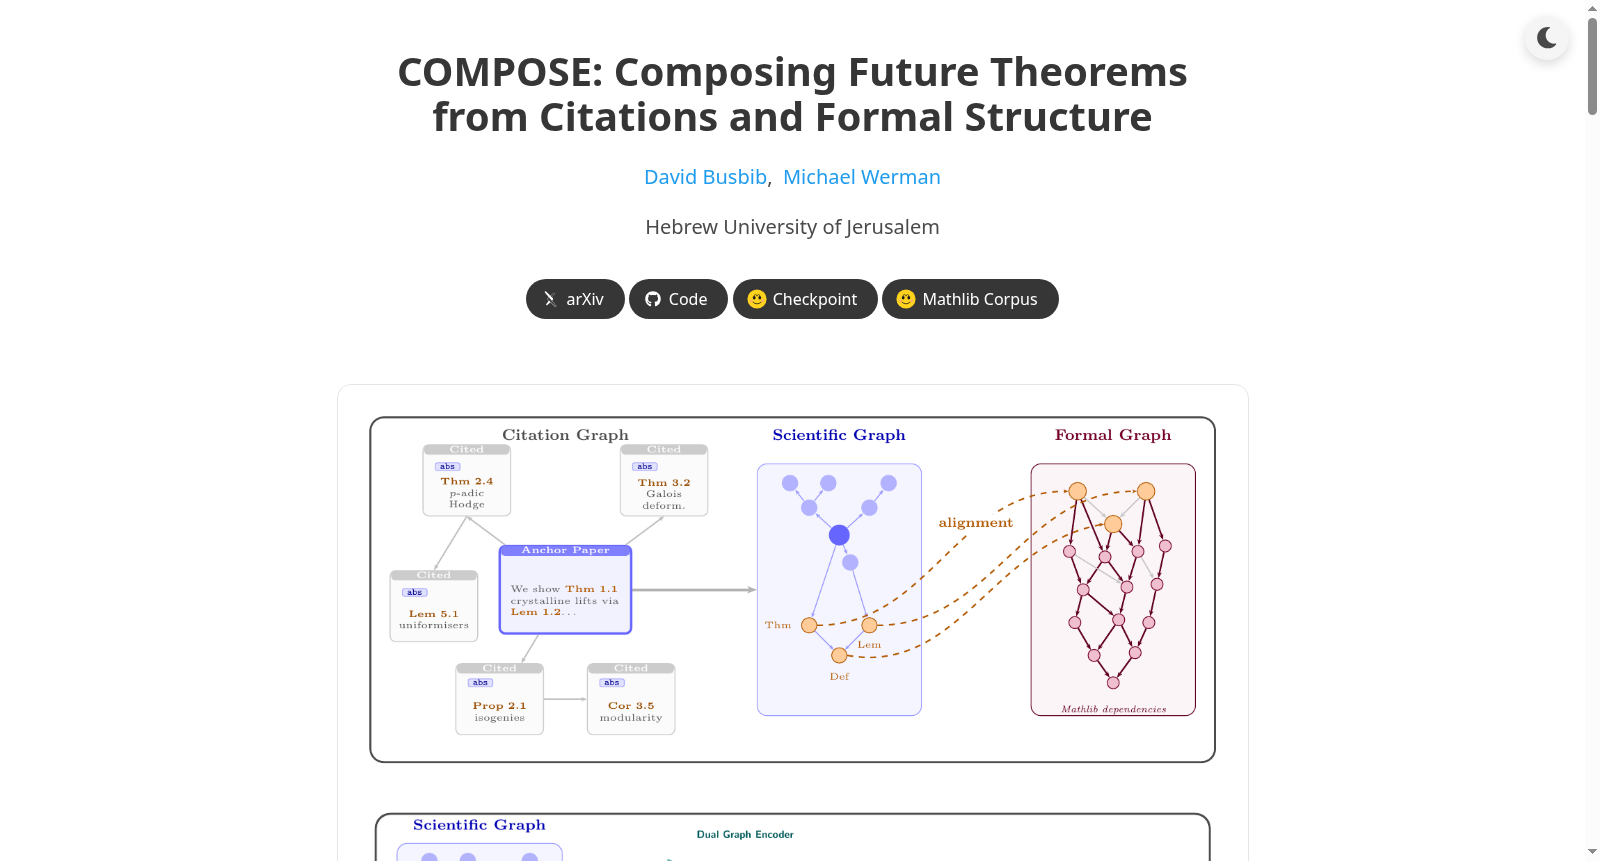
COMPOSE数据集是由耶路撒冷希伯来大学研究团队构建的大规模数学研究资源,旨在支持基于科学引文和形式定理依赖的接地未来数学生成任务。该数据集包含108,000个配对样本,每个样本由科学图(基于arXiv论文的引文网络和定理提取)和形式图(基于Mathlib定理依赖结构)组成,数据来源涵盖2000年至2023年的50万篇数学论文,并通过FrenzyMath进行非形式化对齐处理。数据创建过程涉及从S2ORC收集数学论文、构建引文图、提取定理节点,并与Mathlib形式定理库进行对齐,形成双图结构。该数据集主要应用于人工智能驱动的数学研究预测领域,旨在解决如何结合科学语境和形式逻辑约束来生成合理未来数学命题的核心问题,为机器学习模型提供多源知识融合的训练基础。
The COMPOSE dataset is a large-scale mathematical research resource constructed by a research team from the Hebrew University of Jerusalem, aiming to support grounded future mathematical generation tasks based on scientific citations and formal theorem dependencies. It contains 108,000 paired samples, each consisting of a scientific graph (based on the citation network and theorem extraction from arXiv papers) and a formal graph (based on the Mathlib theorem dependency structure). The data sources cover 500,000 mathematical papers published between 2000 and 2023, and the dataset undergoes informal alignment processing via FrenzyMath. The data creation process involves collecting mathematical papers from S2ORC, constructing citation graphs, extracting theorem nodes, and aligning with the Mathlib formal theorem library to form a dual-graph structure. This dataset is mainly applied in the field of AI-driven mathematical research prediction, aiming to solve the core problem of how to combine scientific context and formal logical constraints to generate plausible future mathematical propositions, and provide a training foundation for machine learning models to fuse multi-source knowledge.
- 1COMPOSE: Composing Future Theorems from Citations and Formal Structure耶路撒冷希伯来大学 · 2026年


