DCAgent2/medagentbench_Qwen3_Coder_480B_A35B_Instruct_FP8_20260430_052915
收藏资源简介:
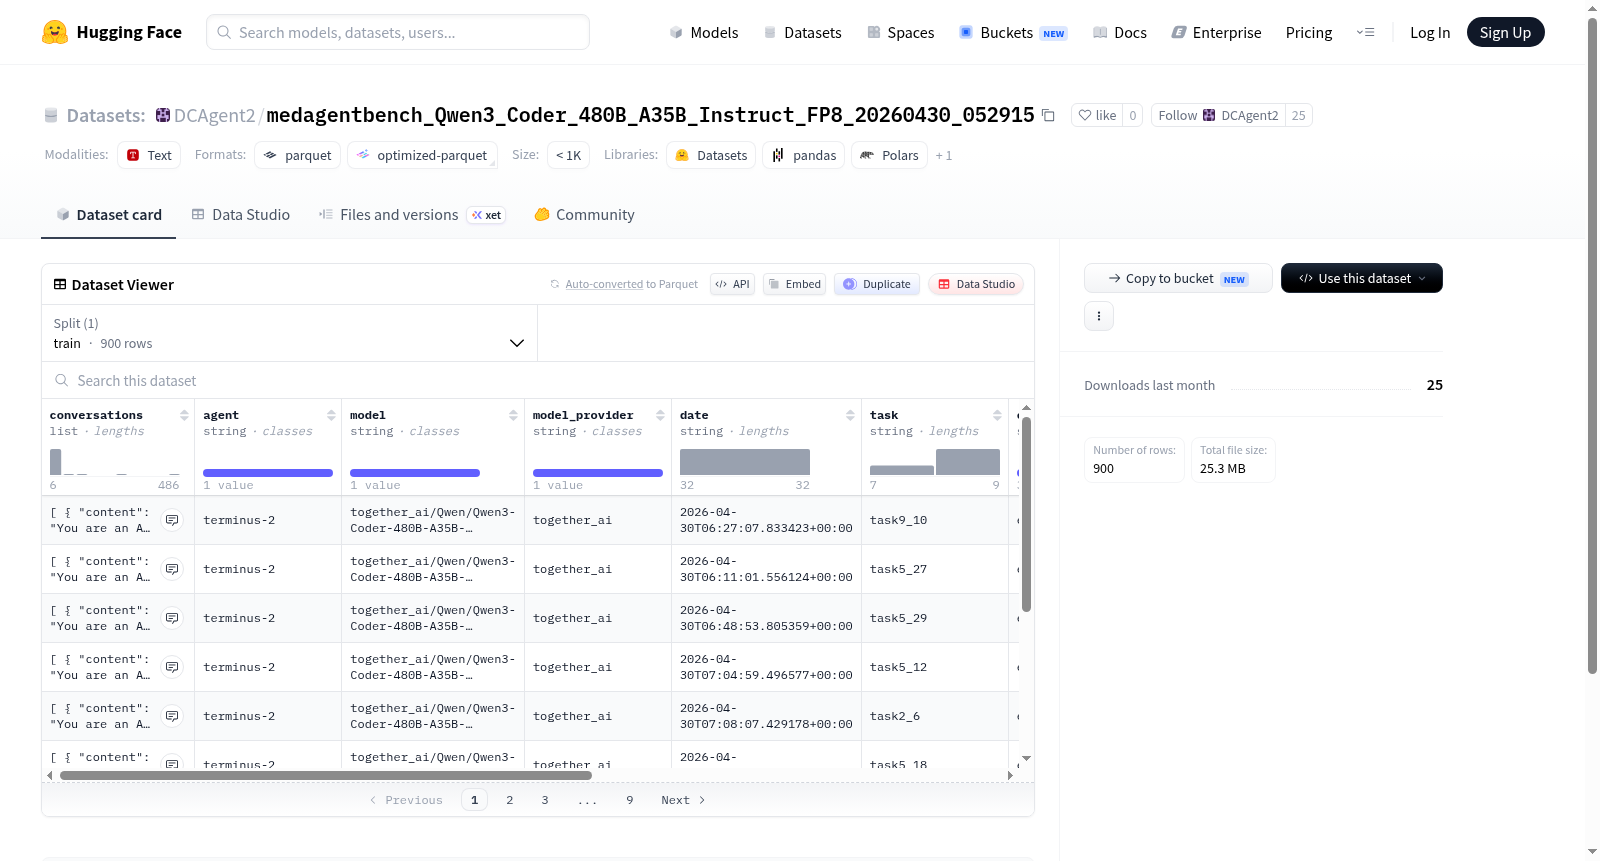
该数据集是一个包含900个样本的训练数据集,主要用于多轮对话和任务执行场景的分析。每个样本包含多个特征字段:conversations(对话内容,包括角色和内容)、agent(代理标识)、model(使用的模型)、model_provider(模型提供商)、date(日期)、task(任务类型)、episode(事件编号)、run_id(运行ID)、trial_name(试验名称)、result(执行结果)和verifier_output(验证器输出)。数据集可能涉及人工智能代理的交互对话、任务完成情况评估以及相关元数据记录,适用于自然语言处理、对话系统评估或任务导向型AI研究。数据集大小约为25.5MB,仅提供训练分割。
This dataset is a training set containing 900 samples, primarily designed for analysis of multi-turn conversations and task execution scenarios. Each sample includes multiple feature fields: conversations (dialogue content with role and content), agent (agent identifier), model (model used), model_provider (model provider), date (date), task (task type), episode (episode number), run_id (run ID), trial_name (trial name), result (execution result), and verifier_output (verifier output). The dataset likely involves interactive dialogues of AI agents, evaluation of task completion, and related metadata records, suitable for natural language processing, dialogue system assessment, or task-oriented AI research. The dataset size is approximately 25.5MB and only includes a training split.