
OCRTurk
收藏资源简介:
OCRTurk是由中东技术大学和Roketsan公司联合创建的首个土耳其语OCR基准数据集,旨在解决土耳其语文档解析缺乏标准化评估的问题。该数据集包含180份真实文档,涵盖学术论文、非学术文档、学位论文和幻灯片四种类型,并按照难度分为简单、中等和困难三个级别。数据来源于arXiv、DergiPark、YÖK TEZ等多个公开平台,包含文本、表格、数学公式和图形等多种元素。数据集通过手动标注和严格的质量控制流程构建,采用Markdown格式标准化存储。该数据集主要用于评估OCR模型在土耳其语文档解析中的性能,特别是在多元素识别和低资源语言处理方面的能力。
OCRTurk is the first Turkish-language OCR benchmark dataset jointly created by Middle East Technical University and Roketsan, aiming to address the lack of standardized evaluation for Turkish document parsing. This dataset comprises 180 real-world documents covering four categories: academic papers, non-academic documents, theses, and slide decks, and is divided into three difficulty levels: easy, medium, and hard. The data is sourced from multiple public platforms including arXiv, DergiPark, YÖK TEZ and others, and contains diverse elements such as text, tables, mathematical formulas and graphics. The dataset is constructed through manual annotation and a rigorous quality control workflow, and is stored in a standardized Markdown format. This dataset is primarily used to evaluate the performance of OCR models in Turkish document parsing, especially their capabilities in multi-element recognition and low-resource language processing.
OCRTurk Benchmark 数据集概述
数据集基本信息
- 数据集名称: OCRTurk Benchmark
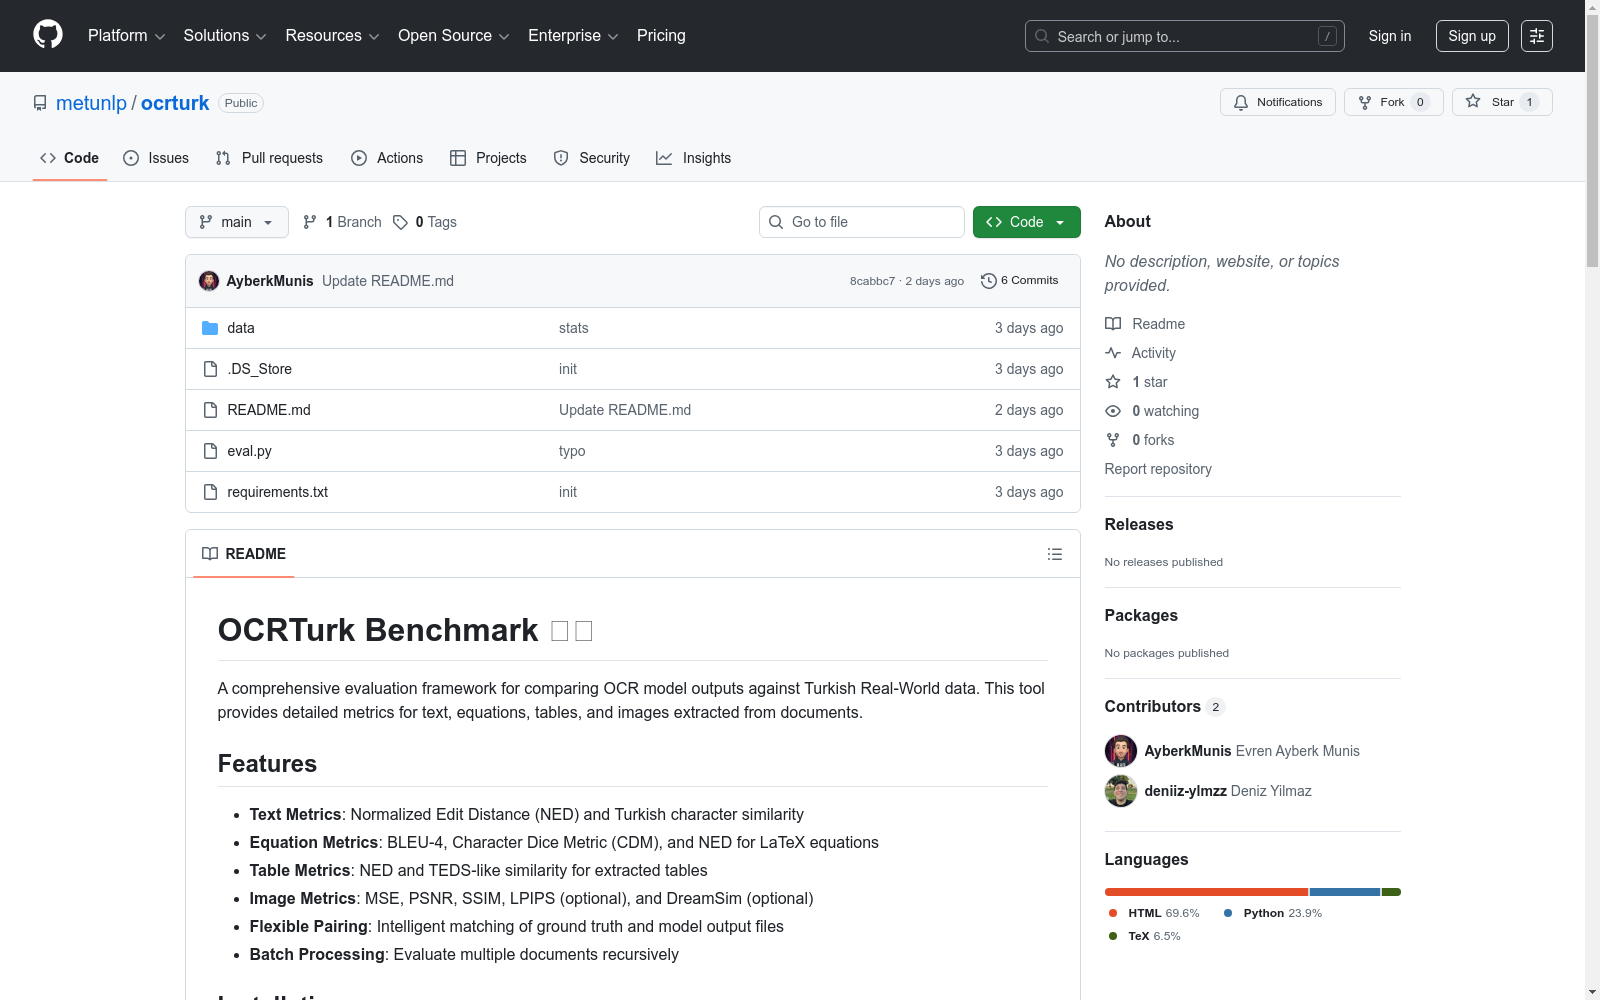
- 主要用途: 一个用于比较OCR模型输出与土耳其语真实世界数据的综合评估框架。
- 核心功能: 提供从文档中提取的文本、公式、表格和图像的详细评估指标。
评估指标
文本指标
- 归一化编辑距离: Levenshtein距离按长度归一化(值越低越好,0表示完美匹配)。
- 土耳其语字符相似度: 针对土耳其语变音符号的专门指标(值越高越好,1表示完美)。
公式指标
- BLEU-4: 用于LaTeX公式的标准BLEU分数(值越高越好,1表示完美)。
- 字符Dice指标: 基于字符重叠的类F1指标(值越高越好,1表示完美)。
- 公式归一化编辑距离: 针对LaTeX字符串的编辑距离(值越低越好)。
表格指标
- 表格归一化编辑距离: 对CSV序列化表格的编辑距离(值越低越好)。
- 类TEDS指标: 基于树编辑距离的表格结构相似度(值越高越好,1表示完美)。
图像指标
- 均方误差: 均方误差(值越低越好)。
- DreamSim: 感知相似度指标(值越低越好)。
数据结构与使用
预期输入结构
ground_truth/ ├── data_1/ │ ├── document.md │ └── figures/ │ ├── figure_1.png │ └── figure_2.png model_outputs/ ├── data_1/ │ ├── result.md (或 document.md) │ └── images/ (或 fig/, imgs/) │ ├── figure_1.png │ └── figure_2.png
输出结构
results/ ├── per_doc_metrics.csv # 每个文档的指标 ├── per_image_metrics.csv # 每个图像对的指标 └── summary_metrics.csv # 汇总统计信息
输出文件详情
- per_doc_metrics.csv: 包含每个文档的指标,如文本、公式、表格、图像指标以及提取元素的数量。
- per_image_metrics.csv: 包含每个图像对的指标,如均方误差、DreamSim以及源文件路径。
- summary_metrics.csv: 包含所有文档和图像的汇总统计数据。
快速开始
基本使用
bash python eval.py <ground_truth_path> <model_output_path> [results_path]
包含图像指标
bash python eval.py <ground_truth_path> <model_output_path> [results_path] --images
示例
bash python eval.py ./data/ground_truth ./data/model_outputs ./results --images
引用信息
如需在研究中引用此工具,请使用以下BibTeX条目: bibtex @misc{yılmaz2026ocrturkcomprehensiveocrbenchmark, title={OCRTurk: A Comprehensive OCR Benchmark for Turkish}, author={Deniz Yılmaz and Evren Ayberk Munis and Çağrı Toraman and Süha Kağan Köse and Burak Aktaş and Mehmet Can Baytekin and Bilge Kaan Görür}, year={2026}, eprint={2602.03693}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2602.03693}, }
- 1OCRTurk: A Comprehensive OCR Benchmark for Turkish中东技术大学·计算机工程系; 都灵理工大学; Roketsan公司·人工智能技术部门 · 2026年


