t22000t/anonymization-before-after
收藏资源简介:
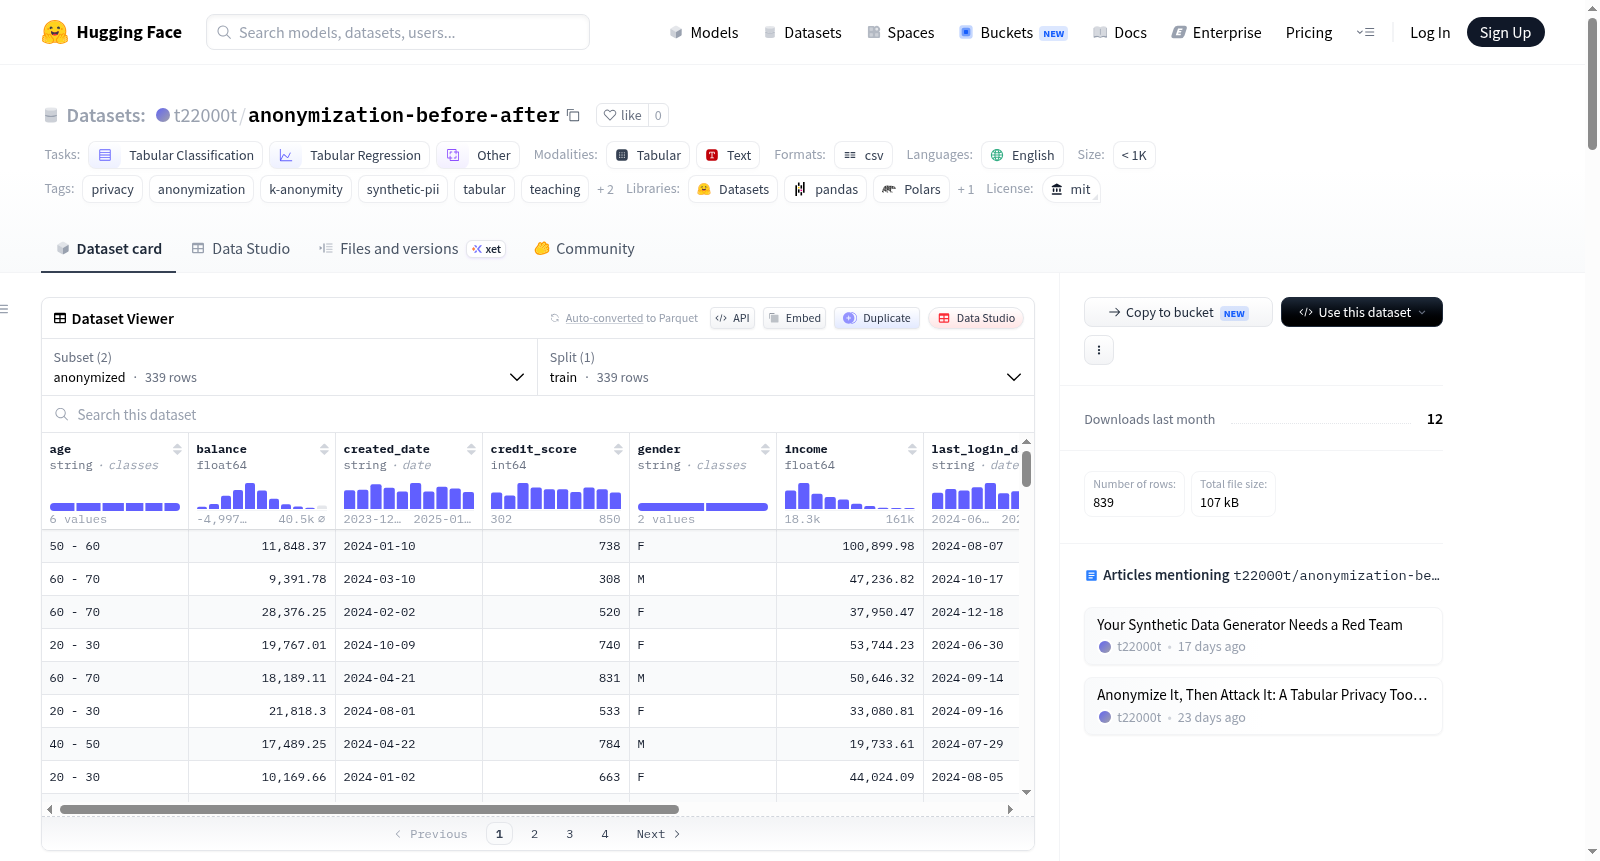
这是一个小型配对表格数据集,展示了相同记录在10步匿名化流程前后的对比。数据集包含两个配置:raw(原始数据)和anonymized(匿名化后数据)。原始数据包含500行、16列,其中包含合成个人身份信息(PII),如姓名、电子邮件、电话号码和国家ID,但这些信息完全是模板化生成的,不代表任何真实个体。匿名化后数据包含339行、10列,通过删除直接标识符和指纹列、对年龄进行分箱、对区域进行类别合并(保留前6个,其余归为其他)、对数值字段注入乘性噪声、对日期进行HMAC确定性偏移等操作,实现了k-匿名性(k≥5)。该数据集可用于隐私概念教学、匿名化工具包基准测试、红队/成员推理实验的验证输入,以及合成数据生成器的完整性检查。数据集基于MIT许可证发布。
A small paired tabular dataset showing the same records before and after a 10-step anonymization pipeline. It includes two configurations: raw (original data) and anonymized (anonymized data). The raw data contains 500 rows and 16 columns with synthetic personally identifiable information (PII), such as names, emails, phone numbers, and national IDs, all generated from templates and not representing any real individuals. The anonymized data contains 339 rows and 10 columns, achieved by removing direct identifiers and fingerprint columns, banding age into ranges, collapsing rare region categories to Other (top-6 kept), injecting multiplicative noise into numeric fields, applying HMAC-deterministic offsets to dates, and enforcing k-anonymity (k≥5). The dataset is useful for teaching privacy concepts, benchmarking anonymization toolkits, sanity-checking inputs for red-team/membership-inference experiments, and validating synthetic data generators. It is released under the MIT license.