Language Table
收藏资源简介:
Interactive Language Dataset 是由谷歌机器人团队创建的一个大规模实时交互语言指令数据集,旨在推动机器人在真实世界中通过自然语言指令进行实时交互和操作的研究。该数据集包含约 60 万个语言标注的轨迹,涵盖模拟和真实场景,是目前同类数据集中规模最大的,比先前的数据集大一个数量级。数据集内容丰富,每个轨迹包含机器人状态、动作输入、工作空间图像以及自然语言指令等多模态信息。其中,语言指令通过众包标注的方式生成,涵盖了从简单操作到复杂多步任务的多样化指令。数据集的创建过程结合了高吞吐量的远程操作数据采集和事件选择性事后语言标注技术,确保数据的多样性和实用性。该数据集的应用领域广泛,主要用于研究机器人如何理解和执行人类通过自然语言实时发出的多样化指令,解决复杂环境中的视觉、语言和运动控制问题。此外,它还支持多机器人同时控制的研究,为未来人机协作提供了新的可能性。
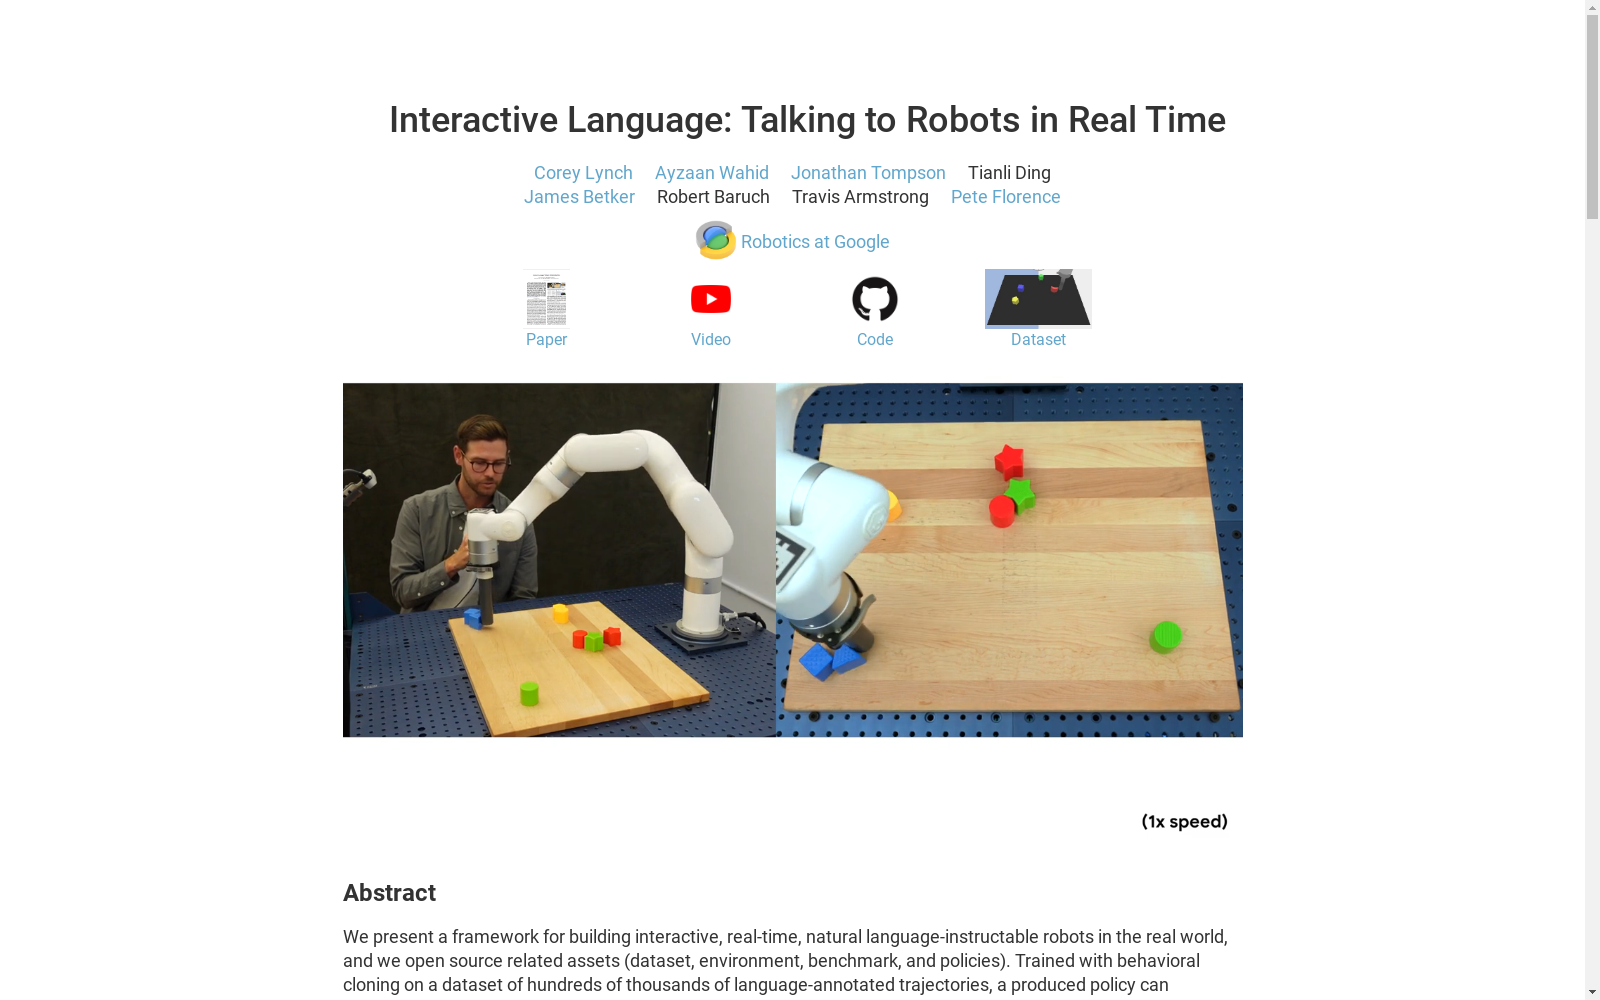
The Interactive Language Dataset is a large-scale real-time interactive language instruction dataset created by the Google Robotics Team, aiming to advance research on robots' real-time interaction and operation via natural language instructions in the physical world. The dataset contains approximately 600,000 linguistically annotated trajectories, covering both simulated and real-world scenarios, and is currently the largest dataset of its kind, being an order of magnitude larger than previous datasets. The dataset is rich in content, with each trajectory containing multimodal information including robot states, action inputs, workspace images, and natural language instructions. The language instructions are generated via crowdsourced annotation, covering diverse instructions ranging from simple operations to complex multi-step tasks. The dataset's creation process combines high-throughput remote operation data collection and event-selective post-hoc linguistic annotation technologies to ensure the diversity and practicality of the data. The dataset has a wide range of application scenarios, mainly used for researching how robots understand and execute diverse instructions issued by humans in real time via natural language, and solving problems of vision, language and motion control in complex environments. In addition, it also supports research on simultaneous control of multiple robots, providing new possibilities for future human-robot collaboration.