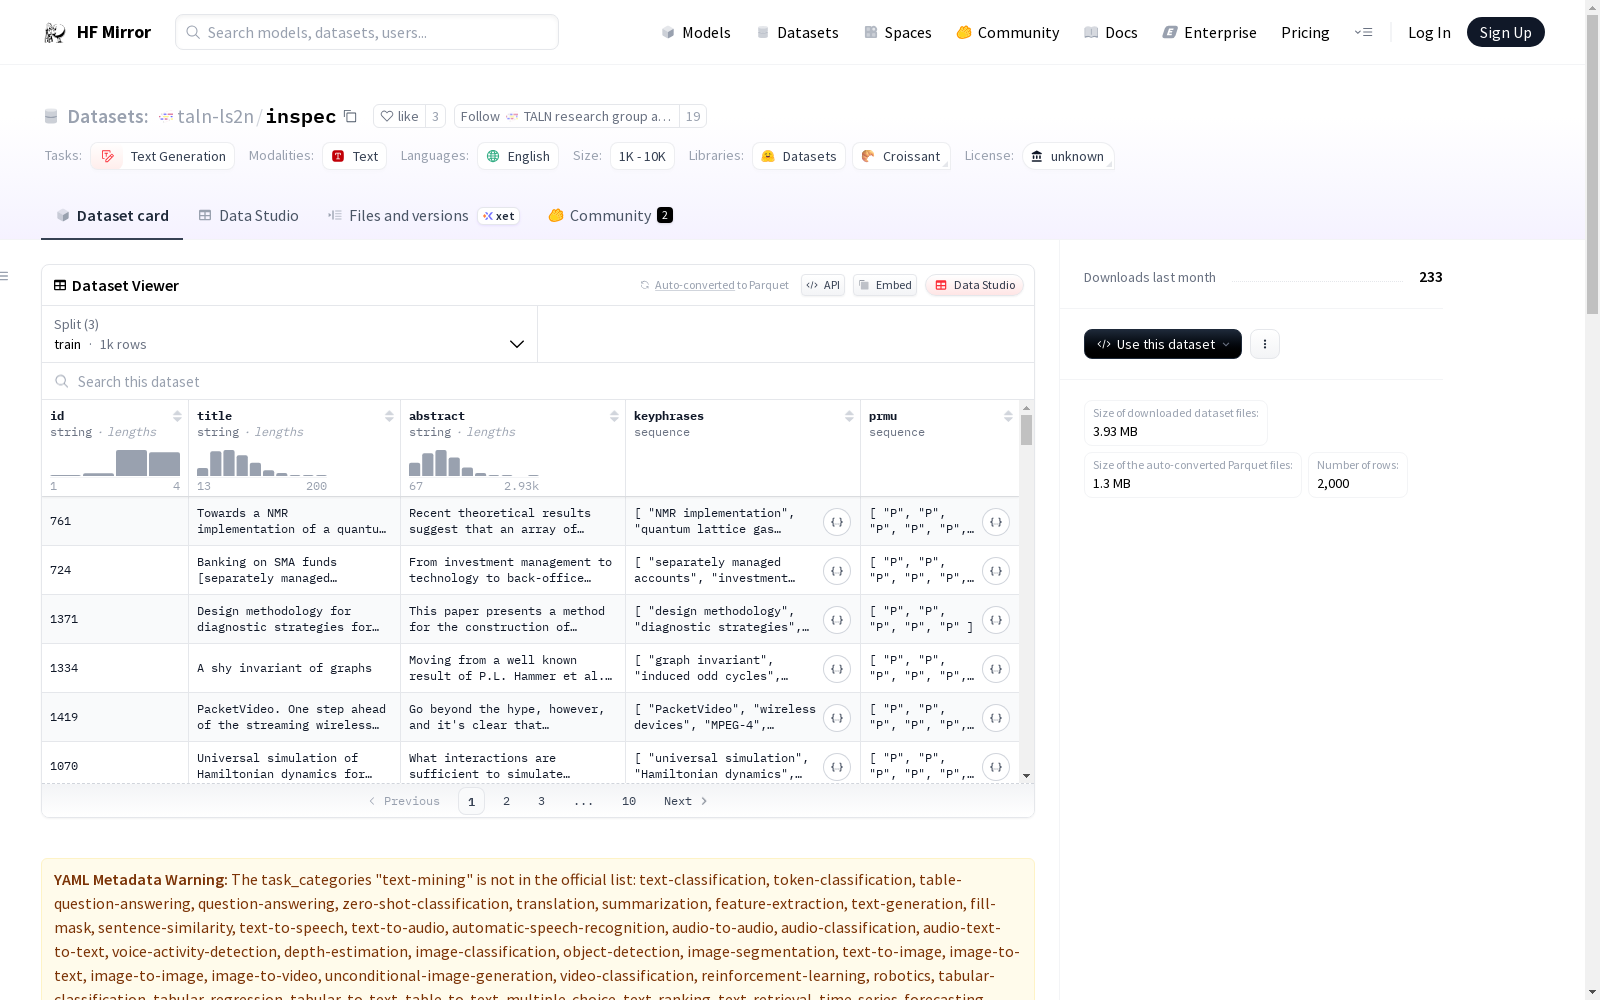
taln-ls2n/inspec
收藏资源简介:
Inspec是一个用于基准测试关键词提取和生成模型的数据集。该数据集包含2000篇从Inspec数据库中收集的科学论文摘要,关键词由专业索引员在不受控环境中标注。数据集分为训练、验证和测试三个部分,并提供了每个部分的文档数量、单词数量、关键词数量及其分类统计。数据集的文本预处理使用了spacy和nltk工具,关键词分类采用了PRMU方案。
Inspec is a dataset for benchmarking keyword extraction and generation models. This dataset contains 2000 scientific paper abstracts collected from the Inspec database, with keywords annotated by professional indexers in an unconstrained environment. The dataset is split into three subsets: training, validation, and test, and provides the counts of documents, words, and keywords, as well as their categorical statistics for each subset. The text preprocessing of the dataset uses spaCy and NLTK tools, and the PRMU scheme is employed for keyword classification.
Inspec Benchmark Dataset for Keyphrase Generation
概述
Inspec是一个用于基准测试关键短语提取和生成模型的数据集。该数据集包含2,000篇科学论文的摘要,来自Inspec数据库。关键短语由专业索引员在非受控环境中标注,不限于主题词表条目。
内容和统计
数据集分为三个部分:
| Split | # documents | #words | # keyphrases | % Present | % Reordered | % Mixed | % Unseen |
|---|---|---|---|---|---|---|---|
| Train | 1,000 | 141.7 | 9.79 | 78.00 | 9.85 | 6.22 | 5.93 |
| Validation | 500 | 132.2 | 9.15 | 77.96 | 9.82 | 6.75 | 5.47 |
| Test | 500 | 134.8 | 9.83 | 78.70 | 9.92 | 6.48 | 4.91 |
数据集包含以下字段:
- id: 文档的唯一标识符。
- title: 文档标题。
- abstract: 文档摘要。
- keyphrases: 参考关键短语列表。
- prmu: 参考关键短语的<u>P</u>resent-<u>R</u>eordered-<u>M</u>ixed-<u>U</u>nseen类别列表。
参考文献
- Hulth, A. (2003). Improved automatic keyword extraction given more linguistic knowledge. In Proceedings of the 2003 Conference on Empirical Methods in Natural Language Processing, pages 216-223.
- Boudin, F., & Gallina, Y. (2021). Redefining Absent Keyphrases and their Effect on Retrieval Effectiveness. In Proceedings of the 2021 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, pages 4185–4193, Online. Association for Computational Linguistics.