FatimahEmadEldin/Yemeni-Speech-Emotion-Dataset
收藏资源简介:
YSED — 也门语音情感数据集(音频分类重新打包版本)是一个包含1432个音频片段的也门阿拉伯语情感分类数据集,覆盖5种情绪类别:愤怒、恐惧、快乐、中立和悲伤。音频为48 kHz立体声.wav格式,中位持续时间约为2.7秒。数据集来源于71名也门志愿者(37男,34女),年龄在15-45岁之间,经过6名评委验证,Fleiss Kappa = 0.9。数据集采用80/10/10的比例进行分层训练/验证/测试分割,确保每个分割的情绪比例相同。该数据集适用于情感分类任务,但不适用于TTS或ASR任务。需要注意的是,数据集为也门方言,不是现代标准阿拉伯语(MSA),且分割未考虑说话者独立性,录音条件也有所不同。
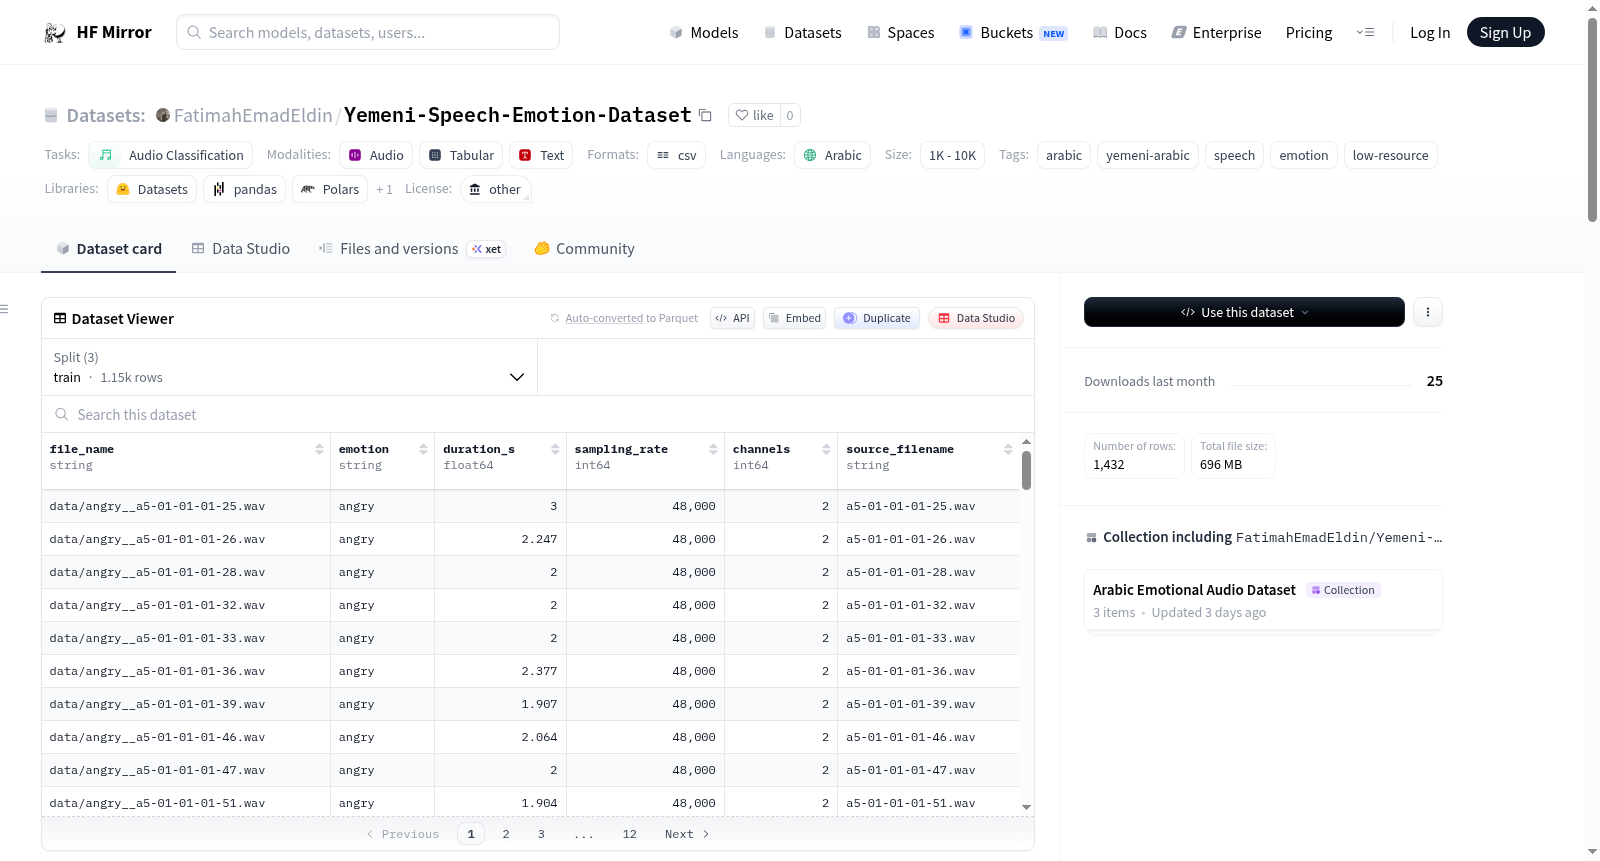
YSED — Yemeni Speech Emotion Dataset (audio-classification repackaging) is a clean repackaging of YSED with a `metadata.csv` and stratified train/validation/test splits, for emotion classification on Yemeni Arabic. It contains 1432 audio clips across 5 emotion classes: angry, fearful, happy, neutral, sad. The audio is in 48 kHz stereo `.wav` format with a median duration of ~2.7 s. The dataset was collected from 71 Yemeni volunteers (37 M, 34 F), aged 15–45, and validated by 6 judges with Fleiss Kappa = 0.9. The dataset uses an 80/10/10 stratified split by emotion, ensuring the same emotion proportions in each split. This dataset is intended for emotion classification tasks, not for TTS or ASR. Note that the dataset is in the Yemeni dialect, not MSA, and the splits are not speaker-disjoint, with varying recording conditions.