ScenePoint
收藏资源简介:
ScenePoint是由伦敦帝国学院构建的大规模点图数据集,专为三维视觉语言学习设计。该数据集整合了ScanNet、3RScan和ARKitScenes三大真实场景数据集,包含6,562个房间级场景及100万单视图点图,通过VGGT模型将二维图像转化为三维点图结构。数据集采用多视图采样与LLM生成描述技术,构建了点图-图像-文本三元组对齐数据,主要应用于三维场景理解、视觉问答和具身导航等领域,旨在解决三维表征学习中预训练先验稀缺和数据匮乏的核心挑战。
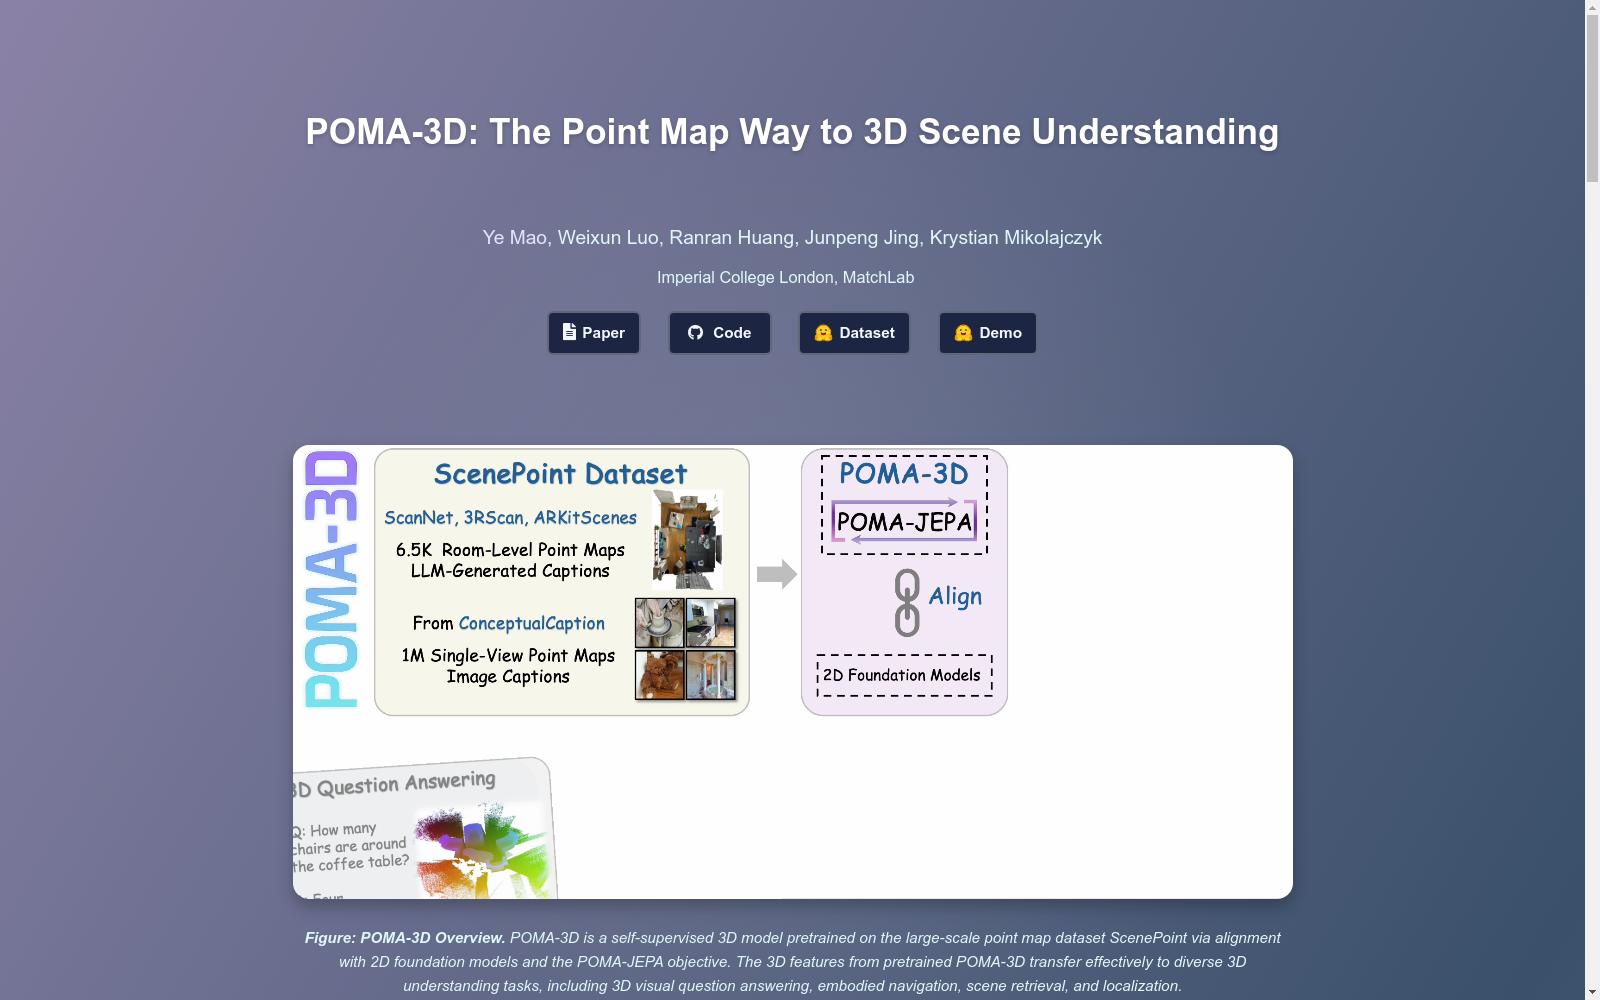
ScenePoint is a large-scale point graph dataset developed by Imperial College London specifically for 3D vision-language learning. This dataset integrates three real-world scene datasets, namely ScanNet, 3RScan, and ARKitScenes, containing 6,562 room-level scenes and 1 million single-view point graphs. It converts 2D images into 3D point graph structures via the VGGT model. By adopting multi-view sampling and LLM-generated description technologies, it constructs aligned triplet data of point graphs, images and texts. It is mainly applied in fields such as 3D scene understanding, visual question answering, and embodied navigation, aiming to address the core challenges of scarce pre-training priors and insufficient data in 3D representation learning.
POMA-3D: The Point Map Way to 3D Scene Understanding
数据集概述
POMA-3D是首个基于多视角点图的自监督3D表示学习模型,通过点图方式实现3D场景理解。
核心特征
- 基于点图的自监督3D表示学习
- 通过视图到场景对齐策略将2D先验知识转移到3D
- 引入POMA-JEPA联合嵌入预测架构
- 仅使用几何输入(3D坐标)
数据集构成
- ScenePoint点图数据集:包含6.5K房间级RGB-D场景和1M 2D图像场景
- 用于大规模POMA-3D预训练
应用任务
- 3D视觉问答(ScanQA、SQA3D、Hypo3D)
- 具身导航(MSNN)
- 场景检索(ScanRefer、Nr3D、Sr3D)
- 具身定位
性能表现
3D VQA与具身导航
- POMA-3D specialist在ScanQA上EM@1达22.3%,EM@10达52.3%
- 在SQA3D上EM@1达51.1%,EM@10达91.2%
- 在MSNN四向导航中达40.4%,八向导航中达21.2%
场景检索
- 在ScanRefer上R@1-1达9.31%,R@1-5达27.9%
- 在Nr3D上R@1-1达8.10%,R@1-5达15.7%
- 在Sr3D上R@1-1达3.89%,R@1-5达14.0%
技术优势
- 解决3D表示学习中预训练先验稀缺和数据有限的问题
- 在专业模型和通用模型中都表现出强大的骨干网络能力
- 在多个3D理解任务中实现仅使用几何输入的优异性能