DataikuNLP/kiji-pii-training-data
收藏资源简介:
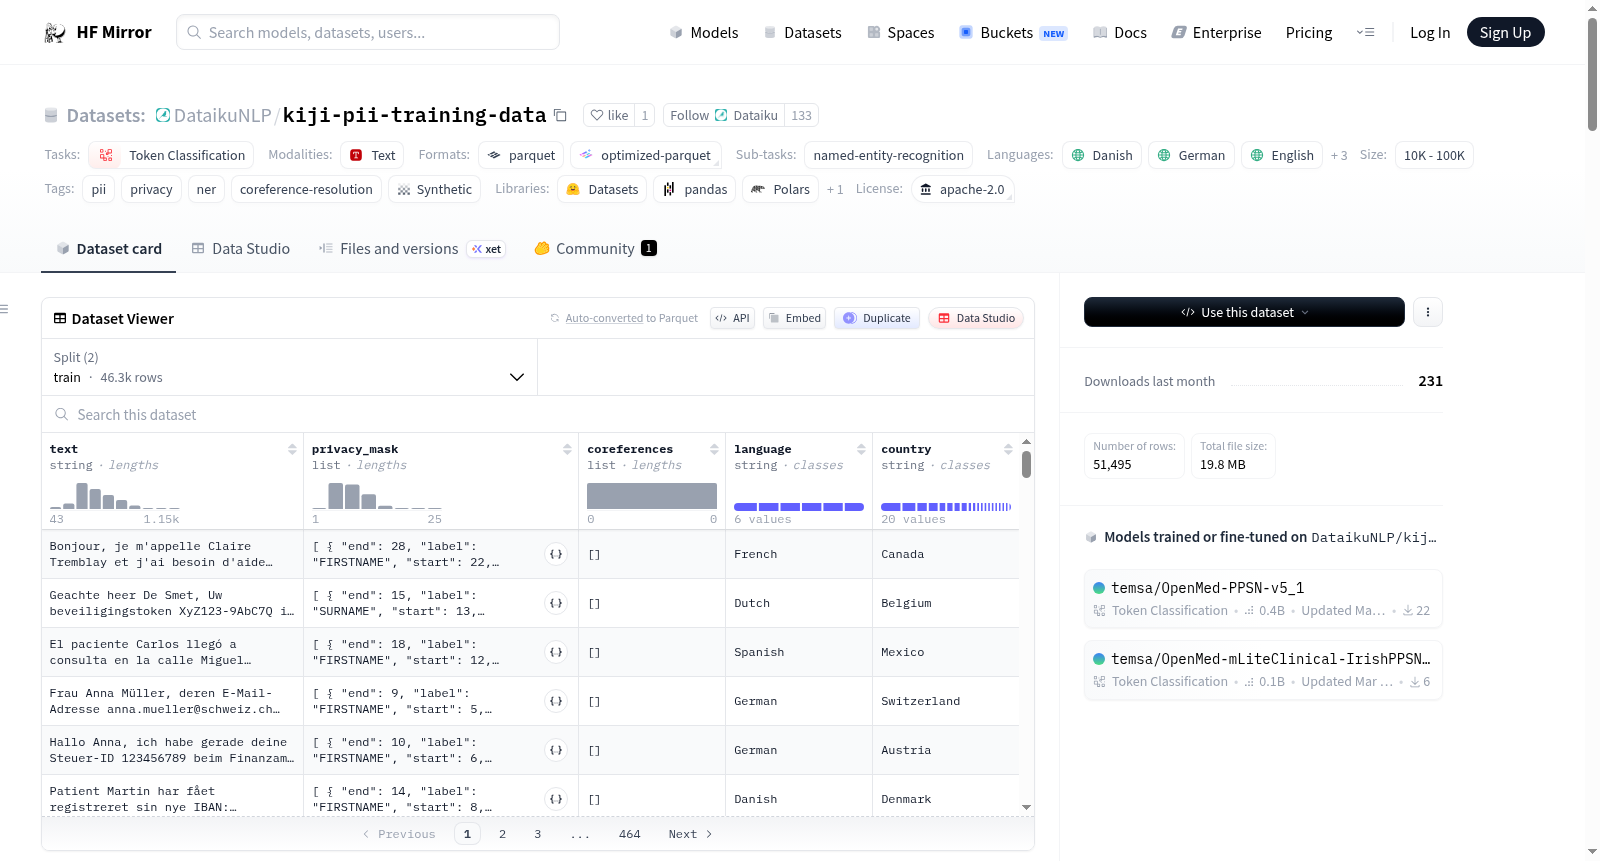
Kiji PII检测训练数据是一个合成的多语言数据集,用于训练具有令牌级实体注释和共指消解的PII(个人可识别信息)检测模型。数据集包含51,495个样本(训练集46,345,测试集5,150),涵盖6种语言(英语、丹麦语、荷兰语、法语、西班牙语、德语)和20个国家。标注了26种PII实体类型,总计397,441个实体注释(平均每个样本7.7个)。每个样本包含自然语言文本、PII实体注释、共指消解簇、文本语言和国家上下文。数据集适用于令牌分类任务,特别是命名实体识别(NER)和共指消解。数据通过LLM生成,包含结构化输出,但均为合成数据,可能不完全反映真实世界文本的实体分布。
Synthetic multilingual dataset for training PII (Personally Identifiable Information) detection models with token-level entity annotations and coreference resolution. The dataset contains 51,495 samples (train: 46,345, test: 5,150) across 6 languages (English, Danish, Dutch, French, Spanish, German) and 20 countries. It features 26 PII entity types with 397,441 total entity annotations (avg 7.7 per sample). Each sample includes natural language text with embedded PII, entity annotations, coreference clusters, language, and country context. Designed for token-classification tasks (NER and coreference resolution), the data is synthetically generated using LLMs with structured outputs, though it may not perfectly match real-world entity distributions.