local-deep-research/ldr-benchmarks
收藏资源简介:
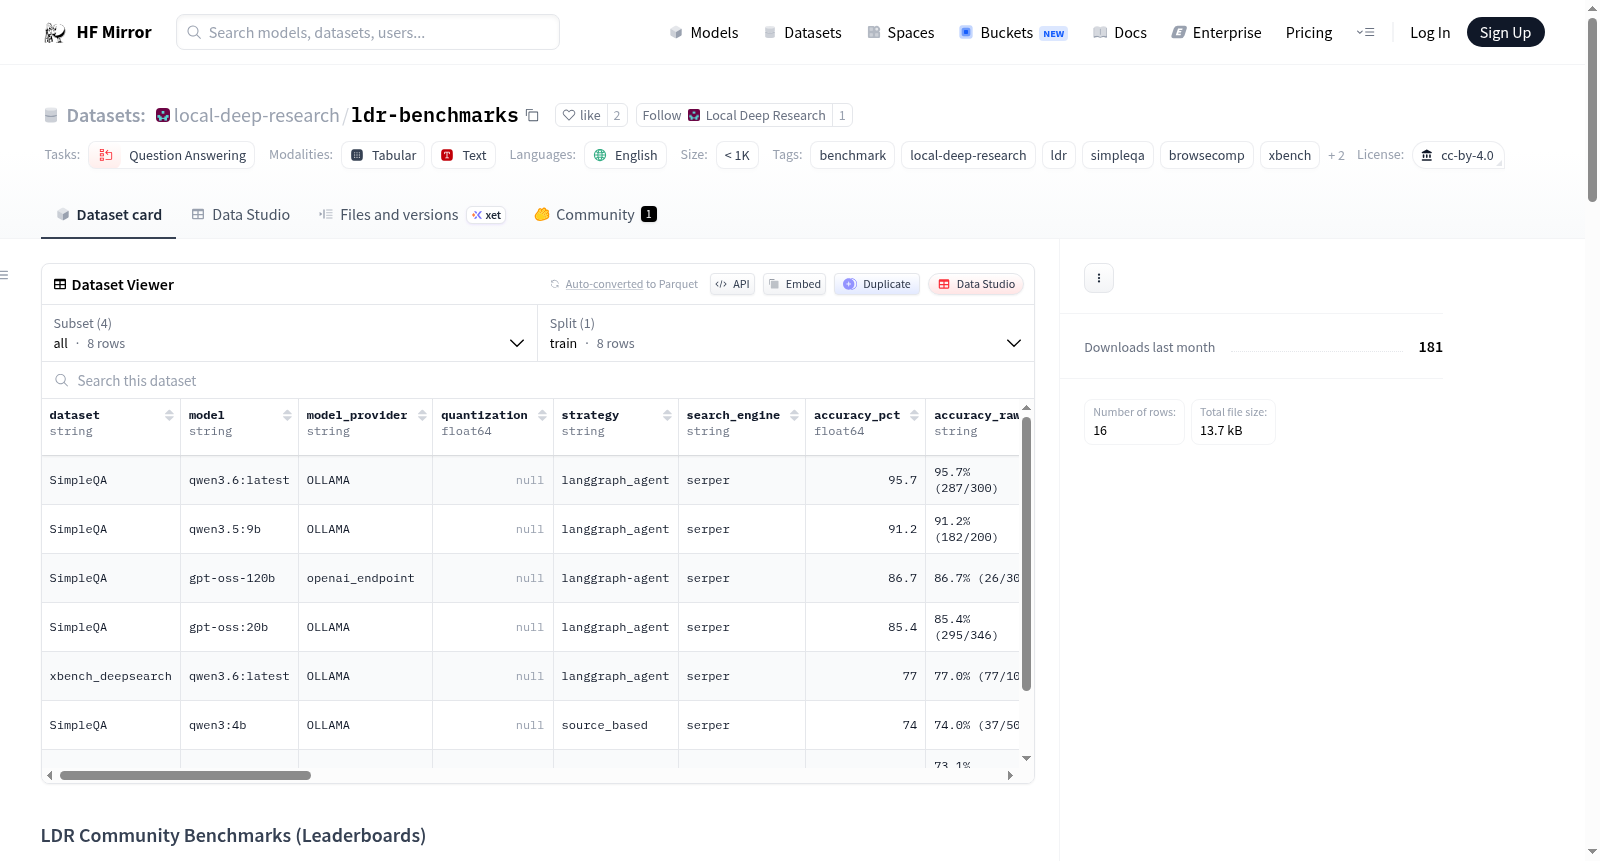
--- license: cc-by-4.0 task_categories: - question-answering language: - en tags: - benchmark - local-deep-research - ldr - simpleqa - browsecomp - xbench - rag - search pretty_name: LDR Community Benchmarks size_categories: - n<1K configs: - config_name: all data_files: leaderboards/all.csv default: true - config_name: simpleqa data_files: leaderboards/simpleqa.csv - config_name: browsecomp data_files: leaderboards/browsecomp.csv - config_name: xbench-deepsearch data_files: leaderboards/xbench-deepsearch.csv --- # LDR Community Benchmarks (Leaderboards) Aggregated leaderboards for Local Deep Research (LDR) community benchmark runs against SimpleQA, BrowseComp, and xbench-DeepSearch. ## 👉 Submit results, read raw YAMLs, open PRs: ## **[github.com/LearningCircuit/ldr-benchmarks](https://github.com/LearningCircuit/ldr-benchmarks)** This Hugging Face dataset hosts **only the aggregated CSV leaderboards**. It is regenerated automatically on every merge to `main` in the GitHub repo above. Each CSV row represents one benchmark run (one strategy from one YAML submission). ## Why the split? - **GitHub** is the source of truth for raw YAML submissions, PR review, CI validation, and leaderboard regeneration. - **Hugging Face** renders the aggregated CSVs in its Dataset Viewer and makes the leaderboards discoverable inside the ML community. Raw per-run YAMLs — including configuration details, notes, and (where permitted by the benchmark's sharing policy) per-question examples — live in the GitHub repo under `results/`. ## Benchmarks covered - **SimpleQA** — OpenAI, MIT-licensed. Full per-question examples allowed in raw YAMLs on GitHub. - **BrowseComp** — OpenAI, encrypted dataset with canary string. Only aggregate metrics are accepted (no per-question examples in raw YAMLs). - **xbench-DeepSearch** — xbench team, encrypted dataset. Only aggregate metrics are accepted (no per-question examples in raw YAMLs). See the GitHub repo's README for the full sharing policy. ## Leaderboard columns Each CSV row contains: `dataset, model, model_provider, quantization, strategy, search_engine, accuracy_pct, accuracy_raw, correct, total, iterations, questions_per_iteration, avg_time_per_question, total_tokens_used, temperature, context_window, max_tokens, hardware_gpu, hardware_ram, hardware_cpu, evaluator_model, evaluator_provider, ldr_version, date_tested, contributor, notes, source_file` The `source_file` column points at the raw YAML in the GitHub repo. ## Configs Use the dropdown at the top of the Dataset Viewer to switch between: - `all` — every run, all benchmarks combined (default) - `simpleqa` — SimpleQA runs only - `browsecomp` — BrowseComp runs only - `xbench-deepsearch` — xbench-DeepSearch runs only ## Considerations for using the data This is a community-submitted leaderboard, not a controlled experiment. Keep these caveats in mind when interpreting results: - **Self-reported.** Runs are submitted by contributors. CI validates schema and flags obvious issues, but the runs themselves are not independently re-executed. - **Evaluator bias.** Many submissions use an LLM grader (default is Claude 3.7 Sonnet via OpenRouter). LLM evaluators have non-trivial error rates; a manual audit of ~200 SimpleQA questions commonly surfaces one or two grading mistakes. - **Small sample sizes.** Many runs use 50–200 questions. Confidence intervals at that scale are wide (roughly ±5–7 percentage points at n=200). Small differences between rows are usually not significant. - **Timing is environment-dependent.** `avg_time_per_question` depends on hardware, network latency, search engine responsiveness, and model server load. - **Contamination risk.** SimpleQA is publicly distributed and may appear in some models' training data. BrowseComp and xbench mitigate this with encryption, but older model generations may still be contaminated. - **Strategy semantics drift.** LDR strategies evolve between versions. Prefer comparing runs tagged with the same `ldr_version`. ## Attribution - **SimpleQA** © OpenAI — [MIT License](https://github.com/openai/simple-evals/blob/main/LICENSE) - **BrowseComp** © OpenAI — see the [BrowseComp paper](https://cdn.openai.com/pdf/5e10f4ab-d6f7-442e-9508-59515c65e35d/browsecomp.pdf) and [openai/simple-evals](https://github.com/openai/simple-evals) - **xbench** © xbench team — see [xbench-ai/xbench-evals](https://github.com/xbench-ai/xbench-evals) Plain-text distribution of BrowseComp and xbench questions or answers is prohibited. ## Contributors <!-- CONTRIBUTORS:START --> Thanks to everyone who has contributed benchmark runs: - **LearningCircuit** — 2 submissions - **kwhyte7** — 1 submission <!-- CONTRIBUTORS:END --> ## Citation ```bibtex @misc{ldr_community_benchmarks, title = {LDR Community Benchmarks}, author = {The Local Deep Research community}, year = {2026}, publisher = {Hugging Face / GitHub}, howpublished = {\url{https://huggingface.co/datasets/local-deep-research/ldr-benchmarks}} } ``` ## License This dataset is licensed under [Creative Commons Attribution 4.0 International (CC BY 4.0)](https://creativecommons.org/licenses/by/4.0/). If you use the data in research, publications, or derivative analyses, please cite it using the BibTeX entry above. Individual benchmark datasets (SimpleQA, BrowseComp, xbench) retain their own upstream licenses — see the *Attribution* section.