electricsheepasia/asia-ilo-une-tune-sex-mts-nb-unemployment-by-sex-and-marital-status-thousands
收藏资源简介:
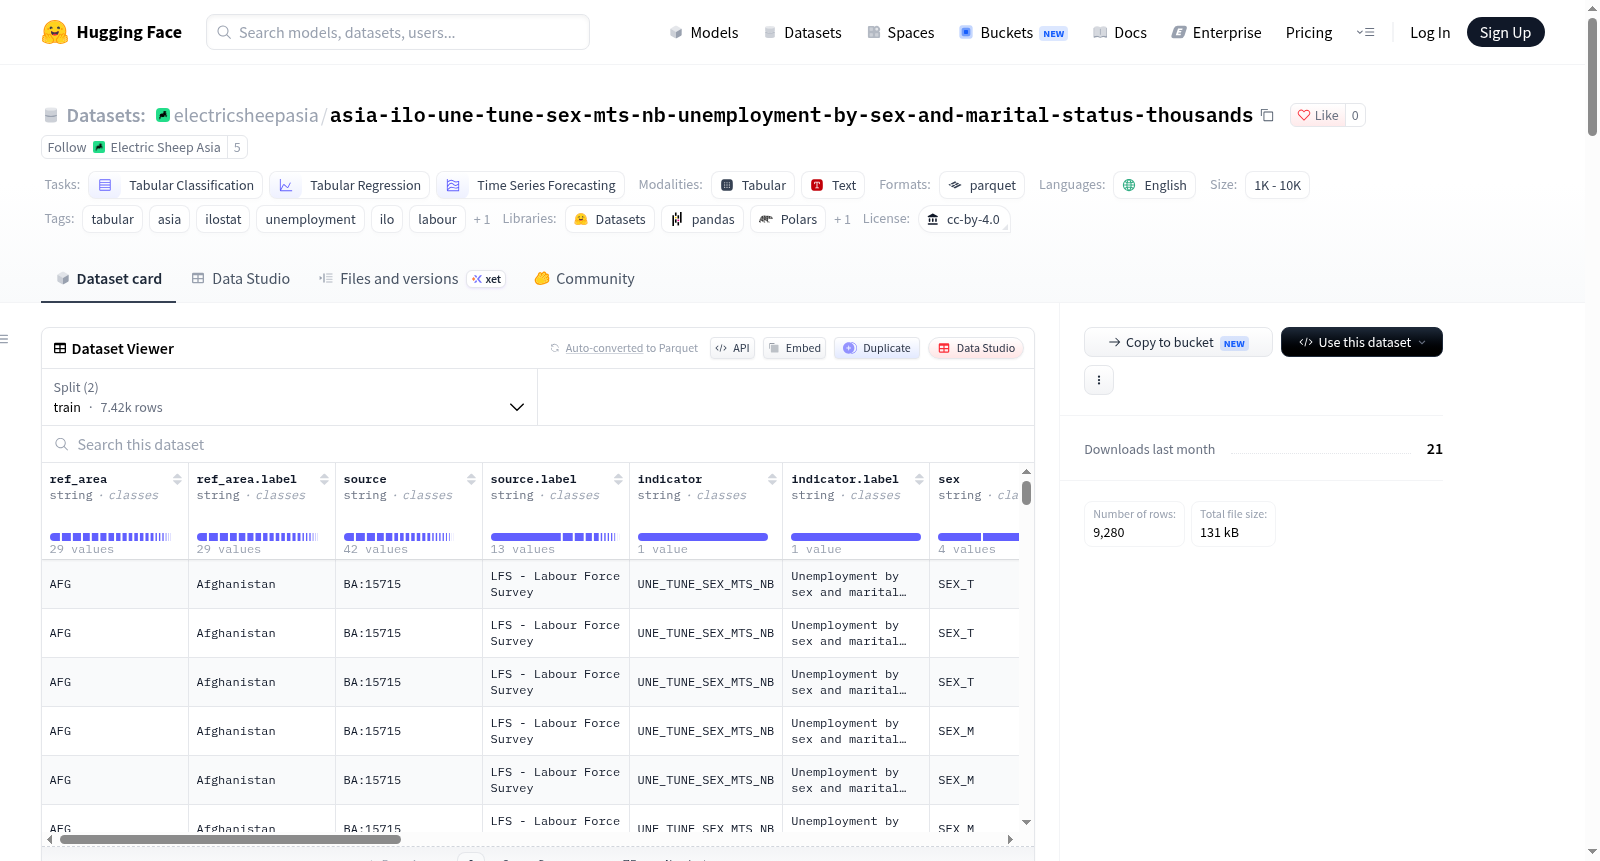
该数据集名为按性别和婚姻状况划分的失业人数(千计)| 亚洲(ILOSTAT),是一个表格型数据集,专注于亚洲国家的失业统计。它包含9,280个观测值,覆盖35个亚洲国家,时间跨度为1970年至2025年,核心指标为UNE_TUNE_SEX_MTS_NB,即按性别和婚姻状况划分的失业人数(以千计)。数据来源于国际劳工组织(ILO)的ILOSTAT数据库,通过API获取并经过处理,以确保数据的权威性和一致性。数据集字段包括国家代码、国家名称、年份、观测值、性别分类(如总人口、男性、女性)、数据来源、观测状态等,并提供了数据质量说明(如年度频率、最佳来源选择)和使用示例(如加载数据、筛选国家、时间序列分析)。该数据集适用于表格分类、回归和时间序列预测等任务,旨在为研究人员和开发者提供机器学习就绪的亚洲劳动力市场数据。
This dataset, titled Unemployment by sex and marital status (thousands) | Asia (ILOSTAT), is a tabular dataset focused on unemployment statistics for Asian countries. It contains 9,280 observations across 35 Asia countries, spanning the years 1970 to 2025, with one core indicator: UNE_TUNE_SEX_MTS_NB, which represents unemployment by sex and marital status in thousands. The data is sourced from the International Labour Organization (ILO) ILOSTAT database, retrieved via API and processed for consistency. The dataset includes fields such as country code, country name, year, observed value, sex disaggregation (e.g., total, male, female), data source, observation status, and more, along with data quality notes (e.g., annual frequency, best source selection) and usage examples (e.g., loading data, filtering by country, time-series analysis). It is suitable for tasks like tabular classification, regression, and time-series forecasting, and is designed to provide machine learning-ready labor market data for Asia.