ZHIYII/Notion_Entropy_Action_SFT_swift_trace_gpt5_quality_top50
收藏资源简介:
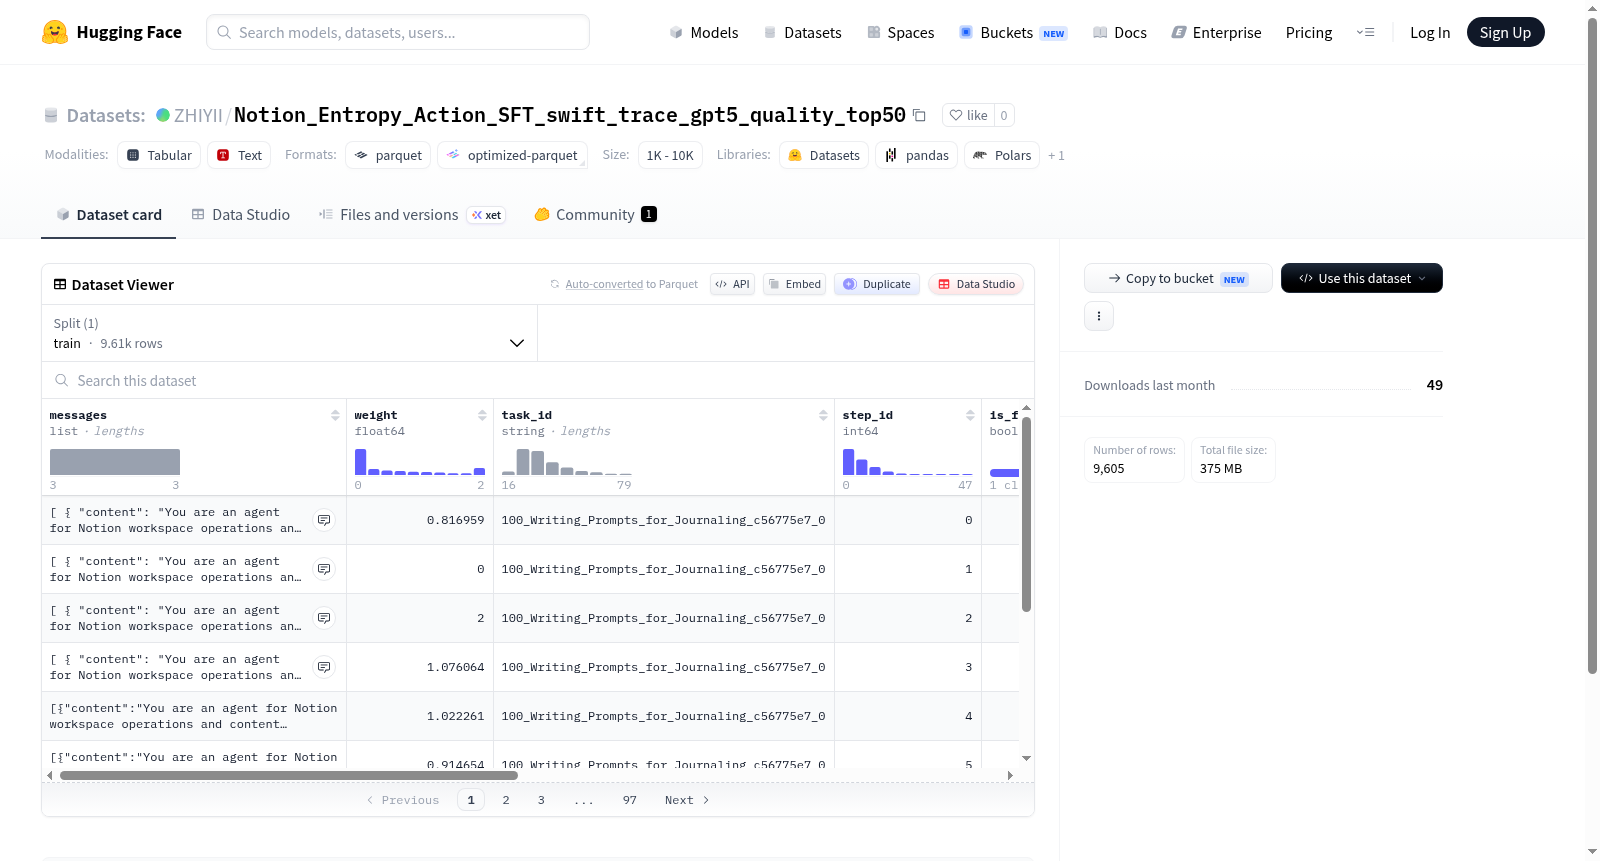
该数据集是一个用于训练或分析的人工智能对话数据集,包含9605个训练示例。每个示例由多个特征组成:messages(包含content和role字段的列表,表示对话内容)、weight(权重值,float64类型)、task_id(任务标识符,string类型)、step_id(步骤编号,int64类型)、is_final_answer(是否为最终答案,bool类型)、is_error_step(是否为错误步骤,bool类型)、raw_advantage(原始优势值,float64类型)、l_prefix(前缀值,float64类型)、nonnegative_advantage(非负优势值,float64类型)、info_gain(信息增益,float64类型)和use_for_training(是否用于训练,bool类型)。数据集总大小约为377MB,下载大小约为375MB,仅包含一个训练分割。
This dataset is an AI dialogue dataset for training or analysis, containing 9605 training examples. Each example consists of multiple features: messages (a list with content and role fields representing dialogue content), weight (a weight value, float64 type), task_id (task identifier, string type), step_id (step number, int64 type), is_final_answer (whether it is the final answer, bool type), is_error_step (whether it is an error step, bool type), raw_advantage (raw advantage value, float64 type), l_prefix (prefix value, float64 type), nonnegative_advantage (non-negative advantage value, float64 type), info_gain (information gain, float64 type), and use_for_training (whether used for training, bool type). The total dataset size is approximately 377MB, with a download size of about 375MB, and it includes only a training split.